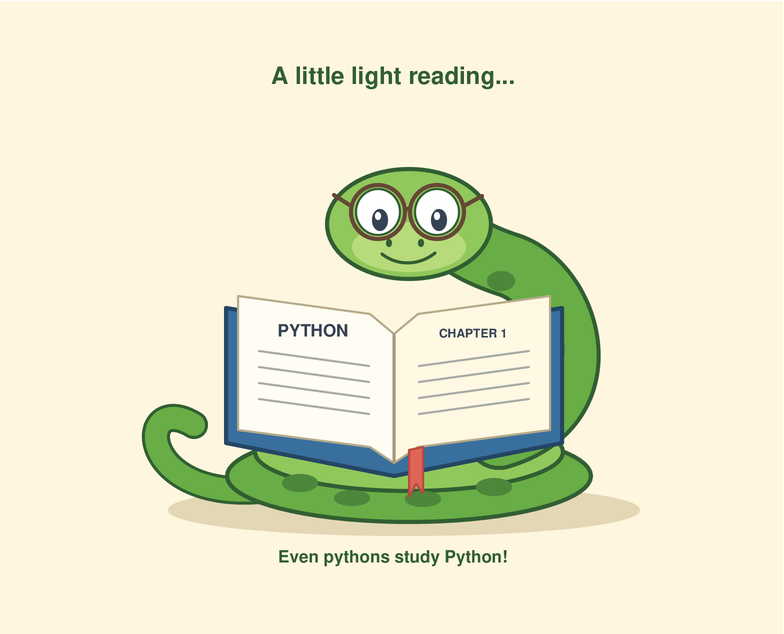
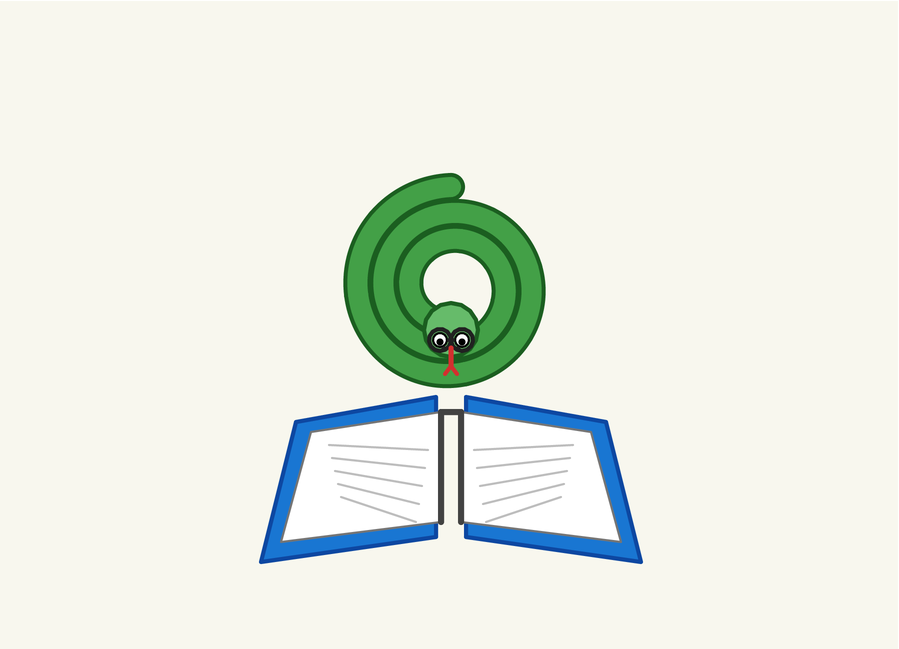
We asked DaisyRose 27B to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
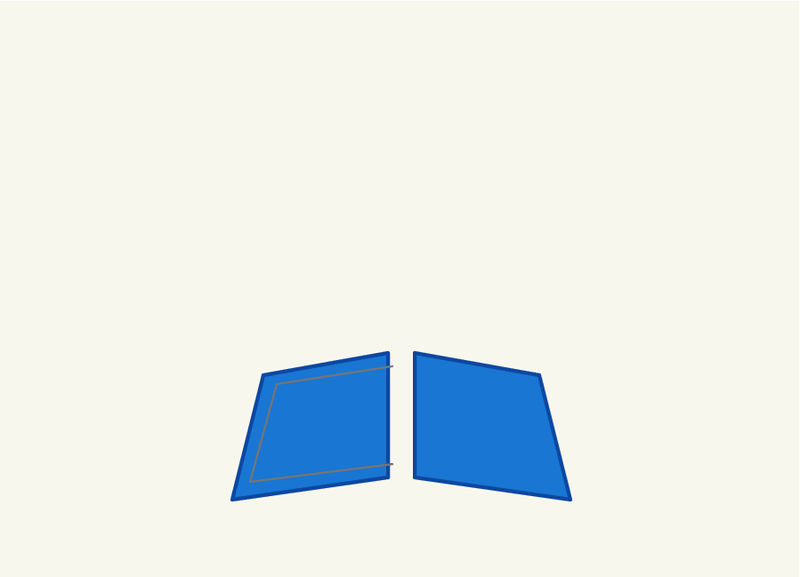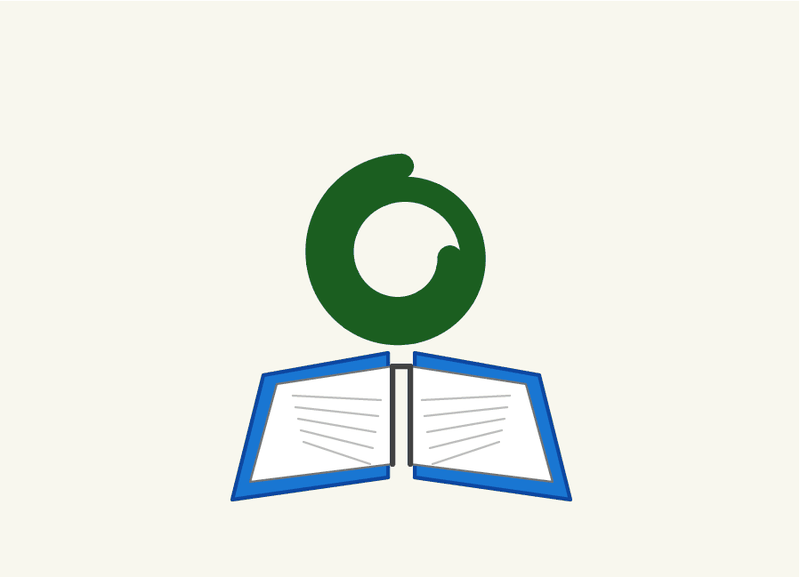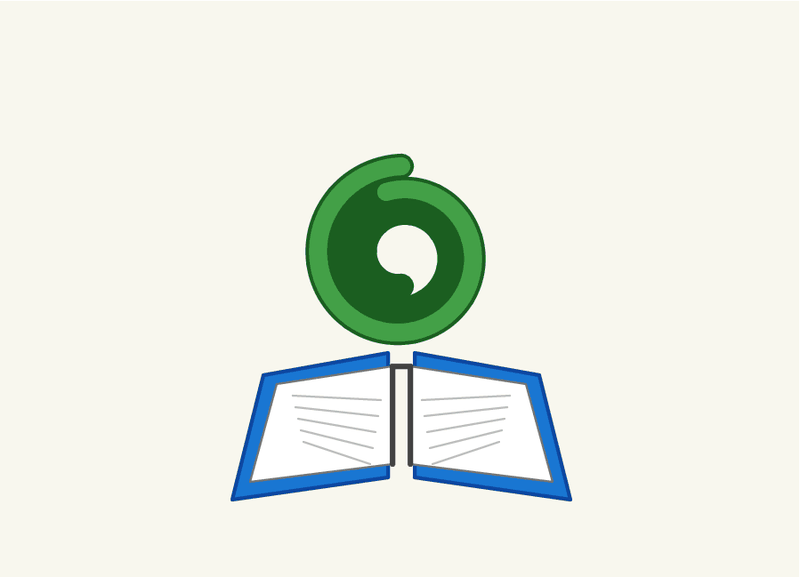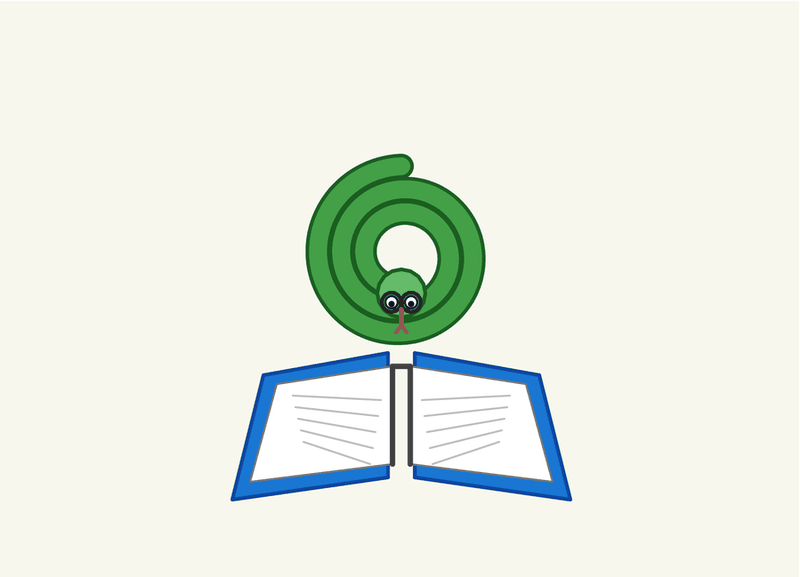
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Unrelated edits | Add an --ext option to a 50-line script. |
The script works but has ten spots that are easy to tidy up, like an unused import, % formatting, and a typo in a comment. None of them is part of the task. We list the ones the model changed anyway. Inspect the diff to see whether those changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 1766 drawing commands, 220 lines of code |
| How modern its Python is | Python 3.10 (2021) | pinned by datetime_utc. Newest feature used: Python 3.11 |
| Modern idioms | 5 of 12 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.14 | the reply is quoted below |
| Unrelated edits | 0 of 10 | left every unrelated spot alone |
| Spots a made-up function? | Caught it | said the function doesn’t exist and offered a real alternative |
| Reasoning effort | default | 75.7k thinking tokens over all five tasks |
| Cost | $0.27 | for all 5 tasks, as billed by the API |
| Response time | 12 min 10 s | 81.1k output tokens, 1 empty reply retried |
The run: radixark/daisyrose-27b via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import math
import turtle

# -------------------------------
# Setup
# -------------------------------
screen = turtle.Screen()
screen.title("Python reading a book")
screen.setup(900, 650)
screen.bgcolor("#f8f7ee")

t = turtle.Turtle()
t.speed(0)
t.hideturtle()
t.penup()


# -------------------------------
# Helper drawing functions
# -------------------------------
def line(x1, y1, x2, y2, color="black", width=3):
    """Draw a line from (x1, y1) to (x2, y2)."""
    t.pencolor(color)
    t.pensize(width)
    t.penup()
    t.goto(x1, y1)
    t.pendown()
    t.goto(x2, y2)


def polygon(points, fill=None, outline="black", width=3):
    """Draw a polygon from a list of (x, y) points."""
    t.pencolor(outline)
    t.pensize(width)

    t.penup()
    t.goto(points[0])
    t.pendown()

    if fill:
        t.fillcolor(fill)
        t.begin_fill()

    for point in points[1:]:
        t.goto(point)

    t.goto(points[0])

    if fill:
        t.end_fill()


def circle(x, y, radius, fill=None, outline="black", width=3):
    """Draw a circle centered at (x, y)."""
    t.pencolor(outline)
    t.pensize(width)

    t.penup()
    t.goto(x, y - radius)
    t.setheading(0)
    t.pendown()

    if fill:
        t.fillcolor(fill)
        t.begin_fill()

    t.circle(radius)

    if fill:
        t.end_fill()


def polyline(points, color="black", width=3):
    """Draw a connected line through a list of points."""
    t.pencolor(color)
    t.pensize(width)

    t.penup()
    t.goto(points[0])
    t.pendown()

    for point in points[1:]:
        t.goto(point)


# -------------------------------
# Draw the book
# -------------------------------
def draw_book():
    # Blue covers of an open book
    left_cover = [
        (-15, -210),
        (-190, -235),
        (-155, -95),
        (-15, -70)
    ]

    right_cover = [
        (15, -210),
        (190, -235),
        (155, -95),
        (15, -70)
    ]

    polygon(left_cover, fill="#1976d2", outline="#0d47a1", width=4)
    polygon(right_cover, fill="#1976d2", outline="#0d47a1", width=4)

    # White pages
    left_page = [
        (-10, -195),
        (-170, -215),
        (-140, -105),
        (-10, -85)
    ]

    right_page = [
        (10, -195),
        (170, -215),
        (140, -105),
        (10, -85)
    ]

    polygon(left_page, fill="#ffffff", outline="#757575", width=2)
    polygon(right_page, fill="#ffffff", outline="#757575", width=2)

    # Center fold / spine lines
    line(-10, -85, 10, -85, "#424242", 6)
    line(-10, -85, -10, -195, "#424242", 6)
    line(10, -85, 10, -195, "#424242", 6)

    # Fake text lines on the pages
    for i in range(1, 6):
        y = -105 - i * 15

        line(
            -125 + i * 3,
            y + i * 2,
            -20 - i * 3,
            y - i * 3,
            "#bdbdbd",
            2
        )

        line(
            20 + i * 3,
            y - i * 3,
            125 - i * 3,
            y + i * 2,
            "#bdbdbd",
            2
        )


# -------------------------------
# Draw the python/snake
# -------------------------------
def draw_snake():
    # Spiral parameters for the snake body
    cx, cy = 0, 40
    r_start, r_end = 100, 35
    turns = 2.5

    # End the spiral at the bottom so the head faces downward
    end_angle = -math.pi / 2
    total_angle = turns * 2 * math.pi
    start_angle = end_angle - total_angle

    points = []
    steps = 800

    for i in range(steps + 1):
        frac = i / steps
        theta = start_angle + frac * total_angle
        r = r_start + (r_end - r_start) * frac

        x = cx + r * math.cos(theta)
        y = cy + r * math.sin(theta)

        points.append((x, y))

    # Draw a dark outline, then a green body over it
    polyline(points, color="#1b5e20", width=28)
    polyline(points, color="#43a047", width=20)

    # Head position: end of the spiral
    hx, hy = points[-1]

    # Draw the head
    circle(hx, hy - 8, 27, fill="#66bb6a", outline="#1b5e20", width=4)

    # Eyes looking down at the book
    eye_y = hy - 18

    circle(hx - 11, eye_y, 7, fill="#ffffff", outline="black", width=2)
    circle(hx + 11, eye_y, 7, fill="#ffffff", outline="black", width=2)

    circle(hx - 11, eye_y - 2, 3, fill="#000000", outline="black", width=1)
    circle(hx + 11, eye_y - 2, 3, fill="#000000", outline="black", width=1)

    # Reading glasses
    circle(hx - 11, eye_y, 11, fill=None, outline="#212121", width=4)
    circle(hx + 11, eye_y, 11, fill=None, outline="#212121", width=4)
    line(hx - 2, eye_y, hx + 2, eye_y, "#212121", 4)

    # Mouth
    line(hx - 8, hy - 26, hx + 8, hy - 26, "#212121", 3)

    # Tongue
    line(hx, hy - 26, hx, hy - 44, "#d32f2f", 5)
    line(hx, hy - 44, hx - 6, hy - 52, "#d32f2f", 4)
    line(hx, hy - 44, hx + 6, hy - 52, "#d32f2f", 4)


# -------------------------------
# Main drawing order
# -------------------------------
draw_book()
draw_snake()

turtle.done()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 5 of the 12 newer Python features checked by our rubric. For example, it used timezone.utc, utcnow(), utcfromtimestamp() instead of datetime.UTC (Python 3.11) and a manual hashing loop instead of hashlib.file_digest() (Python 3.11). These choices give it a Python 3.10 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was import tomllib, introduced in Python 3.11.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ❌ stale | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ❌ stale | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ❌ stale | Path.walk() |
os.walk() |
batched |
3.12 | strong | ➖ n/a | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ❌ stale | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ➖ n/a | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ➖ n/a | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ❌ stale | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
"""Scan, report on, and archive files using settings from stash.toml."""

from __future__ import annotations

import argparse
import fnmatch
import hashlib
import json
import os
import shutil
import sys
from dataclasses import asdict, dataclass
from datetime import datetime, timezone
from pathlib import Path
from typing import Any, Sequence

try:
    import tomllib
except ModuleNotFoundError:
    print("stash requires Python 3.11 or newer.", file=sys.stderr)
    sys.exit(1)

SCRIPT_DIR: Path = Path(__file__).resolve().parent
CONFIG_PATH: Path = SCRIPT_DIR / "stash.toml"
STASH_JSON_PATH: Path = SCRIPT_DIR / "stash.json"
ARCHIVE_DIR: Path = SCRIPT_DIR / "archive"
_CHUNK_SIZE: int = 1024 * 1024


class StashError(Exception):
    """An expected error that should be reported to the user."""


@dataclass(frozen=True)
class FileRecord:
    """A single file captured by a scan."""

    path: str
    size: int
    sha256: str
    modified_utc: float


@dataclass(frozen=True)
class Settings:
    """Runtime settings loaded from stash.toml."""

    ignore: tuple[str, ...]
    batch_size: int
    label: str | None = None


def _fail(message: str) -> int:
    print(f"stash: {message}", file=sys.stderr)
    return 1


def _select_table(data: dict[str, Any]) -> dict[str, Any]:
    table: dict[str, Any] = {key: value for key, value in data.items() if key != "stash"}
    stash_table = data.get("stash")
    if isinstance(stash_table, dict):
        table.update(stash_table)
    return table


def load_settings() -> Settings:
    if not CONFIG_PATH.is_file():
        raise StashError(f"config file not found: {CONFIG_PATH}")

    try:
        with CONFIG_PATH.open("rb") as handle:
            data = tomllib.load(handle)
    except tomllib.TOMLDecodeError as exc:
        raise StashError(f"invalid TOML in {CONFIG_PATH}: {exc}") from exc
    except OSError as exc:
        raise StashError(f"could not read {CONFIG_PATH}: {exc}") from exc

    if not isinstance(data, dict):
        raise StashError(f"invalid TOML in {CONFIG_PATH}: root must be a table")

    table = _select_table(data)
    ignore_raw = table.get("ignore")
    batch_raw = table.get("batch_size")
    label_raw = table.get("label")

    if not isinstance(ignore_raw, list) or not all(isinstance(item, str) for item in ignore_raw):
        raise StashError(f"{CONFIG_PATH}: 'ignore' must be a list of glob patterns")
    if isinstance(batch_raw, bool) or not isinstance(batch_raw, int) or batch_raw <= 0:
        raise StashError(f"{CONFIG_PATH}: 'batch_size' must be a positive integer")
    if label_raw is not None and not isinstance(label_raw, str):
        raise StashError(f"{CONFIG_PATH}: 'label' must be a string when present")

    return Settings(tuple(ignore_raw), batch_raw, label_raw)


def _matches_any(rel_path: str, file_name: str, patterns: Sequence[str]) -> bool:
    for pattern in patterns:
        if not pattern:
            continue

        if fnmatch.fnmatch(rel_path, pattern) or fnmatch.fnmatch(file_name, pattern):
            return True

        if pattern.startswith("/"):
            if fnmatch.fnmatch(rel_path, pattern[1:]):
                return True

    return False


def _os_walk_error(error: OSError) -> None:
    target = error.filename or "<unknown>"
    raise StashError(f"could not access {target}: {error}") from error


def _iter_files(root: Path, patterns: Sequence[str]) -> list[Path]:
    files: list[Path] = []

    for dirpath, dirnames, filenames in os.walk(root, onerror=_os_walk_error):
        current = Path(dirpath)
        rel_dir = current.relative_to(root).as_posix()

        kept_dirs: list[str] = []
        for dirname in dirnames:
            rel_child = f"{rel_dir}/{dirname}" if rel_dir != "." else dirname
            if not _matches_any(rel_child, dirname, patterns):
                kept_dirs.append(dirname)
        dirnames[:] = kept_dirs

        for filename in filenames:
            file_path = current / filename
            rel_path = file_path.relative_to(root).as_posix()
            if not _matches_any(rel_path, filename, patterns):
                files.append(file_path)

    return files


def _sha256(path: Path) -> str:
    digest = hashlib.sha256()
    with path.open("rb") as handle:
        for chunk in iter(lambda: handle.read(_CHUNK_SIZE), b""):
            digest.update(chunk)
    return digest.hexdigest()


def _hash_files(files: Sequence[Path], batch_size: int) -> list[FileRecord]:
    records: list[FileRecord] = []
    total = len(files)
    total_batches = (total + batch_size - 1) // batch_size if total else 0

    for batch_number, start in enumerate(range(0, total, batch_size), start=1):
        batch = files[start : start + batch_size]

        for path in batch:
            try:
                stat = path.stat()
                digest = _sha256(path)
            except OSError as exc:
                raise StashError(f"failed to process {path}: {exc}") from exc

            records.append(
                FileRecord(
                    path=str(path),
                    size=stat.st_size,
                    sha256=digest,
                    modified_utc=stat.st_mtime,
                )
            )

        print(f"Progress: hashed batch {batch_number}/{total_batches} ({len(batch)} files)")

    return records


def write_records(records: Sequence[FileRecord]) -> None:
    payload = [asdict(record) for record in records]

    try:
        with STASH_JSON_PATH.open("w", encoding="utf-8") as handle:
            json.dump(payload, handle, indent=2)
            handle.write("\n")
    except OSError as exc:
        raise StashError(f"could not write {STASH_JSON_PATH}: {exc}") from exc


def read_records() -> list[FileRecord]:
    if not STASH_JSON_PATH.is_file():
        raise StashError(f"{STASH_JSON_PATH} not found; run `stash scan` first")

    try:
        with STASH_JSON_PATH.open("r", encoding="utf-8") as handle:
            data = json.load(handle)
    except OSError as exc:
        raise StashError(f"could not read {STASH_JSON_PATH}: {exc}") from exc
    except json.JSONDecodeError as exc:
        raise StashError(f"invalid JSON in {STASH_JSON_PATH}: {exc}") from exc

    if isinstance(data, dict):
        maybe_files = data.get("files")
        if not isinstance(maybe_files, list):
            raise StashError(f"{STASH_JSON_PATH} must contain a list of file records")
        data = maybe_files

    if not isinstance(data, list):
        raise StashError(f"{STASH_JSON_PATH} must contain a list of file records")

    records: list[FileRecord] = []
    for index, item in enumerate(data):
        if not isinstance(item, dict):
            raise StashError(f"{STASH_JSON_PATH}: record {index} must be an object")

        try:
            record = FileRecord(
                path=str(item["path"]),
                size=int(item["size"]),
                sha256=str(item["sha256"]),
                modified_utc=float(item["modified_utc"]),
            )
        except (KeyError, TypeError, ValueError) as exc:
            raise StashError(
                f"{STASH_JSON_PATH}: record {index} has missing or invalid fields"
            ) from exc

        records.append(record)

    return records


def _extension_groups(records: Sequence[FileRecord]) -> dict[str, list[FileRecord]]:
    groups: dict[str, list[FileRecord]] = {}

    for record in records:
        extension = Path(record.path).suffix
        groups.setdefault(extension, []).append(record)

    return groups


def _format_time(value: float) -> str:
    return datetime.fromtimestamp(value, tz=timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")


def cmd_scan(args: argparse.Namespace, settings: Settings) -> int:
    directory = Path(args.directory).expanduser()

    if not directory.is_dir():
        return _fail(f"directory not found or not a directory: {directory}")

    root = directory.resolve()
    files = sorted(_iter_files(root, settings.ignore), key=lambda path: path.as_posix())
    records = _hash_files(files, settings.batch_size)
    write_records(records)

    print(f"Wrote {len(records)} record(s) to {STASH_JSON_PATH}")
    return 0


def cmd_report(_: argparse.Namespace) -> int:
    records = read_records()
    groups = _extension_groups(records)

    if not groups:
        print("No files recorded.")
        return 0

    for extension in sorted(groups):
        items = groups[extension]
        total_size = sum(item.size for item in items)
        newest = max(items, key=lambda item: item.modified_utc)
        display_extension = extension if extension else "(no extension)"

        print(
            f"{display_extension}: {len(items)} files, {total_size} bytes, "
            f"newest: {newest.path} ({_format_time(newest.modified_utc)})"
        )

    return 0


def cmd_archive(_: argparse.Namespace) -> int:
    records = read_records()

    if not records:
        print("No files recorded.")
        return 0

    try:
        ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)
    except OSError as exc:
        raise StashError(f"could not create {ARCHIVE_DIR}: {exc}") from exc

    groups = _extension_groups(records)
    copied = 0

    for extension in sorted(groups):
        items = groups[extension]
        newest = max(items, key=lambda item: item.modified_utc)
        source = Path(newest.path)
        destination = ARCHIVE_DIR / source.name

        try:
            if not source.is_file():
                raise StashError(f"file not found: {source}")

            if source.resolve() == destination.resolve():
                copied += 1
                continue

            shutil.copy2(source, destination)
            copied += 1
        except StashError:
            raise
        except OSError as exc:
            raise StashError(f"could not copy {source} to {destination}: {exc}") from exc

    print(f"Copied {copied} file(s) to {ARCHIVE_DIR}")
    return 0


def build_parser() -> argparse.ArgumentParser:
    parser = argparse.ArgumentParser(
        prog="stash",
        description="Scan, report on, and archive files described by stash.toml.",
    )
    subparsers = parser.add_subparsers(dest="command", required=True)

    scan_parser = subparsers.add_parser("scan", help="recursively scan a directory")
    scan_parser.add_argument("directory", help="directory to scan")

    subparsers.add_parser("report", help="print per-extension statistics from stash.json")
    subparsers.add_parser("archive", help="copy the newest file of each extension to archive/")

    return parser


def main(argv: Sequence[str] | None = None) -> int:
    parser = build_parser()
    args = parser.parse_args(argv)

    try:
        settings = load_settings()
    except StashError as exc:
        return _fail(str(exc))

    try:
        command = args.command

        if command == "scan":
            return cmd_scan(args, settings)
        if command == "report":
            return cmd_report(args)
        if command == "archive":
            return cmd_archive(args)
    except StashError as exc:
        return _fail(str(exc))

    return _fail(f"unknown command: {args.command}")


if __name__ == "__main__":
    sys.exit(main())
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
3.14
The Small Option
While adding an --ext option, DaisyRose 27B left all 10 unrelated spots alone. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -15,10 +15,15 @@


-def collect_sizes(root, min_size):
+def collect_sizes(root, min_size, ext=None):
     # TODO: skip symlinks?
     sizes = []
     for dirpath, dirnames, filenames in os.walk(root):
         for i in range(len(filenames)):
-            path = os.path.join(dirpath, filenames[i])
+            filename = filenames[i]
+
+            if ext is not None and not filename.endswith(ext):
+                continue
+
+            path = os.path.join(dirpath, filename)
             try:
                 size = os.path.getsize(path)
@@ -40,4 +45,5 @@
     parser.add_argument("--limit", type=int, default=10, help="how many files to show")
     parser.add_argument("--min-size", type=int, default=0, help="skip files smaller than this many bytes")
+    parser.add_argument("--ext", help="only count files with this extension, like .log")
     args = parser.parse_args()

@@ -47,5 +53,10 @@
         sys.exit(1)

-    top = largest(collect_sizes(args.root, args.min_size), args.limit)
+    ext = args.ext
+    if ext:
+        if not ext.startswith("."):
+            ext = "." + ext
+
+    top = largest(collect_sizes(args.root, args.min_size, ext), args.limit)
     for i in range(len(top)):
         size, path = top[i]
The Made-Up Function
Caught it. There is no itertools.flatten(). It said the function doesn’t exist and offered a real alternative.
itertools doesn’t have flatten(). For one level:
from itertools import chain

nested = [[1, 2], [3, 4], [5, 6]]
flat = list(chain.from_iterable(nested))
Result:
[1, 2, 3, 4, 5, 6]
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 1 min 57 s | 23.9k | 22.0k | $0.04 |
| The stash tool | 8 min 42 s | 38.2k | 35.4k | $0.19 |
| Newest Python | 1 min 13 s | 15.5k | 15.5k | $0.03 |
| The small option | 16 s | 3.2k | 2.7k | $0.006 |
| The made-up function | 1 s | 195 | 109 | $0.000 |
| Total | 12 min 10 s | 81.1k | 75.7k | $0.27 |
Reasoning effort: default. Cost is what OpenRouter billed. Output tokens include the thinking tokens. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
See how DaisyRose 27B compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review