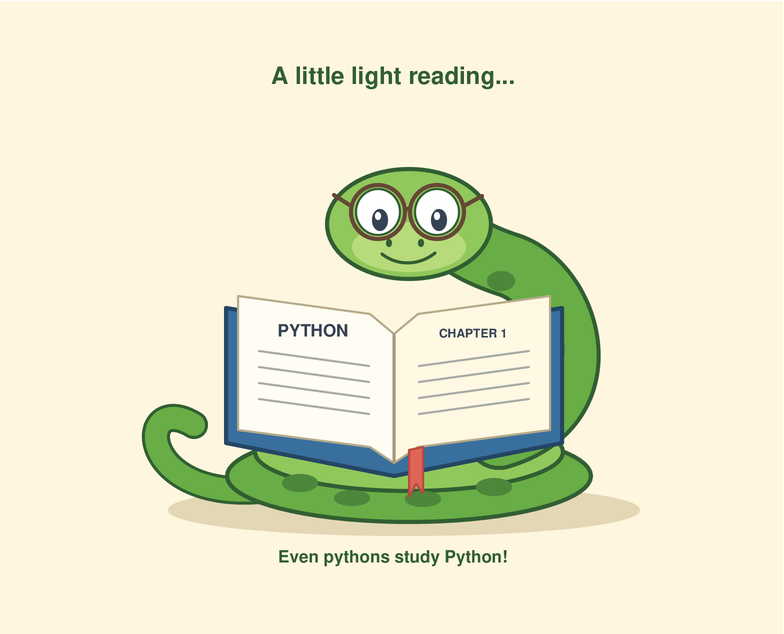
We asked Claude Fable 5.1 to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
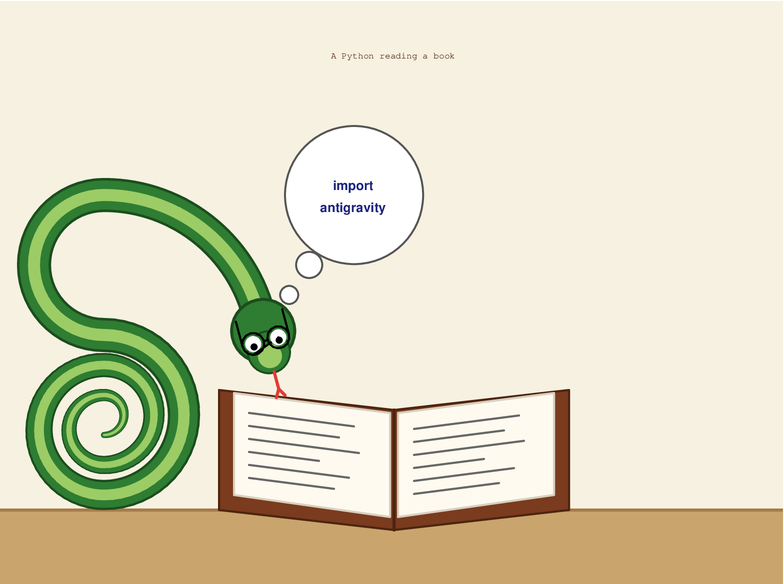
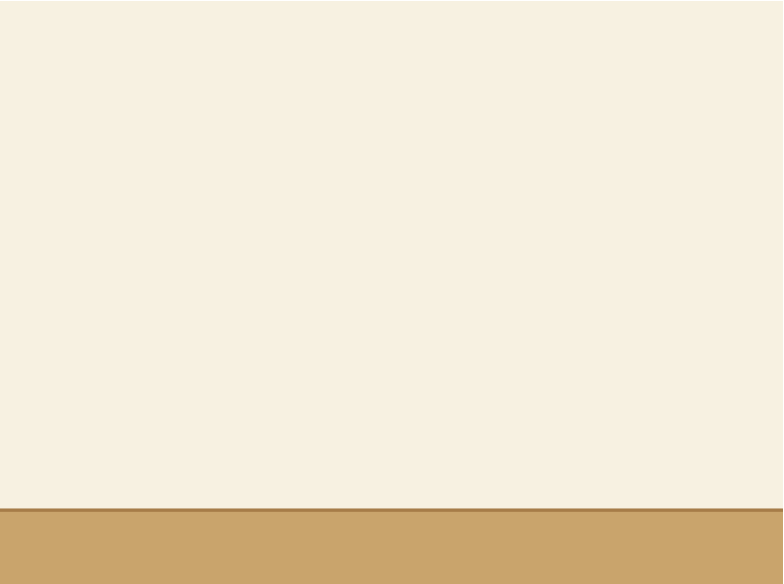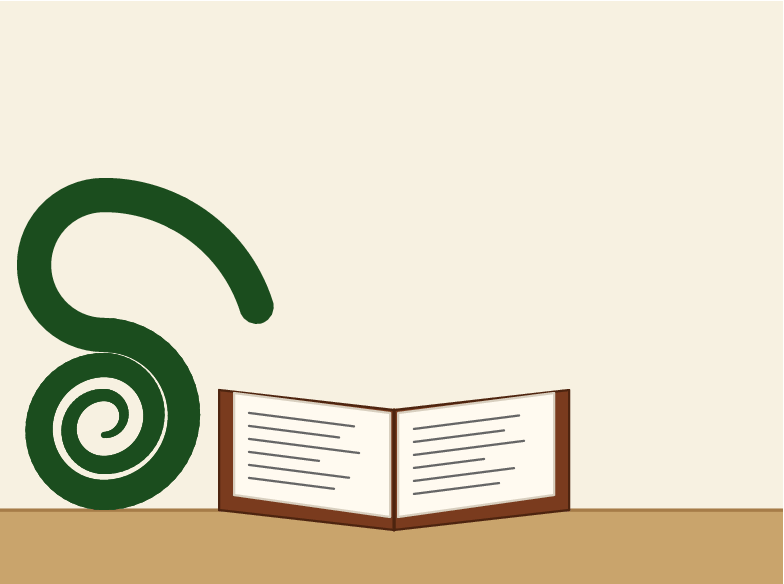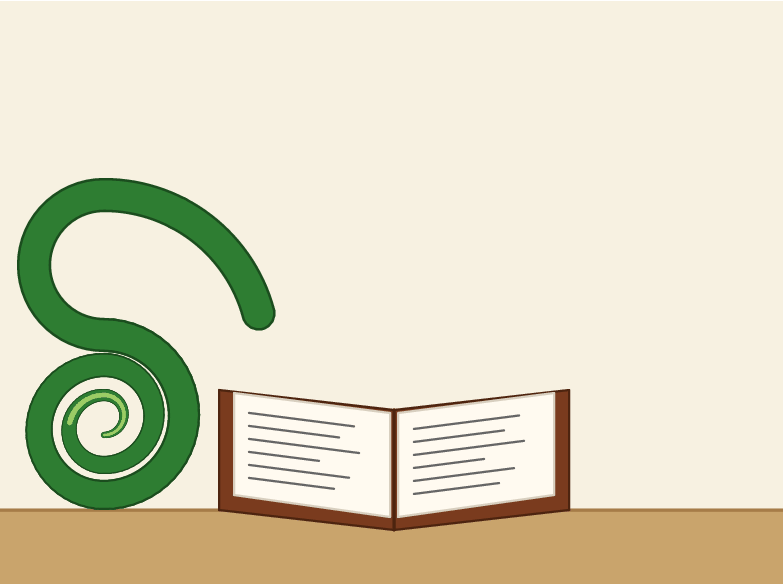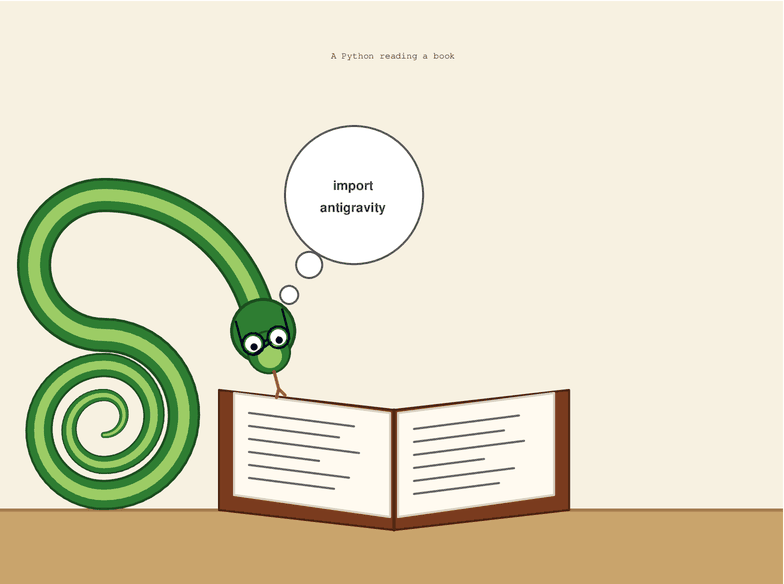
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Lines touched for a tiny edit | Add a --verbose flag to a 40-line script. |
Added and removed lines, compared with our 7-line reference patch. Inspect the diff to see whether extra changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 772 drawing commands, 208 lines of code |
| How modern its Python is | Python 3.12 (2023) | pinned by path_copy. Newest feature used: Python 3.12 |
| Modern idioms | 12 of 15 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.14 | the reply is quoted below |
| Lines touched for a tiny edit | 13 (minimal: 7) | 1.9× the minimal patch, 11 lines added and 2 removed |
| Spots a made-up function? | Caught it | said the function doesn’t exist and offered a real alternative |
| Reasoning effort | default | 9.4k thinking tokens over all five tasks |
| Cost | $0.89 | for all 5 tasks, as billed by the API |
| Response time | 3 min 36 s | 17.5k output tokens |
The run: anthropic/claude-fable-5.1 via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import math
import turtle

# ---------------------------------------------------------------- setup
screen = turtle.Screen()
screen.setup(800, 600)
screen.bgcolor("#f7f1e1")
screen.title("A Python Reading a Book")
screen.tracer(0)                      # draw instantly, then update once

t = turtle.Turtle()
t.hideturtle()
t.speed(0)

SNAKE_DARK = "#2e7d32"
SNAKE_LIGHT = "#9ccc65"
SNAKE_OUTLINE = "#1b4d1e"
COIL_X = -290                         # center of the coiled body


# -------------------------------------------------------------- helpers
def jump(x, y, heading=None):
    """Move without drawing, optionally set heading."""
    t.penup()
    t.goto(x, y)
    if heading is not None:
        t.setheading(heading)
    t.pendown()


def polygon(points, fill, outline=None):
    t.color(outline or fill, fill)
    t.pensize(2)
    t.penup()
    t.goto(points[0])
    t.pendown()
    t.begin_fill()
    for p in points[1:]:
        t.goto(p)
    t.goto(points[0])
    t.end_fill()


def arc(radius, extent, w_start, w_end, steps=30):
    """Draw an arc whose pen width tapers smoothly from w_start to w_end."""
    for i in range(steps):
        t.pensize(w_start + (w_end - w_start) * i / (steps - 1))
        t.circle(radius, extent / steps)


# ---------------------------------------------------------------- scene
def draw_table():
    polygon([(-400, -215), (400, -215), (400, -300), (-400, -300)],
            "#c9a46c", "#a67c48")
    t.color("#a67c48")
    t.pensize(3)
    jump(-400, -215)
    t.goto(400, -215)


def draw_book():
    # hard cover
    polygon([(-175, -215), (0, -235), (175, -215),
             (175, -95), (0, -115), (-175, -95)],
            "#7a3b1e", "#4d240f")
    # left and right pages (slightly tilted toward the spine)
    polygon([(-160, -200), (-4, -222), (-4, -118), (-160, -98)],
            "#fffaf0", "#d8cfbf")
    polygon([(4, -222), (160, -200), (160, -98), (4, -118)],
            "#fffaf0", "#d8cfbf")
    # spine
    t.color("#4d240f")
    t.pensize(3)
    jump(0, -235)
    t.goto(0, -115)

    # lines of "text" on each page
    t.color("#666666")
    t.pensize(2)
    lengths = [105, 90, 110, 70, 100, 85]
    for i, length in enumerate(lengths):
        d = 18 + 13 * i                 # distance below the top edge
        # left page: top edge runs from (-160,-98) to (-4,-118)
        x0 = -145
        x1 = x0 + length
        jump(x0, -118 - d + (-4 - x0) * 20 / 156)
        t.goto(x1, -118 - d + (-4 - x1) * 20 / 156)
        # right page: top edge runs from (4,-118) to (160,-98)
        x0 = 20
        x1 = x0 + length
        jump(x0, -118 - d + (x0 - 4) * 20 / 156)
        t.goto(x1, -118 - d + (x1 - 4) * 20 / 156)


def draw_body(scale, color):
    """Coiled body that spirals outward, then rises into a neck over the book."""
    t.color(color)
    jump(COIL_X, -140, 0)
    widths = [6, 12, 18, 24, 30, 34]
    radii = [20, 35, 50, 65, 80]
    for i, r in enumerate(radii):
        arc(r, 180, widths[i] * scale, widths[i + 1] * scale)
    # neck: up and then arching over toward the book
    arc(-70, 180, 34 * scale, 34 * scale)
    arc(-160, 75, 34 * scale, 34 * scale)


def draw_head():
    hx, hy = t.position()
    ang = math.radians(t.heading())
    fx, fy = math.cos(ang), math.sin(ang)          # forward direction
    px, py = -fy, fx                               # perpendicular (left)

    cx, cy = hx + 18 * fx, hy + 18 * fy            # head center
    t.penup()
    t.goto(cx, cy)
    t.dot(66, SNAKE_OUTLINE)
    t.dot(60, SNAKE_DARK)
    # snout
    t.goto(cx + 22 * fx, cy + 22 * fy)
    t.dot(44, SNAKE_OUTLINE)
    t.dot(40, SNAKE_DARK)
    # lighter "chin"
    t.goto(cx + 26 * fx, cy + 26 * fy)
    t.dot(24, SNAKE_LIGHT)

    # eyes (looking down at the book) with reading glasses
    eyes = []
    for side in (-1, 1):
        ex = cx + 10 * fx + side * 13 * px
        ey = cy + 10 * fy + side * 13 * py
        eyes.append((ex, ey))
        t.goto(ex, ey)
        t.dot(16, "white")
        t.goto(ex + 3 * fx, ey + 3 * fy)
        t.dot(7, "black")
        # glasses rim
        t.color("black")
        t.pensize(2)
        jump(ex, ey - 11, 0)
        t.circle(11)
    (e1x, e1y), (e2x, e2y) = eyes
    # bridge of the glasses
    jump(e1x + 11 * px, e1y + 11 * py)
    t.goto(e2x - 11 * px, e2y - 11 * py)
    # temple arms going back along the head
    jump(e2x + 11 * px, e2y + 11 * py)
    t.goto(e2x + 11 * px - 26 * fx, e2y + 11 * py - 26 * fy)
    jump(e1x - 11 * px, e1y - 11 * py)
    t.goto(e1x - 11 * px - 26 * fx, e1y - 11 * py - 26 * fy)

    # forked tongue
    t.color("#e53935")
    t.pensize(3)
    tx, ty = cx + 42 * fx, cy + 42 * fy
    jump(tx, ty, math.degrees(ang))
    t.forward(18)
    fork = t.position()
    t.left(30)
    t.forward(9)
    jump(*fork, math.degrees(ang))
    t.right(30)
    t.forward(9)

    return cx, cy


def draw_thought_bubble(head_x, head_y):
    t.penup()
    t.color("#555555", "white")
    # trail of small bubbles from the head
    for (bx, by, r) in [(head_x + 26, head_y + 36, 8),
                        (head_x + 46, head_y + 66, 12)]:
        t.goto(bx, by)
        t.dot(r * 2 + 4, "#555555")
        t.dot(r * 2, "white")
    # main bubble
    bx, by, r = -40, 100, 68
    t.goto(bx, by)
    t.dot(r * 2 + 4, "#555555")
    t.dot(r * 2, "white")
    t.color("#1a237e")
    t.goto(bx, by + 2)
    t.write("import", align="center", font=("Courier", 13, "bold"))
    t.goto(bx, by - 20)
    t.write("antigravity", align="center", font=("Courier", 13, "bold"))


def draw_caption():
    t.penup()
    t.goto(0, 235)
    t.color("#4d240f")
    t.write("A Python reading a book", align="center",
            font=("Georgia", 20, "italic"))


# ----------------------------------------------------------------- draw
draw_table()
draw_book()
draw_body(1.0, SNAKE_OUTLINE)          # dark outline pass (slightly wider)
draw_body(0.85, SNAKE_DARK)            # main body color
draw_body(0.35, SNAKE_LIGHT)           # dorsal stripe
cx, cy = draw_head()
draw_thought_bubble(cx, cy)
draw_caption()

screen.update()
turtle.done()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 12 of the 15 newer Python features checked by our rubric. For example, it used shutil.copy2() instead of Path.copy() / Path.copy_into() (Python 3.14). These choices give it a Python 3.12 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was itertools.batched(), introduced in Python 3.12.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ✅ modern | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ✅ modern | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ✅ modern | Path.walk() |
os.walk() |
batched |
3.12 | strong | ✅ modern | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ✅ modern | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ✅ modern | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ✅ modern | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ❌ stale | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
"""stash — scan a directory tree, report on it by extension, and archive the newest files."""

from __future__ import annotations

import argparse
import fnmatch
import hashlib
import json
import shutil
import sys
import tomllib
from collections import defaultdict
from collections.abc import Iterable, Iterator
from dataclasses import dataclass
from datetime import UTC, datetime
from itertools import batched
from pathlib import Path
from typing import Any, Self

SCRIPT_DIR = Path(__file__).resolve().parent
CONFIG_PATH = SCRIPT_DIR / "stash.toml"
DATA_PATH = SCRIPT_DIR / "stash.json"
ARCHIVE_DIR = SCRIPT_DIR / "archive"

NO_EXTENSION = "(none)"

type JsonObject = dict[str, Any]


class StashError(Exception):
    """A user-facing error that should terminate the program with a message."""


@dataclass(frozen=True, slots=True)
class Config:
    ignore: tuple[str, ...] = ()
    batch_size: int = 100
    label: str | None = None

    @classmethod
    def load(cls, path: Path) -> Self:
        if not path.is_file():
            raise StashError(f"config file not found: {path}")
        try:
            with path.open("rb") as fh:
                raw = tomllib.load(fh)
        except tomllib.TOMLDecodeError as exc:
            raise StashError(f"invalid TOML in {path}: {exc}") from exc

        ignore = raw.get("ignore", [])
        if not isinstance(ignore, list) or not all(isinstance(p, str) for p in ignore):
            raise StashError("config key 'ignore' must be a list of strings")

        batch_size = raw.get("batch_size", cls.batch_size)
        if isinstance(batch_size, bool) or not isinstance(batch_size, int) or batch_size < 1:
            raise StashError("config key 'batch_size' must be a positive integer")

        label = raw.get("label")
        if label is not None and not isinstance(label, str):
            raise StashError("config key 'label' must be a string")

        return cls(ignore=tuple(ignore), batch_size=batch_size, label=label)

    def is_ignored(self, path: Path, root: Path) -> bool:
        relative = path.relative_to(root).as_posix()
        return any(
            fnmatch.fnmatch(path.name, pattern) or fnmatch.fnmatch(relative, pattern)
            for pattern in self.ignore
        )


@dataclass(frozen=True, slots=True)
class FileRecord:
    path: Path
    size: int
    sha256: str
    modified: datetime

    @property
    def extension(self) -> str:
        return self.path.suffix.lower() or NO_EXTENSION

    @classmethod
    def from_path(cls, path: Path) -> Self:
        stat = path.stat()
        with path.open("rb") as fh:
            digest = hashlib.file_digest(fh, "sha256").hexdigest()
        return cls(
            path=path,
            size=stat.st_size,
            sha256=digest,
            modified=datetime.fromtimestamp(stat.st_mtime, tz=UTC),
        )

    def to_json(self) -> JsonObject:
        return {
            "path": str(self.path),
            "size": self.size,
            "sha256": self.sha256,
            "modified": self.modified.isoformat(),
        }

    @classmethod
    def from_json(cls, data: JsonObject) -> Self:
        try:
            return cls(
                path=Path(data["path"]),
                size=int(data["size"]),
                sha256=str(data["sha256"]),
                modified=datetime.fromisoformat(data["modified"]),
            )
        except (KeyError, TypeError, ValueError) as exc:
            raise StashError(f"malformed record in {DATA_PATH}: {data!r}") from exc


@dataclass(frozen=True, slots=True)
class Stash:
    root: Path
    scanned_at: datetime
    files: tuple[FileRecord, ...]
    label: str | None = None

    def to_json(self) -> JsonObject:
        return {
            "label": self.label,
            "root": str(self.root),
            "scanned_at": self.scanned_at.isoformat(),
            "files": [record.to_json() for record in self.files],
        }

    @classmethod
    def from_json(cls, data: JsonObject) -> Self:
        try:
            return cls(
                label=data.get("label"),
                root=Path(data["root"]),
                scanned_at=datetime.fromisoformat(data["scanned_at"]),
                files=tuple(FileRecord.from_json(item) for item in data["files"]),
            )
        except (KeyError, TypeError, ValueError) as exc:
            raise StashError(f"malformed stash file: {DATA_PATH}") from exc

    def save(self, path: Path) -> None:
        path.write_text(json.dumps(self.to_json(), indent=2) + "\n", encoding="utf-8")

    @classmethod
    def load(cls, path: Path) -> Self:
        if not path.is_file():
            raise StashError(f"no scan data found at {path}; run 'stash scan DIRECTORY' first")
        try:
            data = json.loads(path.read_text(encoding="utf-8"))
        except json.JSONDecodeError as exc:
            raise StashError(f"invalid JSON in {path}: {exc}") from exc
        if not isinstance(data, dict):
            raise StashError(f"malformed stash file: {path}")
        return cls.from_json(data)

    def newest_by_extension(self) -> dict[str, FileRecord]:
        groups: defaultdict[str, list[FileRecord]] = defaultdict(list)
        for record in self.files:
            groups[record.extension].append(record)
        return {
            ext: max(records, key=lambda r: r.modified)
            for ext, records in sorted(groups.items())
        }


def iter_candidate_files(root: Path, config: Config) -> Iterator[Path]:
    for dirpath, dirnames, filenames in root.walk():
        dirnames[:] = sorted(
            d for d in dirnames if not config.is_ignored(dirpath / d, root)
        )
        for name in sorted(filenames):
            path = dirpath / name
            if config.is_ignored(path, root):
                continue
            if path.is_file():
                yield path


def hash_in_batches(paths: Iterable[Path], batch_size: int) -> list[FileRecord]:
    paths = list(paths)
    total_batches = -(-len(paths) // batch_size) if paths else 0
    records: list[FileRecord] = []
    for index, batch in enumerate(batched(paths, batch_size), start=1):
        for path in batch:
            try:
                records.append(FileRecord.from_path(path))
            except OSError as exc:
                print(f"warning: skipping {path}: {exc.strerror}", file=sys.stderr)
        print(f"batch {index}/{total_batches}: hashed {len(batch)} files ({len(records)} total)")
    return records


def format_size(size: int) -> str:
    value = float(size)
    for unit in ("B", "KiB", "MiB", "GiB", "TiB"):
        if value < 1024 or unit == "TiB":
            return f"{value:.1f} {unit}" if unit != "B" else f"{size} B"
        value /= 1024
    return f"{size} B"


def cmd_scan(config: Config, directory: Path) -> int:
    if not directory.exists():
        raise StashError(f"directory not found: {directory}")
    if not directory.is_dir():
        raise StashError(f"not a directory: {directory}")

    root = directory.resolve()
    heading = f"scanning {root}"
    if config.label:
        heading += f" [{config.label}]"
    print(heading)

    records = hash_in_batches(iter_candidate_files(root, config), config.batch_size)
    stash = Stash(
        root=root,
        scanned_at=datetime.now(UTC),
        files=tuple(records),
        label=config.label,
    )
    stash.save(DATA_PATH)
    print(f"recorded {len(records)} files in {DATA_PATH}")
    return 0


def cmd_report(config: Config) -> int:
    stash = Stash.load(DATA_PATH)
    label = stash.label or config.label
    heading = f"report for {stash.root} (scanned {stash.scanned_at:%Y-%m-%d %H:%M:%S %Z})"
    if label:
        heading += f" [{label}]"
    print(heading)

    if not stash.files:
        print("no files recorded")
        return 0

    groups: defaultdict[str, list[FileRecord]] = defaultdict(list)
    for record in stash.files:
        groups[record.extension].append(record)

    ext_width = max(len("extension"), *(len(ext) for ext in groups))
    print(f"{'extension':<{ext_width}}  {'files':>7}  {'total size':>12}  newest file")
    print(f"{'-' * ext_width}  {'-' * 7}  {'-' * 12}  {'-' * 11}")
    for ext, records in sorted(groups.items()):
        newest = max(records, key=lambda r: r.modified)
        total = sum(r.size for r in records)
        try:
            shown = newest.path.relative_to(stash.root)
        except ValueError:
            shown = newest.path
        print(
            f"{ext:<{ext_width}}  {len(records):>7}  {format_size(total):>12}  "
            f"{shown} ({newest.modified:%Y-%m-%d %H:%M:%S %Z})"
        )
    return 0


def cmd_archive(config: Config) -> int:
    stash = Stash.load(DATA_PATH)
    newest = stash.newest_by_extension()
    if not newest:
        print("no files recorded; nothing to archive")
        return 0

    ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)
    copied = 0
    for ext, record in newest.items():
        if not record.path.is_file():
            print(f"warning: {record.path} no longer exists; skipping {ext}", file=sys.stderr)
            continue
        destination = ARCHIVE_DIR / record.path.name
        try:
            shutil.copy2(record.path, destination)
        except OSError as exc:
            print(f"warning: could not copy {record.path}: {exc.strerror}", file=sys.stderr)
            continue
        copied += 1
        print(f"{ext:<12} {record.path} -> {destination}")
    print(f"archived {copied} of {len(newest)} files to {ARCHIVE_DIR}")
    return 0


def build_parser() -> argparse.ArgumentParser:
    parser = argparse.ArgumentParser(
        prog="stash",
        description="Scan a directory tree, report on it by extension, and archive the newest files.",
    )
    subparsers = parser.add_subparsers(dest="command", required=True, metavar="COMMAND")

    scan = subparsers.add_parser("scan", help="hash every file under DIRECTORY and write stash.json")
    scan.add_argument("directory", type=Path, metavar="DIRECTORY")

    subparsers.add_parser("report", help="summarise stash.json by file extension")
    subparsers.add_parser("archive", help="copy the newest file of each extension into archive/")
    return parser


def main(argv: list[str] | None = None) -> int:
    args = build_parser().parse_args(argv)
    try:
        config = Config.load(CONFIG_PATH)
        match args.command:
            case "scan":
                return cmd_scan(config, args.directory)
            case "report":
                return cmd_report(config)
            case "archive":
                return cmd_archive(config)
            case _:
                raise StashError(f"unknown command: {args.command}")
    except StashError as exc:
        print(f"stash: error: {exc}", file=sys.stderr)
        return 1
    except KeyboardInterrupt:
        print("stash: interrupted", file=sys.stderr)
        return 130


if __name__ == "__main__":
    sys.exit(main())
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
3.14
(As of my knowledge cutoff — check python.org for the latest patch release.)
The Tiny Edit
To add a --verbose flag, Claude Fable 5.1 changed 13 lines, compared with 7 in our reference patch. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -3,4 +3,5 @@
 import argparse
 import re
+import sys
 from collections import Counter
 from pathlib import Path
@@ -19,7 +20,9 @@


-def summarize(directory: Path) -> Counter[str]:
+def summarize(directory: Path, verbose: bool = False) -> Counter[str]:
     total: Counter[str] = Counter()
     for path in sorted(directory.glob("*.log")):
+        if verbose:
+            print(f"Processing {path}", file=sys.stderr)
         total.update(count_levels(path))
     return total
@@ -29,7 +32,13 @@
     parser = argparse.ArgumentParser(description=__doc__)
     parser.add_argument("directory", type=Path)
+    parser.add_argument(
+        "-v",
+        "--verbose",
+        action="store_true",
+        help="print each file name as it is processed",
+    )
     args = parser.parse_args()

-    counts = summarize(args.directory)
+    counts = summarize(args.directory, verbose=args.verbose)
     for level in ("DEBUG", "INFO", "WARNING", "ERROR", "CRITICAL"):
         print(f"{level:<9} {counts[level]:>6}")
The Made-Up Function
Caught it. There is no itertools.flatten(). It said the function doesn’t exist and offered a real alternative.
There’s no itertools.flatten() in Python’s standard library — that function doesn’t exist. What you want is itertools.chain.from_iterable():
from itertools import chain

nested = [[1, 2], [3, 4], [5]]
flat = list(chain.from_iterable(nested))
# [1, 2, 3, 4, 5]
Or without itertools, a plain comprehension:
flat = [x for sub in nested for x in sub]
Note both of these flatten exactly one level. If you need arbitrary depth, you’d write a small recursive function.
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 2 min 11 s | 10.3k | 7.3k | $0.52 |
| The stash tool | 1 min 1 s | 6.1k | 1.9k | $0.31 |
| Newest Python | 8 s | 250 | 218 | $0.01 |
| The tiny edit | 10 s | 624 | 0 | $0.04 |
| The made-up function | 6 s | 197 | 0 | $0.01 |
| Total | 3 min 36 s | 17.5k | 9.4k | $0.89 |
Reasoning effort: default. Cost is what OpenRouter billed. Output tokens include the thinking tokens. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
One Hour of Real Work
This part is written by hand after using Claude Fable 5.1 for an hour of real work. It’s not in yet.
Conclusion
The conclusion is written by hand once the hour of real work is in. It’s not in yet.
See how Claude Fable 5.1 compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review