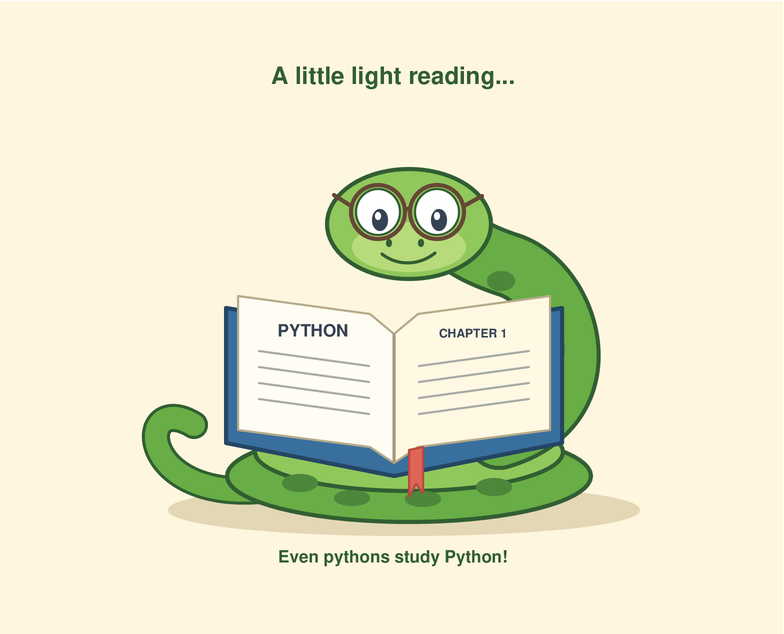
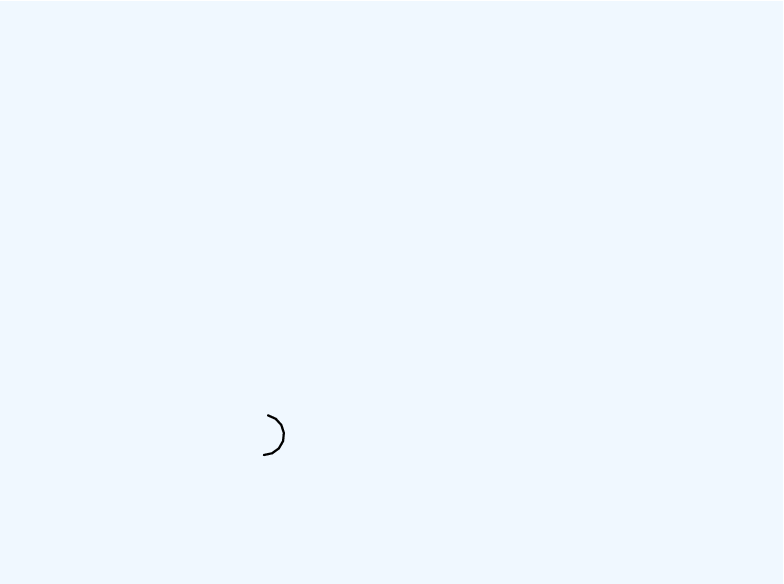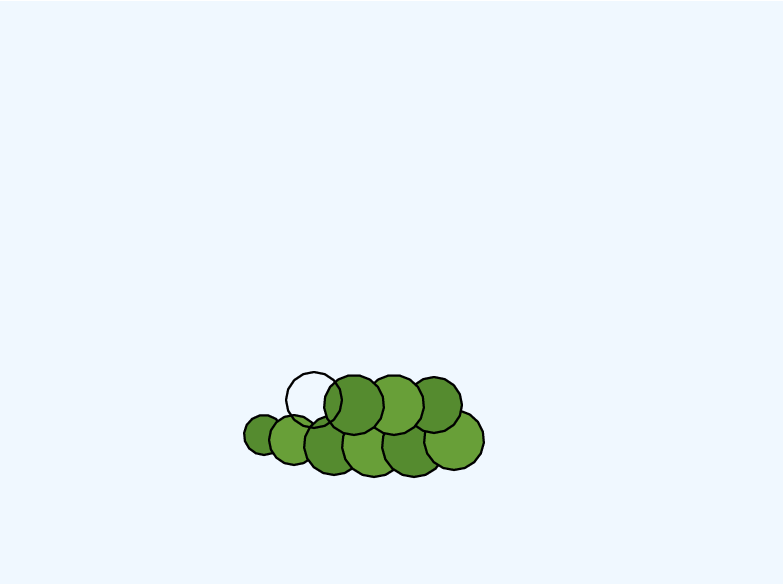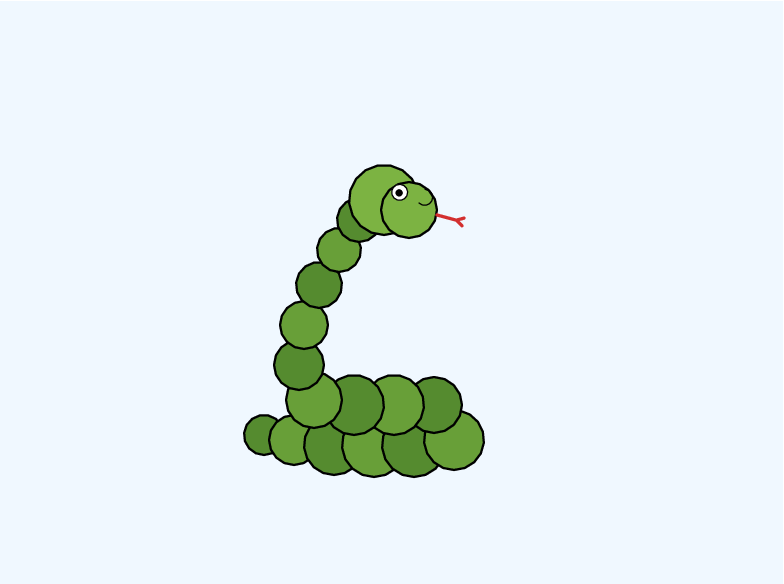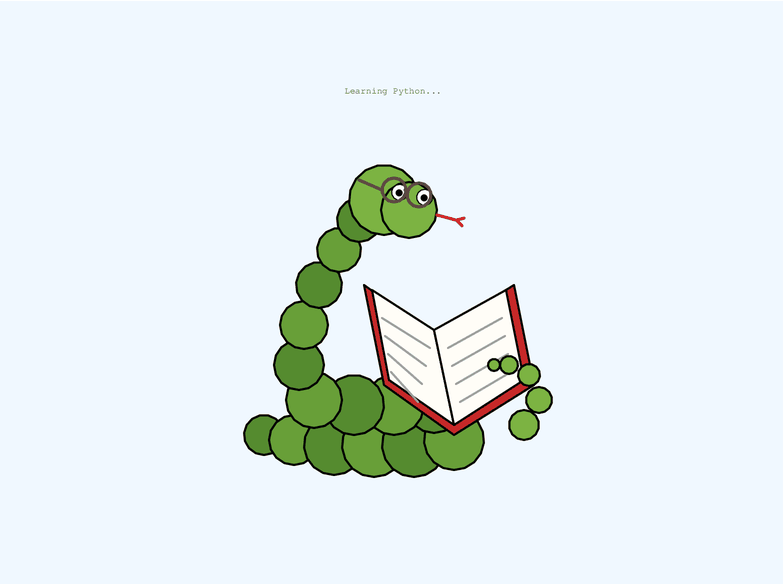
We asked Gemini 4 Argon to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
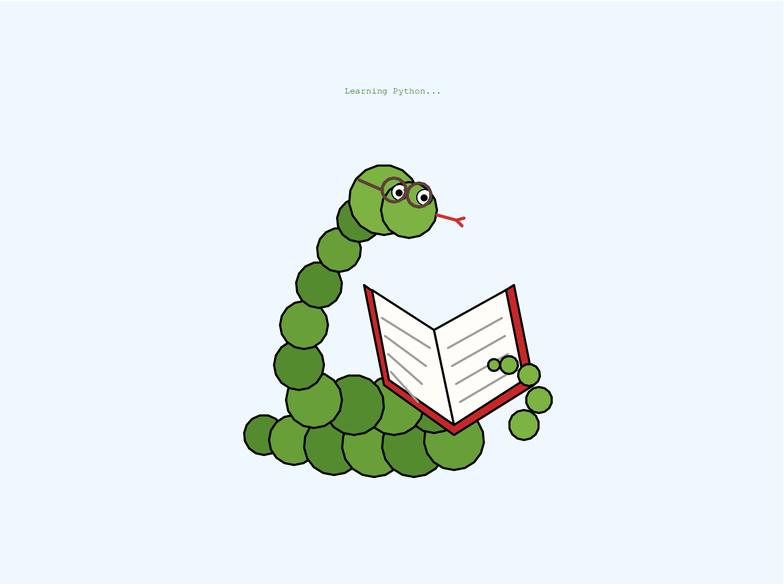
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Unrelated edits | Add an --ext option to a 50-line script. |
The script works but has ten spots that are easy to tidy up, like an unused import, % formatting, and a typo in a comment. None of them is part of the task. We list the ones the model changed anyway. Inspect the diff to see whether those changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 521 drawing commands, 216 lines of code |
| How modern its Python is | Python 3.10 (2021) | pinned by datetime_utc. Newest feature used: Python 3.12 |
| Modern idioms | 12 of 15 | of the checkpoints that applied to its code |
| Latest Python version reported | no version given | the reply is quoted below |
| Unrelated edits | 0 of 10 | left every unrelated spot alone |
| Spots a made-up function? | Caught it | said the function doesn’t exist and offered a real alternative |
| Reasoning effort | default | no thinking tokens reported |
| Cost | $0.06 | for all 5 tasks, as billed by the API |
| Response time | 1 min 11 s | 5.4k output tokens |
The run: google/gemini-4-argon via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import turtle


def setup_canvas():
    screen = turtle.Screen()
    screen.title("A Python Reading a Book")
    screen.bgcolor("#F0F8FF")  # Alice Blue background
    screen.setup(width=800, height=600)

    t = turtle.Turtle()
    t.speed(8)  # 1 is slow, 10 is fast, 0 is instant
    t.hideturtle()
    return t, screen


def draw_circle(t, x, y, radius, color, outline="black", pen_size=2):
    t.penup()
    t.goto(x, y - radius)
    t.pendown()
    t.pensize(pen_size)
    t.color(outline, color)
    t.begin_fill()
    t.circle(radius)
    t.end_fill()


def draw_snake_body(t):
    # We draw overlapping circles from the tail to the neck to create a coiled effect
    body_segments = [
        # Base coil (left to right)
        (-130, -140, 20),
        (-100, -145, 25),
        (-60, -150, 30),
        (-20, -150, 32),
        (20, -150, 32),
        (60, -145, 30),
        # Middle coil (right to left)
        (40, -110, 28),
        (0, -110, 30),
        (-40, -110, 30),
        (-80, -105, 28),
        # Rising neck (curving up)
        (-95, -70, 25),
        (-90, -30, 24),
        (-75, 10, 23),
        (-55, 45, 22),
        (-35, 75, 22),
    ]

    # Alternate slightly between two shades of green for texture
    for i, (x, y, r) in enumerate(body_segments):
        color = "#558B2F" if i % 2 == 0 else "#689F38"
        draw_circle(t, x, y, r, color)


def draw_snake_head(t):
    # Main head
    draw_circle(t, -10, 95, 35, "#7CB342")
    # Snout
    draw_circle(t, 15, 85, 28, "#7CB342")

    # Tongue
    t.penup()
    t.goto(43, 80)
    t.pendown()
    t.color("#D32F2F")
    t.pensize(3)
    t.setheading(-15)
    t.forward(20)
    # Fork in the tongue
    t.left(30)
    t.forward(8)
    t.backward(8)
    t.right(60)
    t.forward(8)


def draw_glasses_and_eyes(t):
    # Left Eye
    draw_circle(t, 0, 105, 8, "white", pen_size=1)
    draw_circle(t, 3, 103, 3, "black", pen_size=1)  # Looking down at the book

    # Right Eye
    draw_circle(t, 25, 100, 8, "white", pen_size=1)
    draw_circle(t, 28, 98, 3, "black", pen_size=1)  # Looking down at the book

    # Glasses Frames (Gold/Brown)
    t.pensize(3)
    t.color("#5D4037")

    # Left Lens
    t.penup()
    t.goto(0, 105 - 12)
    t.setheading(0)
    t.pendown()
    t.circle(12)

    # Right Lens
    t.penup()
    t.goto(25, 100 - 12)
    t.setheading(0)
    t.pendown()
    t.circle(12)

    # Bridge of glasses
    t.penup()
    t.goto(11, 105)
    t.pendown()
    t.goto(14, 103)

    # Earpiece (going back to the head)
    t.penup()
    t.goto(-12, 105)
    t.pendown()
    t.goto(-35, 115)


def draw_book(t):
    # Draw an open book tilted for reading

    # 1. Red Book Cover (Background polygon)
    t.penup()
    t.goto(60, -140)  # Bottom spine
    t.pendown()
    t.color("black", "#C62828")  # Dark Red
    t.pensize(2)
    t.begin_fill()
    t.goto(-10, -90)  # Bottom left
    t.goto(-30, 10)  # Top left
    t.goto(40, -40)  # Top spine
    t.goto(120, 10)  # Top right
    t.goto(140, -90)  # Bottom right
    t.goto(60, -140)  # Back to bottom spine
    t.end_fill()

    # 2. Left Page (White)
    t.penup()
    t.goto(60, -130)  # Bottom spine
    t.pendown()
    t.color("black", "#FFFDF7")  # Off-white
    t.begin_fill()
    t.goto(-5, -85)  # Bottom left
    t.goto(-22, 5)  # Top left
    t.goto(40, -35)  # Top spine
    t.goto(60, -130)  # Back to bottom spine
    t.end_fill()

    # 3. Right Page (White)
    t.penup()
    t.goto(60, -130)  # Bottom spine
    t.pendown()
    t.begin_fill()
    t.goto(130, -85)  # Bottom right
    t.goto(112, 5)  # Top right
    t.goto(40, -35)  # Top spine
    t.goto(60, -130)  # Back to bottom spine
    t.end_fill()

    # 4. Draw "Text" lines on the pages
    t.pensize(2)
    t.color("#9E9E9E")  # Grey for text

    # Left page text
    for i in range(1, 5):
        t.penup()
        t.goto(40 - (i * 4), -35 - (i * 18))
        t.pendown()
        t.goto(-15 + (i * 3), -5 - (i * 18))

    # Right page text
    for i in range(1, 5):
        t.penup()
        t.goto(50 + (i * 4), -35 - (i * 18))
        t.pendown()
        t.goto(105 + (i * 3), -5 - (i * 18))


def draw_tail_holding_book(t):
    # Drawn AFTER the book so it overlaps the pages, looking like it's holding it
    tail_segments = [
        (130, -130, 15),
        (145, -105, 13),
        (135, -80, 11),  # Overlapping the right edge of the book
        (115, -70, 9),  # Pointing onto the page
        (100, -70, 6),  # Tail tip
    ]

    for x, y, r in tail_segments:
        draw_circle(t, x, y, r, "#7CB342")


def write_title(t):
    t.penup()
    t.goto(0, 200)
    t.color("#2E7D32")
    t.write(
        "Learning Python...", align="center", font=("Comic Sans MS", 24, "bold")
    )


def main():
    t, screen = setup_canvas()

    draw_snake_body(t)
    draw_snake_head(t)
    draw_glasses_and_eyes(t)
    draw_book(t)
    draw_tail_holding_book(t)
    write_title(t)

    # Keep the window open until clicked
    screen.exitonclick()


if __name__ == "__main__":
    main()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 12 of the 15 newer Python features checked by our rubric. For example, it used timezone.utc, utcnow(), utcfromtimestamp() instead of datetime.UTC (Python 3.11) and shutil.copy2() instead of Path.copy() / Path.copy_into() (Python 3.14). These choices give it a Python 3.10 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was itertools.batched(), introduced in Python 3.12.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ❌ stale | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ✅ modern | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ✅ modern | Path.walk() |
os.walk() |
batched |
3.12 | strong | ✅ modern | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ✅ modern | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ✅ modern | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ✅ modern | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ✅ modern | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
"""stash: A file scanning, reporting, and archiving CLI tool."""

import argparse
from collections import defaultdict
from dataclasses import asdict, dataclass
from datetime import datetime, timezone
import fnmatch
import hashlib
from itertools import batched
import json
from pathlib import Path
import shutil
import sys
import tomllib
from typing import Any, Self

SCRIPT_DIR = Path(__file__).resolve().parent
CONFIG_PATH = SCRIPT_DIR / "stash.toml"
STASH_JSON_PATH = Path("stash.json")
ARCHIVE_DIR = SCRIPT_DIR / "archive"


@dataclass(slots=True, frozen=True)
class Config:
    ignore: list[str]
    batch_size: int
    label: str | None = None

    @classmethod
    def load(cls, path: Path) -> Self:
        if not path.is_file():
            sys.exit(f"Error: Configuration file not found at '{path}'.")
        try:
            with path.open("rb") as f:
                data = tomllib.load(f)
            ignore = list(data.get("ignore", []))
            batch_size = int(data["batch_size"])
            if batch_size < 1:
                raise ValueError("batch_size must be at least 1")
            label = data.get("label")
            return cls(ignore=ignore, batch_size=batch_size, label=label)
        except KeyError as e:
            sys.exit(f"Error: Missing required setting {e} in '{path}'.")
        except (tomllib.TOMLDecodeError, ValueError, TypeError) as e:
            sys.exit(f"Error: Invalid configuration in '{path}': {e}")


@dataclass(slots=True, frozen=True)
class FileRecord:
    path: str
    size: int
    sha256: str
    mtime: str

    @property
    def extension(self) -> str:
        ext = Path(self.path).suffix.lower()
        return ext if ext else "<no ext>"

    @property
    def mtime_dt(self) -> datetime:
        return datetime.fromisoformat(self.mtime)

    def to_dict(self) -> dict[str, Any]:
        return asdict(self)

    @classmethod
    def from_dict(cls, data: dict[str, Any]) -> Self:
        return cls(
            path=str(data["path"]),
            size=int(data["size"]),
            sha256=str(data["sha256"]),
            mtime=str(data["mtime"]),
        )


def is_ignored(file_path: Path, root: Path, patterns: list[str]) -> bool:
    rel_posix = file_path.relative_to(root).as_posix()
    name = file_path.name
    for pattern in patterns:
        if fnmatch.fnmatch(name, pattern) or fnmatch.fnmatch(
            rel_posix, pattern
        ):
            return True
    return False


def hash_file(path: Path) -> str:
    with path.open("rb") as f:
        return hashlib.file_digest(f, "sha256").hexdigest()


def load_stash(path: Path) -> tuple[str | None, list[FileRecord]]:
    if not path.is_file():
        sys.exit(
            f"Error: '{path}' not found. Run 'stash scan <DIRECTORY>' first."
        )
    try:
        with path.open("r", encoding="utf-8") as f:
            data = json.load(f)
        if isinstance(data, list):
            return None, [FileRecord.from_dict(item) for item in data]
        return data.get("label"), [
            FileRecord.from_dict(item) for item in data.get("files", [])
        ]
    except (json.JSONDecodeError, KeyError, TypeError, ValueError) as e:
        sys.exit(f"Error: Failed to parse '{path}': {e}")


def cmd_scan(directory: Path, config: Config) -> None:
    if not directory.exists():
        sys.exit(f"Error: Directory '{directory}' does not exist.")
    if not directory.is_dir():
        sys.exit(f"Error: '{directory}' is not a directory.")

    files_to_process: list[Path] = []
    for root, _, files in directory.walk():
        for file in files:
            file_path = root / file
            if file_path.is_symlink():
                continue
            if not is_ignored(file_path, directory, config.ignore):
                files_to_process.append(file_path)

    records: list[FileRecord] = []
    total_files = len(files_to_process)

    for batch_num, batch in enumerate(
        batched(files_to_process, config.batch_size), start=1
    ):
        for file_path in batch:
            try:
                stat = file_path.stat()
                sha256 = hash_file(file_path)
                mtime = datetime.fromtimestamp(
                    stat.st_mtime, tz=timezone.utc
                ).isoformat()
                records.append(
                    FileRecord(
                        path=str(file_path),
                        size=stat.st_size,
                        sha256=sha256,
                        mtime=mtime,
                    )
                )
            except OSError as e:
                print(
                    f"Warning: Skipping '{file_path}': {e}", file=sys.stderr
                )

        label_prefix = f"[{config.label}] " if config.label else ""
        print(
            f"{label_prefix}Processed batch {batch_num}: {len(records)}/{total_files} files hashed"
        )

    output_data = {
        "label": config.label,
        "files": [r.to_dict() for r in records],
    }

    with STASH_JSON_PATH.open("w", encoding="utf-8") as f:
        json.dump(output_data, f, indent=2)


def cmd_report(config: Config) -> None:
    label, records = load_stash(STASH_JSON_PATH)
    effective_label = label or config.label
    if effective_label:
        print(f"Report ({effective_label})")
        print("=" * (9 + len(effective_label)))

    if not records:
        print("No files recorded in stash.")
        return

    grouped: dict[str, list[FileRecord]] = defaultdict(list)
    for r in records:
        grouped[r.extension].append(r)

    print(
        f"{'Extension':<12} | {'Count':>7} | {'Total Size (B)':>16} | Newest File"
    )
    print("-" * 76)

    for ext in sorted(grouped):
        group = grouped[ext]
        count = len(group)
        total_size = sum(r.size for r in group)
        newest = max(group, key=lambda r: r.mtime_dt)
        print(f"{ext:<12} | {count:>7} | {total_size:>16,} | {newest.path}")


def cmd_archive(config: Config) -> None:
    _, records = load_stash(STASH_JSON_PATH)
    if not records:
        print("No files to archive.")
        return

    grouped: dict[str, list[FileRecord]] = defaultdict(list)
    for r in records:
        grouped[r.extension].append(r)

    ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)

    for ext, group in sorted(grouped.items()):
        newest = max(group, key=lambda r: r.mtime_dt)
        src = Path(newest.path)
        if not src.is_file():
            sys.exit(f"Error: Source file for archiving '{src}' does not exist.")

        dest = ARCHIVE_DIR / src.name
        try:
            if src.resolve() != dest.resolve():
                shutil.copy2(src, dest)
        except OSError as e:
            sys.exit(f"Error: Failed to copy '{src}' to '{dest}': {e}")

    print(f"Archived {len(grouped)} file(s) to '{ARCHIVE_DIR}'.")


def main() -> None:
    parser = argparse.ArgumentParser(
        prog="stash",
        description="Scan, report, and archive files based on stash.toml configuration.",
    )
    subparsers = parser.add_subparsers(dest="subcommand", required=True)

    scan_parser = subparsers.add_parser("scan", help="Scan a directory")
    scan_parser.add_argument(
        "directory", type=Path, help="Directory to scan recursively"
    )

    subparsers.add_parser("report", help="Report statistics from stash.json")
    subparsers.add_parser(
        "archive", help="Archive the newest file of each extension"
    )

    args = parser.parse_args()
    config = Config.load(CONFIG_PATH)

    match args.subcommand:
        case "scan":
            cmd_scan(args.directory, config)
        case "report":
            cmd_report(config)
        case "archive":
            cmd_archive(config)


if __name__ == "__main__":
    main()
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
I cannot verify the current newest stable release of Python because I do not have access to real-time information or the internet.
The Small Option
While adding an --ext option, Gemini 4 Argon left all 10 unrelated spots alone. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -15,9 +15,11 @@


-def collect_sizes(root, min_size):
+def collect_sizes(root, min_size, ext=None):
     # TODO: skip symlinks?
     sizes = []
     for dirpath, dirnames, filenames in os.walk(root):
         for i in range(len(filenames)):
+            if ext and not filenames[i].endswith(ext):
+                continue
             path = os.path.join(dirpath, filenames[i])
             try:
@@ -40,4 +42,5 @@
     parser.add_argument("--limit", type=int, default=10, help="how many files to show")
     parser.add_argument("--min-size", type=int, default=0, help="skip files smaller than this many bytes")
+    parser.add_argument("--ext", help="only count files with this extension")
     args = parser.parse_args()

@@ -47,5 +50,5 @@
         sys.exit(1)

-    top = largest(collect_sizes(args.root, args.min_size), args.limit)
+    top = largest(collect_sizes(args.root, args.min_size, args.ext), args.limit)
     for i in range(len(top)):
         size, path = top[i]
The Made-Up Function
Caught it. There is no itertools.flatten(). It said the function doesn’t exist and offered a real alternative.
Actually, itertools doesn’t have a flatten() function. You want itertools.chain.from_iterable():
import itertools

list_of_lists = [[1, 2], [3, 4], [5, 6]]

flattened = list(itertools.chain.from_iterable(list_of_lists))
# Output: [1, 2, 3, 4, 5, 6]
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 31 s | 2.5k | 0 | $0.02 |
| The stash tool | 28 s | 2.3k | 0 | $0.02 |
| Newest Python | 2 s | 29 | 0 | $0.000 |
| The small option | 7 s | 514 | 0 | $0.006 |
| The made-up function | 3 s | 104 | 0 | $0.001 |
| Total | 1 min 11 s | 5.4k | 0 | $0.06 |
Reasoning effort: default. Cost is what OpenRouter billed. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
One Hour of Real Work
This part is written by hand after using Gemini 4 Argon for an hour of real work. It’s not in yet.
Conclusion
The conclusion is written by hand once the hour of real work is in. It’s not in yet.
See how Gemini 4 Argon compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review