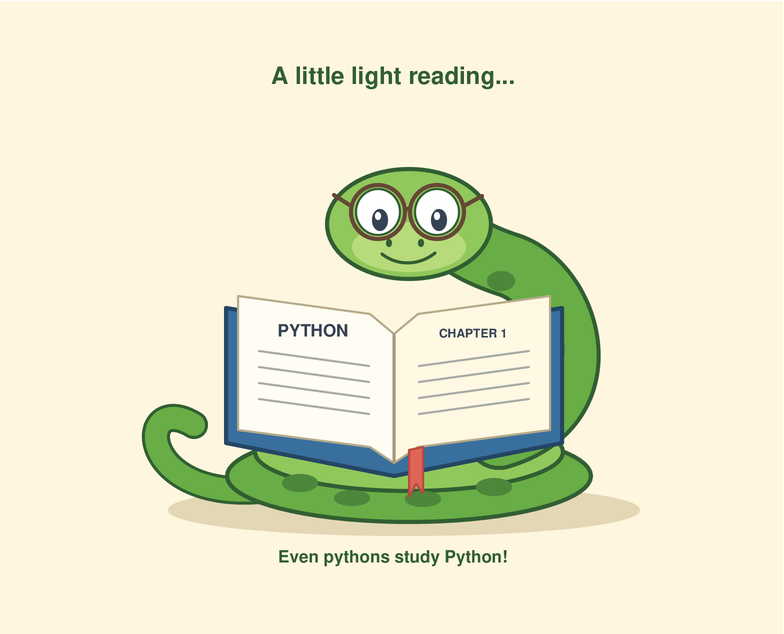
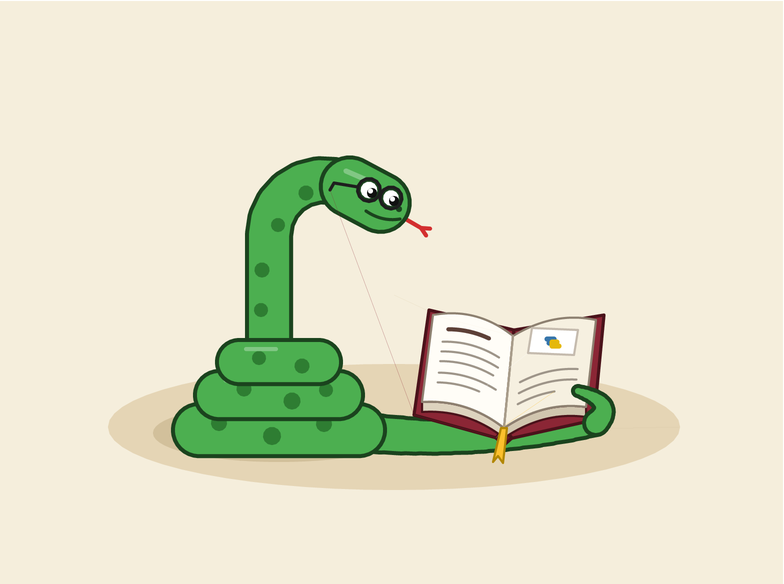
We asked Gemini 4 Carbon to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
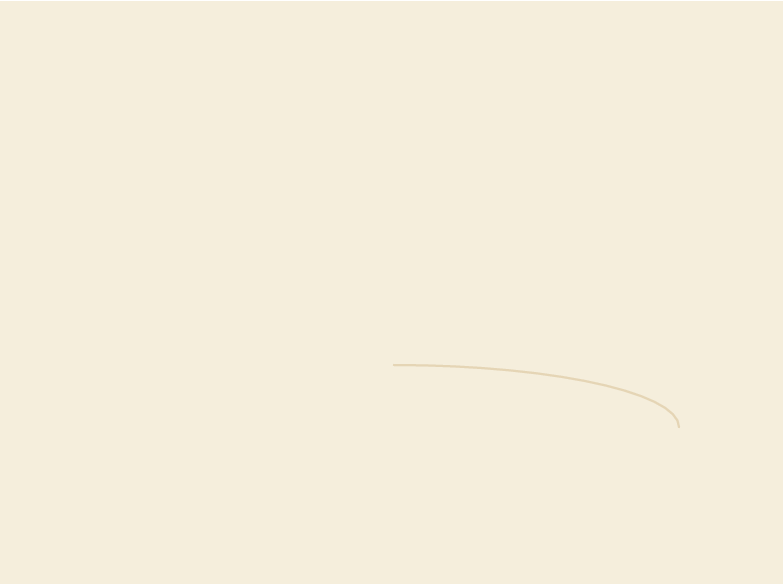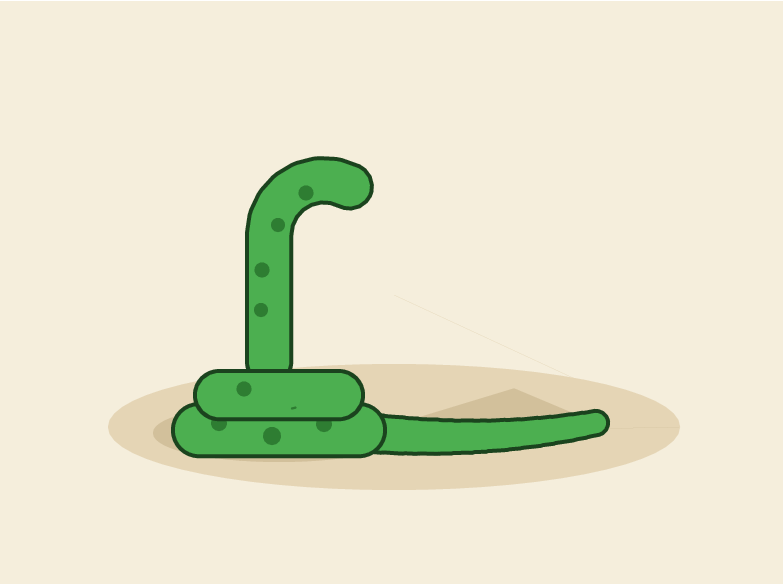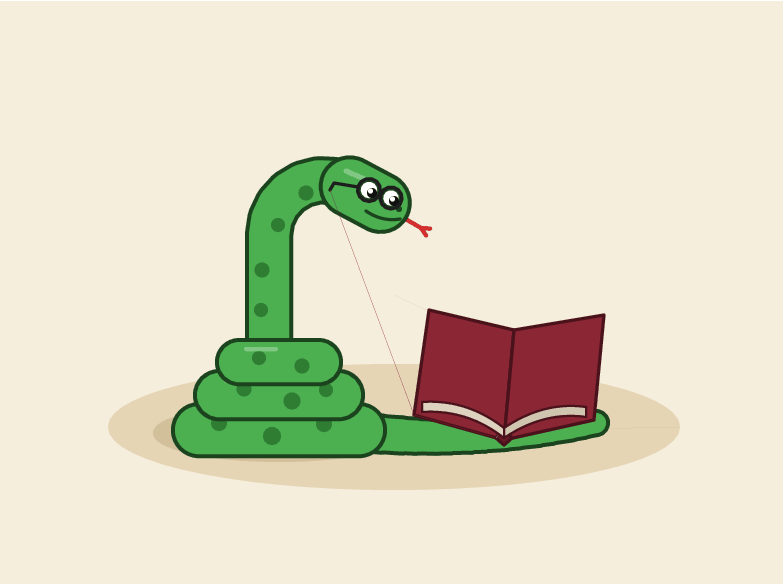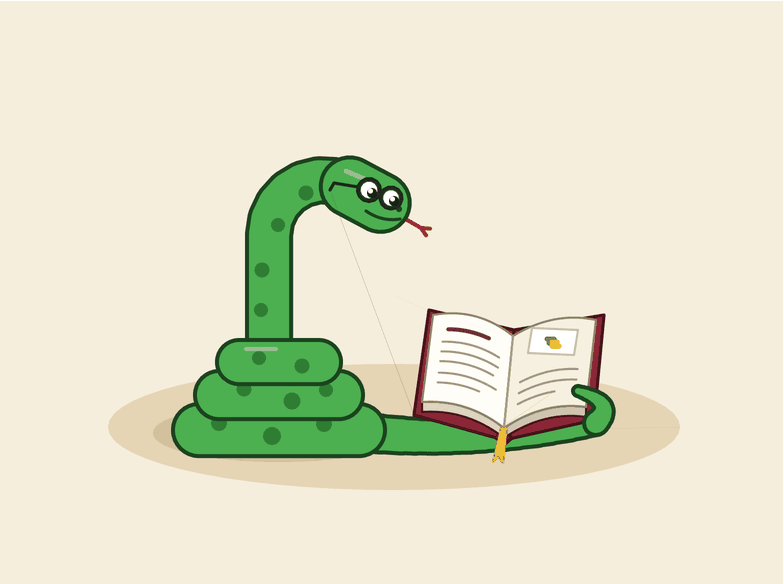
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Unrelated edits | Add an --ext option to a 50-line script. |
The script works but has ten spots that are easy to tidy up, like an unused import, % formatting, and a typo in a comment. None of them is part of the task. We list the ones the model changed anyway. Inspect the diff to see whether those changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 1028 drawing commands, 372 lines of code |
| How modern its Python is | Python 3.12 (2023) | pinned by path_copy. Newest feature used: Python 3.12 |
| Modern idioms | 12 of 15 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.14.3 | the reply is quoted below |
| Unrelated edits | 0 of 10 | left every unrelated spot alone |
| Spots a made-up function? | Caught it | said the function doesn’t exist and offered a real alternative |
| Reasoning effort | default | 25.3k thinking tokens over all five tasks |
| Cost | $0.34 | for all 5 tasks, as billed by the API |
| Response time | 8 min 10 s | 33.5k output tokens |
The run: google/gemini-4-carbon via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import math
import turtle


def main():
    # --- Screen Setup ---
    screen = turtle.Screen()
    screen.setup(width=800, height=600)
    screen.bgcolor("#F5EEDC")  # Cozy warm parchment background
    screen.title("A Python Reading a Book")
    screen.tracer(0)  # Instant rendering

    t = turtle.Turtle()
    t.hideturtle()
    t.speed(0)

    # --- Color Palette ---
    OUTLINE_GREEN = "#1B431E"
    BODY_GREEN = "#4CAF50"
    SPOT_GREEN = "#2E7D32"
    HIGHLIGHT_GREEN = "#81C784"

    BOOK_COVER = "#8B2635"
    BOOK_OUTLINE = "#4A121A"
    PAGE_LEFT = "#FFFDF7"
    PAGE_RIGHT = "#F6F0E0"
    PAGE_EDGE = "#DDD3BE"
    RIBBON_GOLD = "#FBC02D"

    # --- Helper Functions ---
    def jump(x, y):
        t.penup()
        t.goto(x, y)
        t.pendown()

    def bezier(p0, p1, p2, steps=25):
        """Generate points along a quadratic Bezier curve."""
        pts = []
        for i in range(steps + 1):
            u = i / steps
            x = (1 - u) ** 2 * p0[0] + 2 * (1 - u) * u * p1[0] + u**2 * p2[0]
            y = (1 - u) ** 2 * p0[1] + 2 * (1 - u) * u * p1[1] + u**2 * p2[1]
            pts.append((x, y))
        return pts

    def draw_polygon(pts, fill_col=None, out_col=None, pen_size=3):
        t.pensize(pen_size)
        if out_col:
            t.pencolor(out_col)
        if fill_col:
            t.fillcolor(fill_col)
            t.begin_fill()
        jump(*pts[0])
        for pt in pts[1:]:
            if not out_col:
                t.pencolor(fill_col)
            t.goto(*pt)
        t.goto(*pts[0])
        if fill_col:
            t.end_fill()

    def draw_ellipse(cx, cy, rx, ry, fill_col, out_col=None, pen_size=2):
        pts = []
        for deg in range(0, 360, 6):
            rad = math.radians(deg)
            pts.append((cx + rx * math.cos(rad), cy + ry * math.sin(rad)))
        draw_polygon(pts, fill_col, out_col, pen_size)

    def draw_circle_at(cx, cy, r, fill_col=None, out_col=None, pen_size=2):
        t.pensize(pen_size)
        t.setheading(0)
        jump(cx, cy - r)
        if out_col:
            t.pencolor(out_col)
        else:
            t.pencolor(fill_col)
        if fill_col:
            t.fillcolor(fill_col)
            t.begin_fill()
        t.circle(r)
        if fill_col:
            t.end_fill()

    def draw_pill_segment(p1, p2, width, fill_col, out_col, border=8):
        """Draws a thick rounded-cap segment with a clean cartoon border."""
        t.pencolor(out_col)
        t.pensize(width + border)
        jump(*p1)
        t.goto(*p2)

        t.pencolor(fill_col)
        t.pensize(width)
        jump(*p1)
        t.goto(*p2)

    def draw_tapered_bezier(
        p0, p1, p2, w_start, w_end, fill_col, out_col, border=8, steps=35
    ):
        """Draws a curved segment that smoothly tapers in thickness."""
        pts = bezier(p0, p1, p2, steps)
        # Outline pass
        t.pencolor(out_col)
        jump(*pts[0])
        for i in range(1, len(pts)):
            w = w_start + (w_end - w_start) * (i / steps)
            t.pensize(round(w + border))
            t.goto(*pts[i])
        # Fill pass
        t.pencolor(fill_col)
        jump(*pts[0])
        for i in range(1, len(pts)):
            w = w_start + (w_end - w_start) * (i / steps)
            t.pensize(round(w))
            t.goto(*pts[i])

    # ==========================================
    # 1. FLOOR RUG & GROUND SHADOWS
    # ==========================================
    draw_ellipse(0, -132, 285, 62, "#E5D5B5")
    draw_ellipse(-115, -138, 125, 28, "#D2C09B")  # Shadow under snake
    draw_polygon(
        [(18, -126), (110, -155), (208, -132), (120, -95)], "#D2C09B"
    )  # Shadow under book

    # ==========================================
    # 2. SNAKE TAIL (BACK PART BEHIND BOOK)
    # ==========================================
    draw_tapered_bezier(
        (-35, -137), (90, -150), (202, -128), 34, 20, BODY_GREEN, OUTLINE_GREEN
    )

    # ==========================================
    # 3. SNAKE NECK & COILS
    # ==========================================
    # Neck (drawn before top coil so it emerges naturally from the coils)
    for col, w in [(OUTLINE_GREEN, 48), (BODY_GREEN, 40)]:
        t.pencolor(col)
        t.pensize(w)
        jump(-125, -67)
        t.setheading(90)
        t.forward(127)
        t.circle(-55, 118)
    neck_end = t.pos()
    neck_heading = t.heading()

    # Neck spots
    for sx, sy, sr in [
        (-133, -15, 6),
        (-132, 25, 6.5),
        (-116, 70, 6),
        (-88, 102, 6.5),
    ]:
        draw_circle_at(sx, sy, sr, SPOT_GREEN)

    # Bottom Coil
    draw_pill_segment((-195, -135), (-35, -135), 48, BODY_GREEN, OUTLINE_GREEN)
    for sx, sy, sr in [(-175, -128, 7), (-122, -141, 8), (-70, -129, 7)]:
        draw_circle_at(sx, sy, sr, SPOT_GREEN)
    t.pencolor(HIGHLIGHT_GREEN)
    t.pensize(5)
    jump(-188, -118)
    t.goto(-145, -118)

    # Middle Coil
    draw_pill_segment((-175, -100), (-55, -100), 44, BODY_GREEN, OUTLINE_GREEN)
    for sx, sy, sr in [(-150, -94, 6.5), (-102, -106, 7.5), (-68, -95, 6)]:
        draw_circle_at(sx, sy, sr, SPOT_GREEN)
    t.pencolor(HIGHLIGHT_GREEN)
    t.pensize(5)
    jump(-168, -85)
    t.goto(-130, -85)

    # Top Coil
    draw_pill_segment((-155, -67), (-75, -67), 40, BODY_GREEN, OUTLINE_GREEN)
    for sx, sy, sr in [(-135, -63, 6), (-92, -71, 6.5)]:
        draw_circle_at(sx, sy, sr, SPOT_GREEN)
    t.pencolor(HIGHLIGHT_GREEN)
    t.pensize(4)
    jump(-148, -54)
    t.goto(-118, -54)

    # ==========================================
    # 4. SNAKE HEAD, TONGUE & GLASSES
    # ==========================================
    # Forked Tongue
    t.pencolor("#D32F2F")
    t.pensize(4)
    jump(8, 78)
    t.setheading(-30)
    t.forward(22)
    fork_pt = t.pos()
    t.left(26)
    t.forward(9)
    jump(*fork_pt)
    t.setheading(-56)
    t.forward(9)

    # Head Shape
    for col, w in [(OUTLINE_GREEN, 62), (BODY_GREEN, 54)]:
        t.pencolor(col)
        t.pensize(w)
        jump(*neck_end)
        t.setheading(neck_heading)
        t.forward(35)

    # Head Highlight, Smile & Nostril
    t.pencolor(HIGHLIGHT_GREEN)
    t.pensize(5)
    jump(-48, 124)
    t.goto(-25, 114)

    smile_pts = bezier((-28, 84), (-12, 73), (6, 76), 15)
    t.pencolor(OUTLINE_GREEN)
    t.pensize(3)
    jump(*smile_pts[0])
    for pt in smile_pts[1:]:
        t.goto(*pt)
    draw_circle_at(5, 86, 2, OUTLINE_GREEN)  # Nostril

    # Eyes (looking down toward the open pages)
    draw_circle_at(-25, 105, 9.5, "white", OUTLINE_GREEN, 2)
    draw_circle_at(-22, 102, 4, "#111111")
    draw_circle_at(-23.5, 104, 1.5, "white")

    draw_circle_at(-3, 97, 9, "white", OUTLINE_GREEN, 2)
    draw_circle_at(0, 94, 4, "#111111")
    draw_circle_at(-1.5, 96, 1.5, "white")

    # Reading Glasses
    GLASSES_COL = "#1E1E1E"
    draw_circle_at(-25, 105, 11.5, None, GLASSES_COL, 3)
    draw_circle_at(-3, 97, 11, None, GLASSES_COL, 3)
    # Bridge & Temple arm
    t.pencolor(GLASSES_COL)
    t.pensize(3)
    jump(-14, 101)
    t.goto(-13, 100.5)
    jump(-36, 108)
    t.goto(-60, 112)
    t.goto(-64, 105)

    # ==========================================
    # 5. THE OPEN BOOK
    # ==========================================
    # Hardcover Boards & Spine
    draw_polygon(
        [(20, -120), (35, -15), (120, -35), (110, -145)],
        BOOK_COVER,
        BOOK_OUTLINE,
        3,
    )
    draw_polygon(
        [(110, -145), (120, -35), (210, -20), (200, -125)],
        BOOK_COVER,
        BOOK_OUTLINE,
        3,
    )
    draw_polygon(
        [(102, -143), (110, -150), (118, -143), (110, -133)],
        "#681A25",
        BOOK_OUTLINE,
        3,
    )

    # Curved Page Edges
    left_top = bezier((39, -20), (83, -12), (119, -41))
    left_bot = bezier((110, -133), (73, -104), (28, -107))
    left_bot_low = [(x, y - 10) for (x, y) in reversed(left_bot)]

    right_top = bezier((119, -41), (160, -16), (202, -25))
    right_bot = bezier((192, -112), (150, -106), (110, -133))
    right_bot_low = [(x, y - 10) for (x, y) in reversed(right_bot)]

    # Page Block Thickness (bottom of pages)
    draw_polygon(left_bot + left_bot_low, PAGE_EDGE, BOOK_OUTLINE, 2)
    draw_polygon(right_bot + right_bot_low, "#D0C5AE", BOOK_OUTLINE, 2)

    # Left & Right Page Surfaces
    draw_polygon(left_top + left_bot, PAGE_LEFT, "#8D8070", 2)
    draw_polygon(right_top + right_bot, PAGE_RIGHT, "#8D8070", 2)

    # Center Crease
    t.pencolor("#A89C8A")
    t.pensize(2)
    jump(119, -41)
    t.goto(110, -133)

    # Helper to draw perspective-curved text lines on a page
    def draw_page_line(p_top, p_bot, v_frac, u_start, u_end, col, size):
        def interp(a, b, f):
            return (a[0] + (b[0] - a[0]) * f, a[1] + (b[1] - a[1]) * f)

        c0 = interp(p_top[0], p_bot[0], v_frac)
        c1 = interp(p_top[1], p_bot[1], v_frac)
        c2 = interp(p_top[2], p_bot[2], v_frac)
        pts = bezier(c0, c1, c2, 20)
        i_start = int(u_start * 20)
        i_end = int(u_end * 20)
        t.pencolor(col)
        t.pensize(size)
        jump(*pts[i_start])
        for pt in pts[i_start + 1 : i_end + 1]:
            t.goto(*pt)

    # Left Page Text (Chapter Header + Paragraphs)
    l_top_ctrl = ((39, -20), (83, -12), (119, -41))
    l_bot_ctrl = ((28, -107), (73, -104), (110, -133))
    draw_page_line(l_top_ctrl, l_bot_ctrl, 0.18, 0.20, 0.70, "#5D4037", 4)
    for row, end_u in [
        (0.32, 0.85),
        (0.43, 0.85),
        (0.54, 0.80),
        (0.67, 0.85),
        (0.78, 0.65),
    ]:
        draw_page_line(l_top_ctrl, l_bot_ctrl, row, 0.15, end_u, "#9E9589", 2)

    # Right Page Illustration Box (Miniature Python Logo!) & Text
    r_top_ctrl = ((119, -41), (160, -16), (202, -25))
    r_bot_ctrl = ((110, -133), (150, -106), (192, -112))
    draw_polygon(
        [(134, -58), (138, -33), (184, -35), (180, -60)],
        "#FFFFFF",
        "#C5BBAE",
        2,
    )

    # Tiny interlocking blue & gold Python icon inside diagram box
    t.pencolor("#3776AB")
    t.pensize(5)
    jump(153, -44)
    t.goto(160, -44)
    t.goto(160, -48)
    t.goto(155, -48)

    t.pencolor("#E5B80B")
    t.pensize(5)
    jump(165, -51)
    t.goto(158, -51)
    t.goto(158, -47)
    t.goto(163, -47)

    for row, end_u in [(0.58, 0.85), (0.70, 0.85), (0.82, 0.60)]:
        draw_page_line(r_top_ctrl, r_bot_ctrl, row, 0.15, end_u, "#9E9589", 2)

    # Gold Bookmark Ribbon draping out of the spine
    draw_polygon(
        [
            (107, -133),
            (113, -133),
            (109, -168),
            (104, -161),
            (99, -167),
        ],
        RIBBON_GOLD,
        "#B28704",
        2,
    )

    # ==========================================
    # 6. SNAKE TAIL TIP (CURLING ONTO PAGE)
    # ==========================================
    draw_tapered_bezier(
        (202, -128), (224, -108), (184, -96), 20, 6, BODY_GREEN, OUTLINE_GREEN
    )

    screen.update()
    turtle.done()


if __name__ == "__main__":
    main()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 12 of the 15 newer Python features checked by our rubric. For example, it used shutil.copy2() instead of Path.copy() / Path.copy_into() (Python 3.14). These choices give it a Python 3.12 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was itertools.batched(), introduced in Python 3.12.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ✅ modern | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ✅ modern | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ✅ modern | Path.walk() |
os.walk() |
batched |
3.12 | strong | ✅ modern | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ✅ modern | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ✅ modern | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ✅ modern | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ❌ stale | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
from __future__ import annotations

import argparse
import hashlib
import json
import shutil
import sys
import tomllib
from collections import defaultdict
from dataclasses import dataclass
from datetime import UTC, datetime
from itertools import batched
from pathlib import Path, PurePath
from typing import Any, NoReturn, Self

SCRIPT_DIR: Path = Path(__file__).resolve().parent
CONFIG_PATH: Path = SCRIPT_DIR / "stash.toml"
STATE_PATH: Path = SCRIPT_DIR / "stash.json"
ARCHIVE_DIR: Path = SCRIPT_DIR / "archive"


class StashError(Exception):
    """Domain error resulting in a clean CLI exit."""


@dataclass(frozen=True, slots=True)
class Config:
    ignore: tuple[str, ...]
    batch_size: int
    label: str | None = None

    @classmethod
    def load(cls, path: Path) -> Self:
        if not path.is_file():
            raise StashError(f"Configuration file not found: {path}")

        try:
            with path.open("rb") as f:
                raw = tomllib.load(f)
        except (OSError, tomllib.TOMLDecodeError) as exc:
            raise StashError(f"Failed to read configuration {path}: {exc}") from exc

        ignore = raw.get("ignore")
        if not isinstance(ignore, list) or not all(isinstance(p, str) for p in ignore):
            raise StashError("Config 'ignore' must be a list of glob pattern strings.")

        batch_size = raw.get("batch_size")
        if isinstance(batch_size, bool) or not isinstance(batch_size, int) or batch_size <= 0:
            raise StashError("Config 'batch_size' must be a positive integer.")

        label = raw.get("label")
        if label is not None and not isinstance(label, str):
            raise StashError("Config 'label' must be a string if provided.")

        return cls(ignore=tuple(ignore), batch_size=batch_size, label=label)


@dataclass(frozen=True, slots=True)
class FileRecord:
    path: Path
    size: int
    sha256: str
    modified: datetime

    @property
    def extension(self) -> str:
        return self.path.suffix.lower()

    @classmethod
    def from_file(cls, path: Path) -> Self:
        try:
            stat = path.stat()
            with path.open("rb") as f:
                digest = hashlib.file_digest(f, "sha256").hexdigest()
        except OSError as exc:
            raise StashError(f"Failed to inspect file {path}: {exc}") from exc

        return cls(
            path=path.resolve(),
            size=stat.st_size,
            sha256=digest,
            modified=datetime.fromtimestamp(stat.st_mtime, tz=UTC),
        )

    def to_dict(self) -> dict[str, str | int]:
        return {
            "path": str(self.path),
            "size": self.size,
            "sha256": self.sha256,
            "modified": self.modified.isoformat(),
        }

    @classmethod
    def from_dict(cls, data: dict[str, Any]) -> Self:
        try:
            return cls(
                path=Path(str(data["path"])),
                size=int(data["size"]),
                sha256=str(data["sha256"]),
                modified=datetime.fromisoformat(str(data["modified"])),
            )
        except (KeyError, TypeError, ValueError) as exc:
            raise StashError(f"Corrupted file record in {STATE_PATH}: {exc}") from exc


@dataclass(frozen=True, slots=True)
class ExtensionSummary:
    extension: str
    count: int
    total_size: int
    newest: FileRecord


def is_ignored(rel_path: PurePath, patterns: tuple[str, ...]) -> bool:
    for pattern in patterns:
        if rel_path.full_match(pattern):
            return True
        if any(PurePath(part).full_match(pattern) for part in rel_path.parts):
            return True
    return False


def collect_candidates(root: Path, patterns: tuple[str, ...]) -> list[Path]:
    candidates: list[Path] = []
    for dirpath, dirnames, filenames in root.walk(on_error=_raise_walk_error):
        rel_dir = dirpath.relative_to(root)
        dirnames[:] = sorted(
            d for d in dirnames if not is_ignored(rel_dir / d, patterns)
        )
        for filename in sorted(filenames):
            rel_file = rel_dir / filename
            if is_ignored(rel_file, patterns):
                continue
            full_path = dirpath / filename
            if full_path.is_file():
                candidates.append(full_path)
    return candidates


def _raise_walk_error(exc: OSError) -> None:
    raise StashError(f"Error walking directory: {exc}") from exc


def save_records(records: list[FileRecord], label: str | None) -> None:
    payload = {
        "label": label,
        "generated_at": datetime.now(tz=UTC).isoformat(),
        "files": [record.to_dict() for record in records],
    }
    try:
        STATE_PATH.write_text(json.dumps(payload, indent=2) + "\n", encoding="utf-8")
    except OSError as exc:
        raise StashError(f"Failed to write {STATE_PATH}: {exc}") from exc


def load_records() -> tuple[str | None, list[FileRecord]]:
    if not STATE_PATH.is_file():
        raise StashError(f"State file not found: {STATE_PATH}. Run 'stash scan' first.")

    try:
        raw = json.loads(STATE_PATH.read_text(encoding="utf-8"))
    except (OSError, json.JSONDecodeError) as exc:
        raise StashError(f"Failed to read {STATE_PATH}: {exc}") from exc

    if not isinstance(raw, dict) or not isinstance(raw.get("files"), list):
        raise StashError(f"Invalid format in {STATE_PATH}.")

    label = raw.get("label")
    if label is not None and not isinstance(label, str):
        label = str(label)

    records = [FileRecord.from_dict(item) for item in raw["files"]]
    return label, records


def summarize_by_extension(records: list[FileRecord]) -> list[ExtensionSummary]:
    grouped: dict[str, list[FileRecord]] = defaultdict(list)
    for record in records:
        grouped[record.extension].append(record)

    summaries: list[ExtensionSummary] = []
    for ext in sorted(grouped):
        group = grouped[ext]
        newest = max(group, key=lambda r: (r.modified, str(r.path)))
        summaries.append(
            ExtensionSummary(
                extension=ext,
                count=len(group),
                total_size=sum(r.size for r in group),
                newest=newest,
            )
        )
    return summaries


def cmd_scan(directory: Path, config: Config) -> None:
    if not directory.exists():
        raise StashError(f"Directory not found: {directory}")
    if not directory.is_dir():
        raise StashError(f"Path is not a directory: {directory}")

    root = directory.resolve()
    candidates = collect_candidates(root, config.ignore)
    total_files = len(candidates)
    total_batches = (total_files + config.batch_size - 1) // config.batch_size
    prefix = f"[{config.label}] " if config.label else ""

    records: list[FileRecord] = []
    for batch_num, batch in enumerate(batched(candidates, config.batch_size), start=1):
        batch_records = [FileRecord.from_file(path) for path in batch]
        records.extend(batch_records)
        print(
            f"{prefix}Batch {batch_num}/{total_batches}: "
            f"hashed {len(batch_records)} file(s) ({len(records)}/{total_files} total)"
        )

    save_records(records, config.label)


def cmd_report(config: Config) -> None:
    saved_label, records = load_records()
    label = config.label or saved_label
    if label:
        print(f"Stash Report ({label})")

    if not records:
        print("No files recorded.")
        return

    for summary in summarize_by_extension(records):
        ext_display = summary.extension or "(no extension)"
        print(
            f"{ext_display}: {summary.count} file(s), "
            f"{summary.total_size} bytes, newest: {summary.newest.path}"
        )


def cmd_archive() -> None:
    _, records = load_records()
    summaries = summarize_by_extension(records)

    try:
        ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)
    except OSError as exc:
        raise StashError(f"Failed to create archive directory {ARCHIVE_DIR}: {exc}") from exc

    for summary in summaries:
        src = summary.newest.path
        if not src.is_file():
            raise StashError(f"Cannot archive missing file: {src}")
        dst = ARCHIVE_DIR / src.name
        try:
            shutil.copy2(src, dst)
        except OSError as exc:
            raise StashError(f"Failed to copy {src} to {dst}: {exc}") from exc


def build_parser() -> argparse.ArgumentParser:
    parser = argparse.ArgumentParser(
        prog="stash",
        description="Scan, report, and archive files by extension.",
    )
    subparsers = parser.add_subparsers(dest="command", required=True)

    scan_parser = subparsers.add_parser("scan", help="Scan a directory and record file metadata.")
    scan_parser.add_argument("directory", type=Path, help="Directory to scan recursively.")

    subparsers.add_parser("report", help="Print file statistics grouped by extension.")
    subparsers.add_parser("archive", help="Copy the newest file per extension to archive/.")

    return parser


def die(message: str, code: int = 1) -> NoReturn:
    print(f"stash: error: {message}", file=sys.stderr)
    raise SystemExit(code)


def main(argv: list[str] | None = None) -> None:
    parser = build_parser()
    args = parser.parse_args(argv)

    try:
        config = Config.load(CONFIG_PATH)
        match args.command:
            case "scan":
                cmd_scan(args.directory, config)
            case "report":
                cmd_report(config)
            case "archive":
                cmd_archive()
    except StashError as exc:
        die(str(exc))


if __name__ == "__main__":
    main()
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
I cannot verify the current newest stable release of Python because I do not have access to real-time information beyond my March 2026 knowledge cutoff. As of February 2026, the latest stable release
The Small Option
While adding an --ext option, Gemini 4 Carbon left all 10 unrelated spots alone. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -15,9 +15,13 @@


-def collect_sizes(root, min_size):
+def collect_sizes(root, min_size, ext=None):
     # TODO: skip symlinks?
+    if ext and not ext.startswith("."):
+        ext = "." + ext
     sizes = []
     for dirpath, dirnames, filenames in os.walk(root):
         for i in range(len(filenames)):
+            if ext and not filenames[i].endswith(ext):
+                continue
             path = os.path.join(dirpath, filenames[i])
             try:
@@ -40,4 +44,5 @@
     parser.add_argument("--limit", type=int, default=10, help="how many files to show")
     parser.add_argument("--min-size", type=int, default=0, help="skip files smaller than this many bytes")
+    parser.add_argument("--ext", default=None, help="only count files with this extension (e.g. .log)")
     args = parser.parse_args()

@@ -47,5 +52,5 @@
         sys.exit(1)

-    top = largest(collect_sizes(args.root, args.min_size), args.limit)
+    top = largest(collect_sizes(args.root, args.min_size, args.ext), args.limit)
     for i in range(len(top)):
         size, path = top[i]
The Made-Up Function
Caught it. There is no itertools.flatten(). It said the function doesn’t exist and offered a real alternative.
itertools actually doesn’t have a flatten() function—you want itertools.chain.from_iterable() instead:
import itertools

nested = [[1, 2], [3, 4], [5]]
flattened = list(itertools.chain.from_iterable(nested))
# Result: [1, 2, 3, 4, 5]
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 5 min 6 s | 22.3k | 17.5k | $0.22 |
| The stash tool | 1 min 40 s | 6.6k | 3.9k | $0.07 |
| Newest Python | 40 s | 2.4k | 2.3k | $0.02 |
| The small option | 32 s | 1.9k | 1.4k | $0.02 |
| The made-up function | 11 s | 359 | 268 | $0.004 |
| Total | 8 min 10 s | 33.5k | 25.3k | $0.34 |
Reasoning effort: default. Cost is what OpenRouter billed. Output tokens include the thinking tokens. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
One Hour of Real Work
This part is written by hand after using Gemini 4 Carbon for an hour of real work. It’s not in yet.
Conclusion
The conclusion is written by hand once the hour of real work is in. It’s not in yet.
See how Gemini 4 Carbon compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review