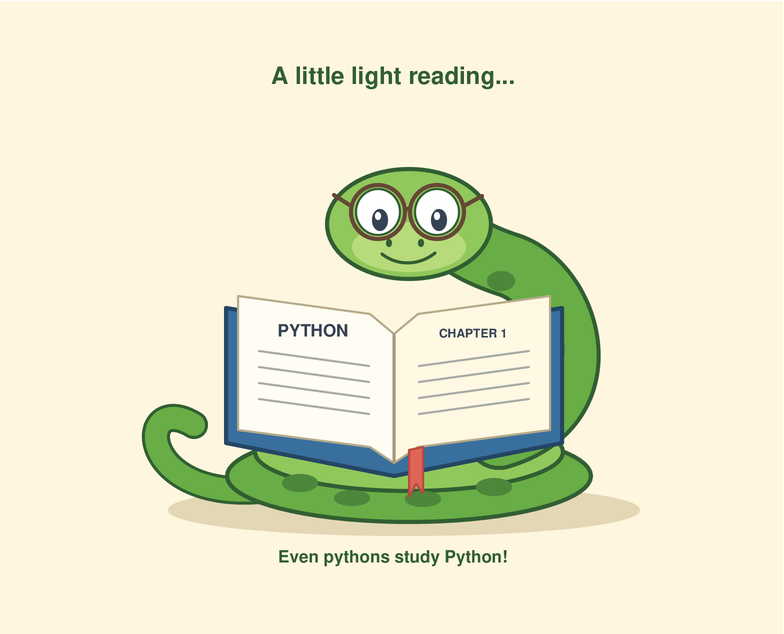
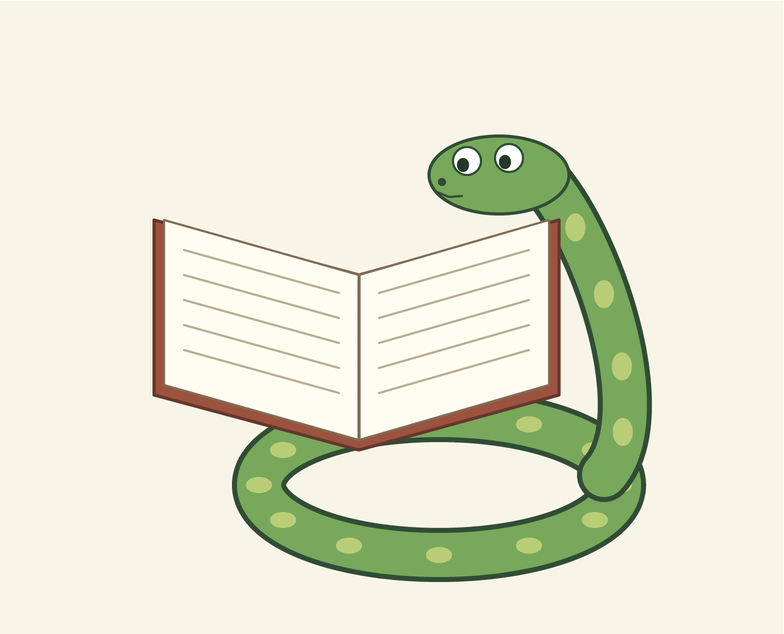
We asked GPT-6.1 Terra to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
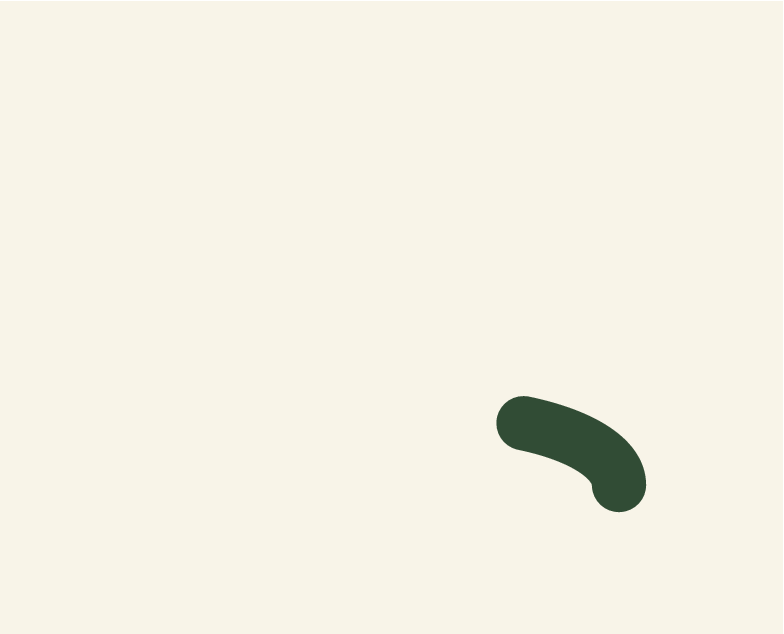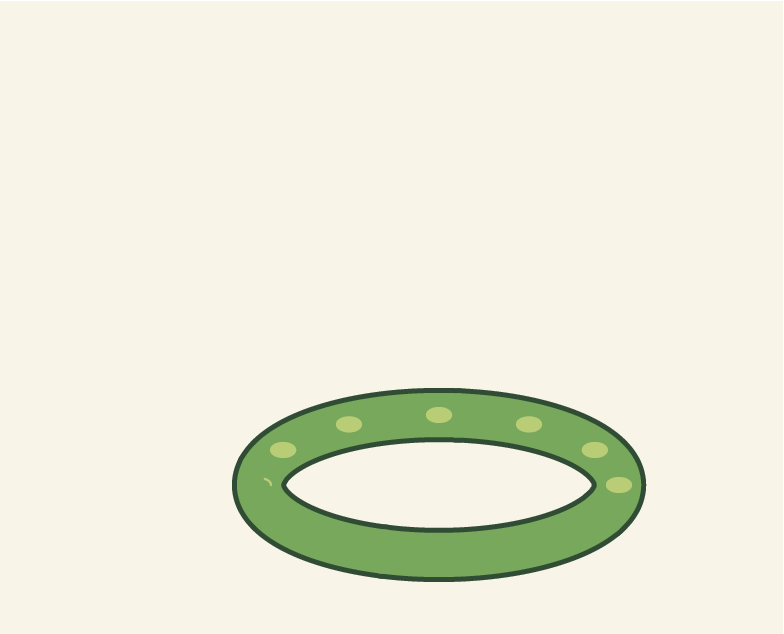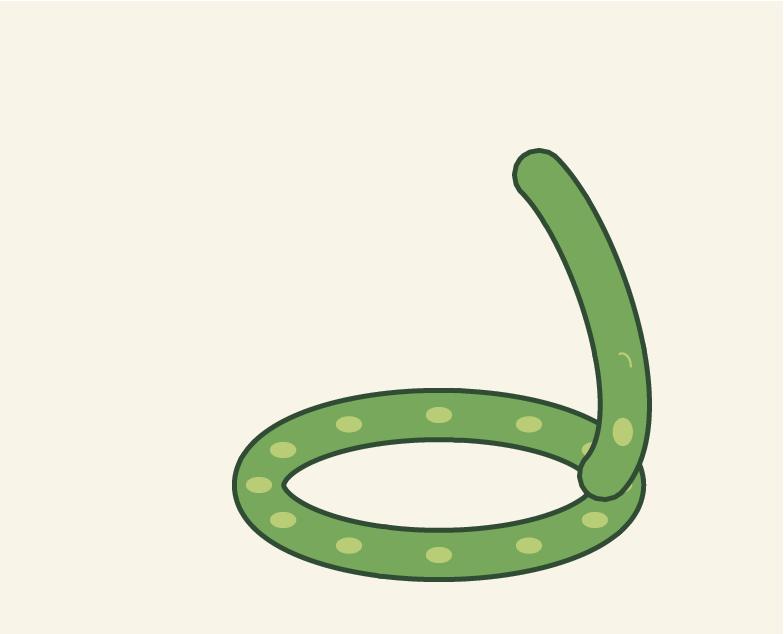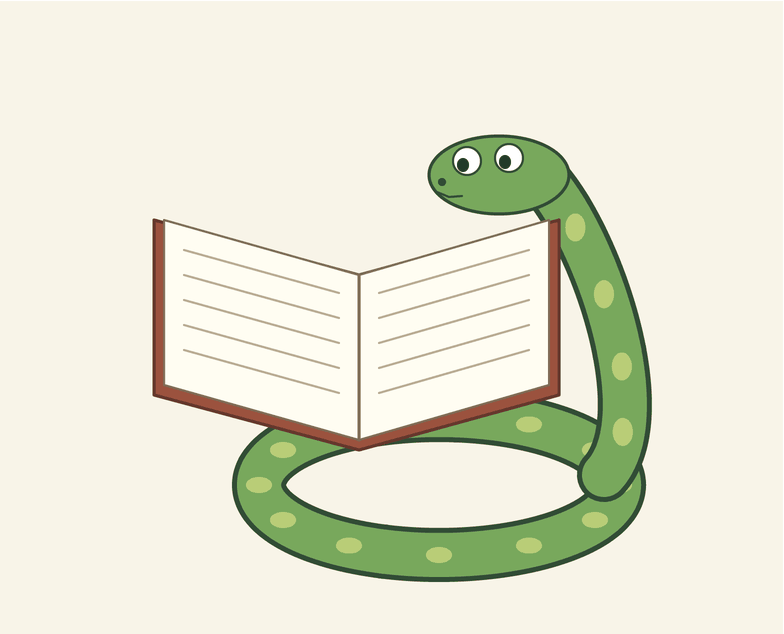
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Unrelated edits | Add an --ext option to a 50-line script. |
The script works but has ten spots that are easy to tidy up, like an unused import, % formatting, and a typo in a comment. None of them is part of the task. We list the ones the model changed anyway. Inspect the diff to see whether those changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 2853 drawing commands, 110 lines of code |
| How modern its Python is | Python 3.10 (2021) | pinned by datetime_utc. Newest feature used: Python 3.11 |
| Modern idioms | 6 of 14 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.14.5 | the reply is quoted below |
| Unrelated edits | 0 of 10 | left every unrelated spot alone |
| Spots a made-up function? | Sidestepped it | showed a real alternative without saying the function is made up |
| Reasoning effort | default | 2.6k thinking tokens over all five tasks |
| Cost | $0.03 | for all 5 tasks, as billed by the API |
| Response time | 1 min 16 s | 6.3k output tokens |
The run: openai/gpt-6.1-terra via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import math
import turtle

screen = turtle.Screen()
screen.setup(800, 650)
screen.bgcolor("#f8f4e8")
screen.title("A Python Reading a Book")

pen = turtle.Turtle()
pen.hideturtle()
pen.speed(0)
screen.tracer(0)


def move(x, y):
    pen.penup()
    pen.goto(x, y)
    pen.pendown()


def polygon(points, fill, outline="#324a35", width=2):
    pen.color(outline, fill)
    pen.pensize(width)
    move(*points[0])
    pen.begin_fill()
    for point in points[1:]:
        pen.goto(*point)
    pen.goto(*points[0])
    pen.end_fill()


def ellipse(cx, cy, rx, ry, fill, outline=None, width=2):
    points = [
        (cx + rx * math.cos(i * math.tau / 100),
         cy + ry * math.sin(i * math.tau / 100))
        for i in range(100)
    ]
    polygon(points, fill, outline or fill, width)


def line(points, color, width=2):
    pen.color(color)
    pen.pensize(width)
    move(*points[0])
    for point in points[1:]:
        pen.goto(*point)


def bezier(p0, p1, p2, p3):
    points = []
    for i in range(101):
        t = i / 100
        u = 1 - t
        points.append((
            u**3 * p0[0] + 3*u**2*t * p1[0] + 3*u*t**2 * p2[0] + t**3 * p3[0],
            u**3 * p0[1] + 3*u**2*t * p1[1] + 3*u*t**2 * p2[1] + t**3 * p3[1],
        ))
    return points


# Coiled body: a dark border with a green stroke on top.
coil = [
    (45 + 180 * math.cos(i * math.tau / 180),
     -165 + 70 * math.sin(i * math.tau / 180))
    for i in range(181)
]
line(coil, "#314c35", 54)
line(coil, "#78a85c", 44)

# Markings along the coil.
for angle in range(0, 360, 30):
    a = math.radians(angle)
    ellipse(45 + 180 * math.cos(a), -165 + 70 * math.sin(a),
            12, 7, "#b9cd77")

# Neck rising behind the book.
neck = bezier((210, -155), (265, -95), (200, 90), (145, 145))
line(neck, "#314c35", 54)
line(neck, "#78a85c", 44)
for i in (18, 38, 58, 78):
    x, y = neck[i]
    ellipse(x, y, 9, 13, "#b9cd77")

# Open book, including its cover and two pages.
polygon([(-240, 100), (-35, 45), (165, 100),
         (165, -75), (-35, -130), (-240, -75)],
        "#9b523e", "#65372c", 3)
polygon([(-230, 100), (-35, 45), (-35, -120), (-230, -65)],
        "#fffdf2", "#806c56", 2)
polygon([(-35, 45), (155, 100), (155, -65), (-35, -120)],
        "#fffdf2", "#806c56", 2)

# Lines of print on the pages.
for y in (70, 45, 20, -5, -30):
    line([(-210, y), (-55, y - 43)], "#b9ab91", 2)
    line([(-15, y - 43), (135, y)], "#b9ab91", 2)

line([(-35, 45), (-35, -120)], "#806c56", 3)

# Head and face, looking down at the book.
ellipse(105, 145, 70, 39, "#78a85c", "#314c35", 3)
ellipse(73, 159, 14, 14, "white", "#314c35", 2)
ellipse(115, 162, 14, 14, "white", "#314c35", 2)
ellipse(69, 155, 5, 6, "#24382a")
ellipse(111, 158, 5, 6, "#24382a")
ellipse(48, 138, 3, 3, "#314c35")
line([(43, 128), (55, 123), (68, 124)], "#314c35", 2)

screen.update()
turtle.done()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 6 of the 14 newer Python features checked by our rubric. For example, it used timezone.utc, utcnow(), utcfromtimestamp() instead of datetime.UTC (Python 3.11) and os.walk() instead of Path.walk() (Python 3.12). These choices give it a Python 3.10 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was hashlib.file_digest(), introduced in Python 3.11.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ❌ stale | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ✅ modern | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ❌ stale | Path.walk() |
os.walk() |
batched |
3.12 | strong | ➖ n/a | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ❌ stale | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ❌ stale | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ❌ stale | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ❌ stale | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
"""Scan, report on, and archive files.

Place stash.toml next to this script, for example:

    ignore = ["*.tmp", "build/*"]
    batch_size = 100
    label = "My files"  # optional

Ignore patterns are matched case-sensitively against both the filename and
its slash-separated path relative to the scanned directory. As with fnmatch,
a wildcard can match a slash.
"""

from __future__ import annotations

import argparse
import fnmatch
import hashlib
import json
import os
import shutil
import stat
import sys
import tempfile
import tomllib
from dataclasses import dataclass
from datetime import datetime, timezone
from pathlib import Path
from typing import Iterator


SCRIPT_DIR = Path(__file__).resolve().parent
CONFIG_PATH = SCRIPT_DIR / "stash.toml"
RESULTS_PATH = SCRIPT_DIR / "stash.json"
ARCHIVE_DIR = SCRIPT_DIR / "archive"


@dataclass(frozen=True)
class Settings:
    ignore: tuple[str, ...]
    batch_size: int
    label: str | None


@dataclass(frozen=True)
class FileRecord:
    path: Path
    size: int
    sha256: str
    modified: datetime

    def to_json(self) -> dict[str, str | int]:
        return {
            "path": str(self.path),
            "size": self.size,
            "sha256": self.sha256,
            "modified": self.modified.isoformat().replace("+00:00", "Z"),
        }

    @classmethod
    def from_json(cls, value: object) -> FileRecord:
        if not isinstance(value, dict):
            raise ValueError("each file record must be an object")

        path = value.get("path")
        size = value.get("size")
        digest = value.get("sha256")
        modified = value.get("modified")

        if not isinstance(path, str) or not Path(path).is_absolute():
            raise ValueError("file record path must be an absolute path")
        if type(size) is not int or size < 0:
            raise ValueError(f"invalid size for {path}")
        if (
            not isinstance(digest, str)
            or len(digest) != 64
            or any(c not in "0123456789abcdef" for c in digest)
        ):
            raise ValueError(f"invalid SHA-256 hash for {path}")
        if not isinstance(modified, str):
            raise ValueError(f"invalid modification time for {path}")

        try:
            timestamp = datetime.fromisoformat(modified)
        except ValueError as exc:
            raise ValueError(f"invalid modification time for {path}") from exc
        if timestamp.tzinfo is None or timestamp.utcoffset() is None:
            raise ValueError(f"modification time for {path} has no timezone")

        return cls(
            path=Path(path),
            size=size,
            sha256=digest,
            modified=timestamp.astimezone(timezone.utc),
        )


def load_settings() -> Settings:
    try:
        with CONFIG_PATH.open("rb") as file:
            data = tomllib.load(file)
    except FileNotFoundError as exc:
        raise ValueError(f"config file not found: {CONFIG_PATH}") from exc

    ignore = data.get("ignore")
    batch_size = data.get("batch_size")
    label = data.get("label")

    if not isinstance(ignore, list) or not all(
        isinstance(pattern, str) for pattern in ignore
    ):
        raise ValueError("config 'ignore' must be a list of strings")
    if type(batch_size) is not int or batch_size <= 0:
        raise ValueError("config 'batch_size' must be a positive integer")
    if label is not None and not isinstance(label, str):
        raise ValueError("config 'label' must be a string")

    return Settings(tuple(ignore), batch_size, label)


def matches_ignore(path: Path, root: Path, patterns: tuple[str, ...]) -> bool:
    relative = path.relative_to(root).as_posix()
    return any(
        fnmatch.fnmatchcase(relative, pattern)
        or fnmatch.fnmatchcase(path.name, pattern)
        for pattern in patterns
    )


def walk_files(root: Path, patterns: tuple[str, ...]) -> Iterator[Path]:
    def raise_walk_error(error: OSError) -> None:
        raise error

    for directory, subdirectories, filenames in os.walk(
        root, onerror=raise_walk_error
    ):
        subdirectories.sort()
        for filename in sorted(filenames):
            path = Path(directory) / filename
            if not matches_ignore(path, root, patterns) and path.is_file():
                yield path


def hash_file(path: Path) -> FileRecord:
    with path.open("rb") as file:
        metadata = os.fstat(file.fileno())
        if not stat.S_ISREG(metadata.st_mode):
            raise ValueError(f"not a regular file: {path}")
        digest = hashlib.file_digest(file, "sha256").hexdigest()
        metadata = os.fstat(file.fileno())

    return FileRecord(
        path=path,
        size=metadata.st_size,
        sha256=digest,
        modified=datetime.fromtimestamp(metadata.st_mtime, timezone.utc),
    )


def write_results(records: list[FileRecord], label: str | None) -> None:
    document = {"label": label, "files": [record.to_json() for record in records]}
    temporary_path: Path | None = None
    try:
        with tempfile.NamedTemporaryFile(
            mode="w",
            encoding="utf-8",
            dir=SCRIPT_DIR,
            prefix=".stash-",
            suffix=".tmp",
            delete=False,
        ) as file:
            temporary_path = Path(file.name)
            json.dump(document, file, indent=2, ensure_ascii=False)
            file.write("\n")
        os.replace(temporary_path, RESULTS_PATH)
    finally:
        if temporary_path is not None:
            temporary_path.unlink(missing_ok=True)


def read_results() -> tuple[str | None, list[FileRecord]]:
    try:
        with RESULTS_PATH.open("r", encoding="utf-8") as file:
            document = json.load(file)
    except FileNotFoundError as exc:
        raise ValueError(f"results file not found: {RESULTS_PATH}; run scan first") from exc

    if not isinstance(document, dict) or not isinstance(document.get("files"), list):
        raise ValueError("results must contain a 'files' list")
    label = document.get("label")
    if label is not None and not isinstance(label, str):
        raise ValueError("results label must be a string or null")

    return label, [FileRecord.from_json(item) for item in document["files"]]


def scan(directory: str, settings: Settings) -> None:
    root = Path(directory).resolve()
    if not root.is_dir():
        raise ValueError(f"directory not found or not a directory: {directory}")

    paths = list(walk_files(root, settings.ignore))
    records: list[FileRecord] = []
    total = len(paths)
    batches = (total + settings.batch_size - 1) // settings.batch_size

    for start in range(0, total, settings.batch_size):
        batch = paths[start : start + settings.batch_size]
        records.extend(hash_file(path) for path in batch)
        batch_number = start // settings.batch_size + 1
        print(f"Batch {batch_number}/{batches}: processed {len(records)}/{total} files")

    write_results(records, settings.label)


def group_by_extension(records: list[FileRecord]) -> dict[str, list[FileRecord]]:
    groups: dict[str, list[FileRecord]] = {}
    for record in records:
        extension = record.path.suffix.lower()
        groups.setdefault(extension, []).append(record)
    return groups


def newest(records: list[FileRecord]) -> FileRecord:
    return max(records, key=lambda record: (record.modified, str(record.path)))


def report() -> None:
    label, records = read_results()
    if label is not None:
        print(f"Label: {label}")

    for extension, group in sorted(group_by_extension(records).items()):
        latest = newest(group)
        display_extension = extension or "(no extension)"
        timestamp = latest.modified.isoformat().replace("+00:00", "Z")
        print(
            f"{display_extension}: {len(group)} files, "
            f"{sum(record.size for record in group)} bytes; "
            f"newest: {latest.path} ({timestamp})"
        )


def archive() -> None:
    _, records = read_results()
    ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)

    for _, group in sorted(group_by_extension(records).items()):
        source = newest(group).path
        destination = ARCHIVE_DIR / source.name
        if destination.exists() and os.path.samefile(source, destination):
            continue
        shutil.copy2(source, destination)


def main() -> int:
    parser = argparse.ArgumentParser(prog="stash", description=__doc__)
    subparsers = parser.add_subparsers(dest="command", required=True)

    scan_parser = subparsers.add_parser("scan", help="scan a directory")
    scan_parser.add_argument("directory", metavar="DIRECTORY")
    subparsers.add_parser("report", help="report on scanned files")
    subparsers.add_parser("archive", help="copy the newest file of each extension")

    args = parser.parse_args()
    try:
        settings = load_settings()
        if args.command == "scan":
            scan(args.directory, settings)
        elif args.command == "report":
            report()
        else:
            archive()
    except (OSError, ValueError) as exc:
        print(f"stash: error: {exc}", file=sys.stderr)
        return 1
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
3.14.5
The Small Option
While adding an --ext option, GPT-6.1 Terra left all 10 unrelated spots alone. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -15,9 +15,11 @@


-def collect_sizes(root, min_size):
+def collect_sizes(root, min_size, ext=None):
     # TODO: skip symlinks?
     sizes = []
     for dirpath, dirnames, filenames in os.walk(root):
         for i in range(len(filenames)):
+            if ext is not None and os.path.splitext(filenames[i])[1] != ext:
+                continue
             path = os.path.join(dirpath, filenames[i])
             try:
@@ -40,4 +42,5 @@
     parser.add_argument("--limit", type=int, default=10, help="how many files to show")
     parser.add_argument("--min-size", type=int, default=0, help="skip files smaller than this many bytes")
+    parser.add_argument("--ext", help="only count files with this extension, e.g. .log")
     args = parser.parse_args()

@@ -47,5 +50,5 @@
         sys.exit(1)

-    top = largest(collect_sizes(args.root, args.min_size), args.limit)
+    top = largest(collect_sizes(args.root, args.min_size, args.ext), args.limit)
     for i in range(len(top)):
         size, path = top[i]
The Made-Up Function
Sidestepped it. There is no itertools.flatten(). It showed a real alternative but never said the function is made up.
from itertools import chain

flattened = list(chain.from_iterable(list_of_lists))
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 22 s | 1.9k | 787 | $0.009 |
| The stash tool | 40 s | 3.5k | 1.4k | $0.02 |
| Newest Python | 5 s | 314 | 303 | $0.002 |
| The small option | 7 s | 536 | 98 | $0.003 |
| The made-up function | 2 s | 47 | 20 | $0.000 |
| Total | 1 min 16 s | 6.3k | 2.6k | $0.03 |
Reasoning effort: default. Cost is what OpenRouter billed. Output tokens include the thinking tokens. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
One Hour of Real Work
This part is written by hand after using GPT-6.1 Terra for an hour of real work. It’s not in yet.
Conclusion
The conclusion is written by hand once the hour of real work is in. It’s not in yet.
See how GPT-6.1 Terra compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review