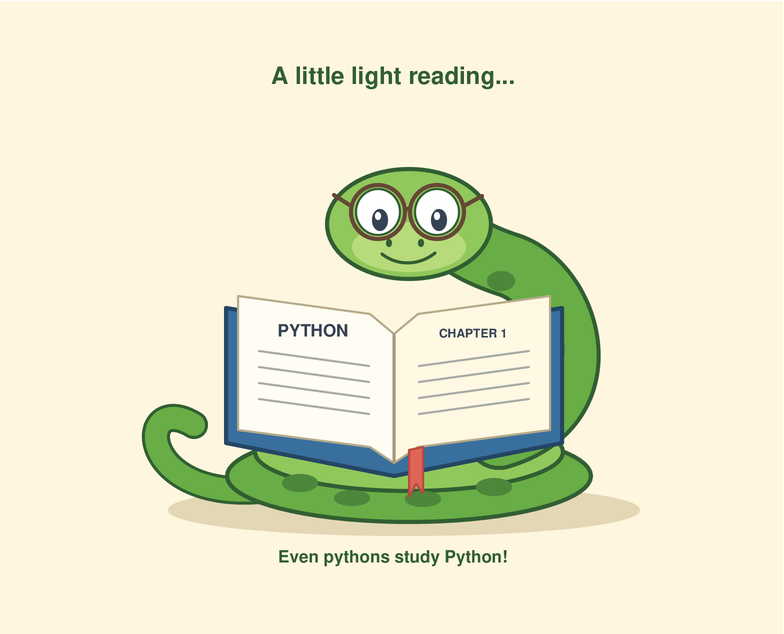
We asked GPT-6 Astra to draw a python reading a book using the turtle module. It’s one of five tasks in Real Python’s informal model comparison, which explores how models handle everyday Python work. Here’s the drawing from this run:
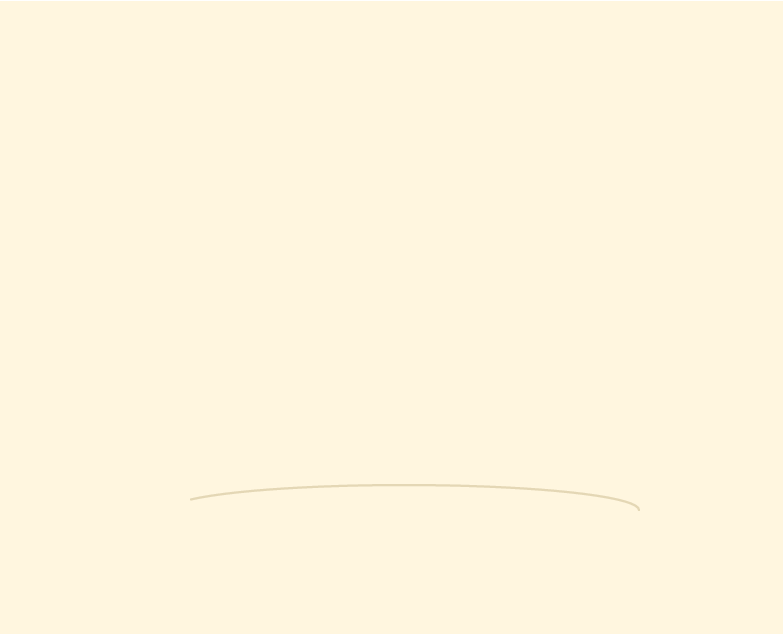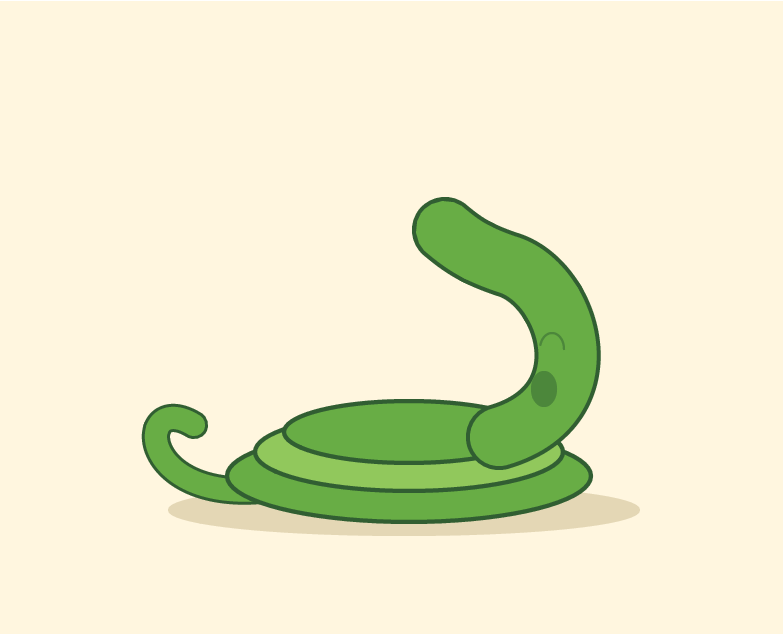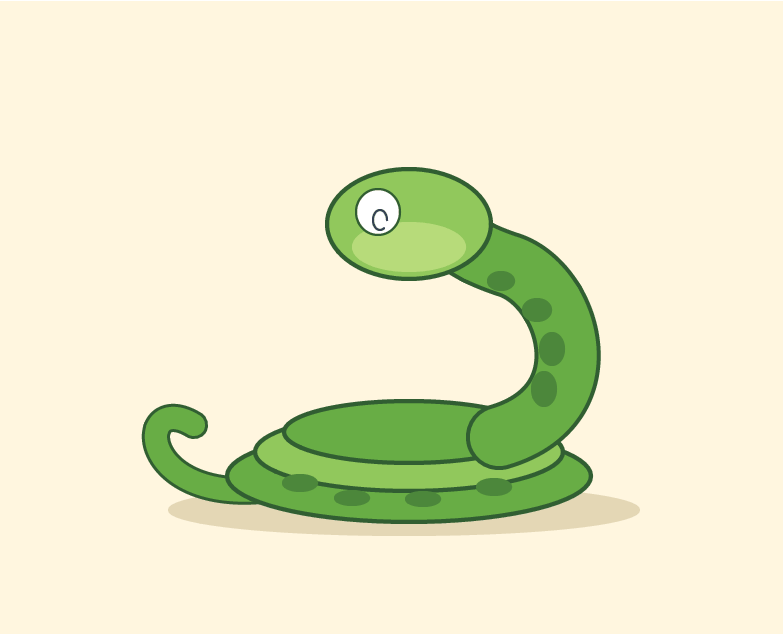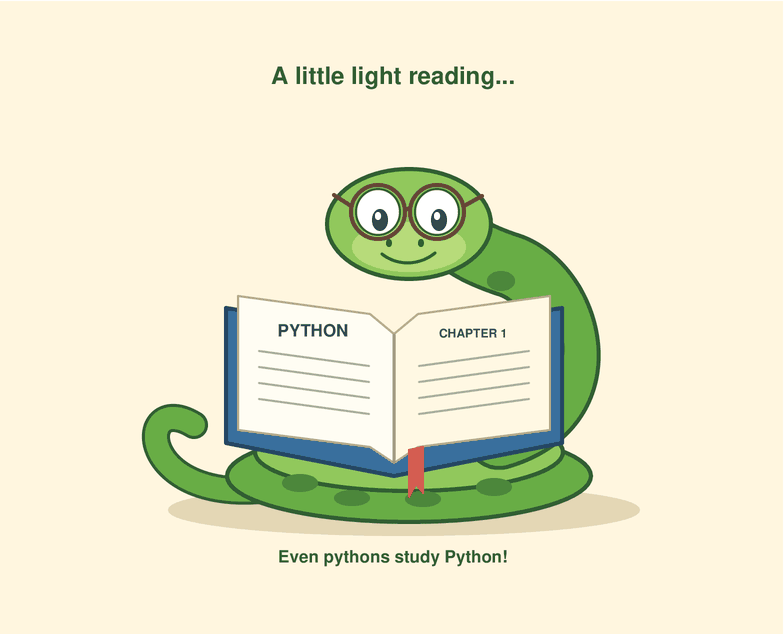
We use the same prompts and no system prompt for each model. The results come from the returned code and replies. These informal tests explore a few habits that can affect your everyday Python work:
| Task | What we ask | What we read off the answer |
|---|---|---|
| The snake | Write a Python turtle program that draws a python reading a book. | We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all. |
| How modern its Python is | Write a small command-line tool. | Which features it uses, such as list[str], tomllib, and Path.walk(). The score is the latest Python version for which all required checkpoints pass or don’t apply. |
| Modern idioms | The same CLI tool as above. | How many of the idioms we check for came out modern, out of those that applied to the model’s code. |
| Latest Python version reported | Which Python release is the newest? | Whether its answer is up to date. This doesn’t establish its training cutoff. |
| Lines touched for a tiny edit | Add a --verbose flag to a 40-line script. |
Added and removed lines, compared with our 7-line reference patch. Inspect the diff to see whether extra changes were useful. |
| Spots a made-up function? | How do I use itertools.flatten()? |
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer. |
| Reasoning effort | The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported. | |
| Cost | What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price. |
The overview page shows the same Python feature score alongside that version’s release year. Code can use newer features and still receive a lower score.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review
The Results at a Glance
| Task | Result | Detail |
|---|---|---|
| The snake | Drew it | 2264 drawing commands, 196 lines of code |
| How modern its Python is | Python 3.10 (2021) | pinned by file_digest. Newest feature used: Python 3.12 |
| Modern idioms | 9 of 15 | of the checkpoints that applied to its code |
| Latest Python version reported | 3.13.7 | the reply is quoted below |
| Lines touched for a tiny edit | 11 (minimal: 7) | 1.6× the minimal patch, 9 lines added and 2 removed |
| Spots a made-up function? | Caught it | said the function doesn’t exist and offered a real alternative |
| Reasoning effort | default | 1.2k thinking tokens over all five tasks |
| Cost | $0.31 | for all 5 tasks, as billed by the API |
| Response time | 1 min 25 s | 6.0k output tokens |
The run: openai/gpt-6-astra via OpenRouter, at its default reasoning settings, with no system prompt and the returned code left unchanged.
The Five Tasks
The Snake
The script ran without errors. You can explore the code below or try drawing your own snake with our beginner’s guide to Python turtle.
turtle.py
import math
import turtle

screen = turtle.Screen()
screen.setup(800, 650)
screen.title("A Python Reading Python")
screen.bgcolor("#fff6df")
screen.tracer(0)

pen = turtle.Turtle()
pen.hideturtle()
pen.speed(0)

GREEN = "#68ad45"
DARK_GREEN = "#315e32"
LIGHT_GREEN = "#91c85c"
INK = "#354253"


def polygon(points, fill, outline=INK, width=2):
    pen.penup()
    pen.goto(points[0])
    pen.color(outline, fill)
    pen.pensize(width)
    pen.pendown()
    pen.begin_fill()
    for point in points[1:]:
        pen.goto(point)
    pen.goto(points[0])
    pen.end_fill()
    pen.penup()


def ellipse(x, y, rx, ry, fill, outline=INK, width=2):
    points = [
        (
            x + rx * math.cos(math.radians(angle)),
            y + ry * math.sin(math.radians(angle)),
        )
        for angle in range(0, 360, 5)
    ]
    polygon(points, fill, outline, width)


def line(points, color=INK, width=2):
    pen.penup()
    pen.goto(points[0])
    pen.pencolor(color)
    pen.pensize(width)
    pen.pendown()
    for point in points[1:]:
        pen.goto(point)
    pen.penup()


def bezier(p0, p1, p2, p3, steps=60):
    points = []
    for i in range(steps + 1):
        t = i / steps
        u = 1 - t
        points.append((
            u**3 * p0[0] + 3*u*u*t * p1[0]
            + 3*u*t*t * p2[0] + t**3 * p3[0],
            u**3 * p0[1] + 3*u*u*t * p1[1]
            + 3*u*t*t * p2[1] + t**3 * p3[1],
        ))
    return points


def text(x, y, words, size=18, color=INK):
    pen.penup()
    pen.goto(x, y)
    pen.pencolor(color)
    pen.write(words, align="center", font=("Arial", size, "bold"))


# Ground shadow
ellipse(10, -190, 235, 25, "#e4d7b5", "#e4d7b5")

# Tail curling out from behind the coils
tail = bezier(
    (-80, -160), (-260, -210), (-265, -65), (-200, -105)
)
line(tail, DARK_GREEN, 28)
line(tail, GREEN, 22)

# Broad, overlapping coils
ellipse(15, -156, 182, 46, GREEN, DARK_GREEN, 4)
ellipse(15, -132, 154, 39, LIGHT_GREEN, DARK_GREEN, 4)
ellipse(15, -112, 125, 31, GREEN, DARK_GREEN, 4)

# Raised neck, behind the book
neck = (
    bezier((105, -117), (215, -85), (174, 39), (112, 56))
    + bezier((112, 56), (83, 66), (70, 74), (51, 90))[1:]
)
line(neck, DARK_GREEN, 66)
line(neck, GREEN, 58)

# A few python markings
for x, y, rx, ry in [
    (150, -69, 12, 17),
    (158, -29, 12, 16),
    (143, 10, 14, 11),
    (107, 39, 13, 9),
    (-94, -163, 17, 8),
    (-42, -178, 17, 7),
    (29, -179, 17, 7),
    (100, -167, 17, 8),
]:
    ellipse(x, y, rx, ry, "#4c873b", "#4c873b")

# Head
ellipse(15, 96, 82, 55, LIGHT_GREEN, DARK_GREEN, 4)
ellipse(15, 73, 56, 24, "#b7db7a", "#b7db7a")

# Eyes
for x in (-16, 43):
    ellipse(x, 108, 22, 23, "white", DARK_GREEN, 2)
    # Pupils look down toward the book.
    ellipse(x + 2, 100, 7, 10, INK, INK)
    ellipse(x, 104, 2, 3, "white", "white")

# Round reading glasses
for x in (-16, 43):
    rim = [
        (
            x + 27 * math.cos(math.radians(a)),
            108 + 27 * math.sin(math.radians(a)),
        )
        for a in range(0, 361, 5)
    ]
    line(rim, "#664735", 4)

line([(11, 110), (16, 112)], "#664735", 4)
line([(-43, 114), (-60, 125)], "#664735", 4)
line([(70, 114), (88, 124)], "#664735", 4)

# Nostrils and a contented smile
ellipse(-5, 77, 2, 3, DARK_GREEN, DARK_GREEN)
ellipse(27, 77, 2, 3, DARK_GREEN, DARK_GREEN)
line(
    bezier((-12, 66), (3, 54), (25, 54), (41, 67)),
    DARK_GREEN,
    3,
)

# Open book: blue covers
polygon(
    [(-168, 12), (-8, -14), (0, -27),
     (8, -14), (168, 12), (168, -123),
     (0, -156), (-168, -123)],
    "#396f9d",
    "#244664",
    4,
)

# Left and right pages
polygon(
    [(-156, 24), (-24, 6), (0, -14),
     (0, -143), (-24, -127), (-156, -110)],
    "#fffdf3",
    "#b6aa8a",
)
polygon(
    [(0, -14), (24, 6), (156, 24),
     (156, -110), (24, -127), (0, -143)],
    "#fff8e3",
    "#b6aa8a",
)

# Spine
line([(0, -15), (0, -142)], "#a99a7c", 3)

# Page headings
text(-80, -20, "PYTHON", 17)
text(80, -20, "CHAPTER 1", 12)

# Printed lines follow the angle of each page.
for y in (-39, -55, -71, -87):
    line([(-135, y + 8), (-25, y - 7)], "#a7aaa5", 2)
    line([(25, y - 7), (135, y + 8)], "#a7aaa5", 2)

# Ribbon bookmark
polygon(
    [(15, -130), (29, -127), (29, -173),
     (22, -164), (15, -177)],
    "#df6558",
    "#b94940",
)

text(0, 231, "A little light reading...", 24, DARK_GREEN)
text(0, -246, "Even pythons study Python!", 17, DARK_GREEN)

screen.update()
screen.exitonclick()
The Stash Tool
We asked for a command-line tool called stash to see which Python features the model uses.
Its code used 9 of the 15 newer Python features checked by our rubric. For example, it used a manual hashing loop instead of hashlib.file_digest() (Python 3.11) and os.walk() instead of Path.walk() (Python 3.12). These choices give it a Python 3.10 score under our rubric. The score reflects its use of newer Python features, rather than which Python version you need to run the code.
The newest feature detected was itertools.batched(), introduced in Python 3.12.
| Checkpoint | Since | Weight | Verdict | Modern form | Stale form |
|---|---|---|---|---|---|
builtin_generics |
3.9 | strong | ✅ modern | list[str], dict[str, int] |
typing.List, typing.Dict |
union_pipe |
3.10 | strong | ✅ modern | X \| None |
Optional[X], Union[X, Y] |
tomllib |
3.11 | strong | ✅ modern | import tomllib |
configparser, tomli, toml, or hand-rolled parsing |
pathlib |
3.4 | strong | ✅ modern | pathlib.Path |
os.path.join and friends |
fstrings |
3.6 | strong | ✅ modern | f"..." |
str.format() or % formatting |
datetime_utc |
3.11 | strong | ✅ modern | datetime.UTC |
timezone.utc, utcnow(), utcfromtimestamp() |
file_digest |
3.11 | strong | ❌ stale | hashlib.file_digest() |
manual read/update loop |
path_walk |
3.12 | strong | ❌ stale | Path.walk() |
os.walk() |
batched |
3.12 | strong | ✅ modern | itertools.batched() |
range(0, len(x), n) slicing or islice() |
path_copy |
3.14 | strong | ❌ stale | Path.copy() / Path.copy_into() |
shutil.copy2() |
dataclass_slots |
3.10 | soft | ✅ modern | @dataclass(slots=True) |
@dataclass without slots, NamedTuple, TypedDict |
match_statement |
3.10 | soft | ✅ modern | match args.command: |
if/elif chain on the command string |
self_type |
3.11 | soft | ❌ stale | -> Self |
-> 'Config' on a classmethod |
pep695_generics |
3.12 | soft | ➖ n/a | def f[T](...) |
TypeVar() |
except_no_parens |
3.14 | soft | ❌ stale | except A, B: |
except (A, B): |
no_future_annotations |
3.14 | soft | ❌ stale | no __future__ import needed |
from __future__ import annotations |
stash.py
#!/usr/bin/env python3
"""Inventory files, report by extension, and archive the newest files.

Requires Python 3.12 or newer.

Example stash.toml (stored next to this script):

    ignore = ["*.pyc", "__pycache__/*", ".git/*", "**/.git/*"]
    batch_size = 100
    label = "My files"

Ignore patterns match case-sensitive, forward-slash-separated paths relative
to the scanned directory, or individual file names. Extensions are grouped
case-insensitively; only the final suffix counts.
"""

from __future__ import annotations

import argparse
import fnmatch
import hashlib
import json
import os
import shutil
import sys
import tempfile
import tomllib
from collections import defaultdict
from dataclasses import dataclass
from datetime import UTC, datetime
from itertools import batched
from pathlib import Path
from typing import Any, NoReturn

SCRIPT_DIR = Path(__file__).resolve().parent
CONFIG_PATH = SCRIPT_DIR / "stash.toml"
RESULTS_PATH = SCRIPT_DIR / "stash.json"
ARCHIVE_DIR = SCRIPT_DIR / "archive"
HASH_CHUNK_SIZE = 1024 * 1024


@dataclass(frozen=True, slots=True)
class Settings:
    ignore: tuple[str, ...]
    batch_size: int
    label: str | None


@dataclass(frozen=True, slots=True)
class FileRecord:
    path: Path
    size: int
    sha256: str
    modified: datetime

    @property
    def extension(self) -> str:
        return self.path.suffix.lower()

    def to_json(self) -> dict[str, Any]:
        return {
            "path": str(self.path),
            "size": self.size,
            "sha256": self.sha256,
            "modified": self.modified.astimezone(UTC).isoformat().replace(
                "+00:00", "Z"
            ),
        }

    @classmethod
    def from_json(cls, value: object) -> FileRecord:
        if not isinstance(value, dict):
            raise ValueError("each file record must be an object")

        path = value.get("path")
        size = value.get("size")
        digest = value.get("sha256")
        modified = value.get("modified")

        if not isinstance(path, str) or not path or not Path(path).is_absolute():
            raise ValueError("file record path must be an absolute path")
        if type(size) is not int or size < 0:
            raise ValueError("file record size must be a non-negative integer")
        if (
            not isinstance(digest, str)
            or len(digest) != 64
            or any(character not in "0123456789abcdefABCDEF" for character in digest)
        ):
            raise ValueError("file record sha256 must be a SHA-256 hex digest")
        if not isinstance(modified, str):
            raise ValueError("file record modified must be a UTC timestamp")

        timestamp = datetime.fromisoformat(modified)
        if timestamp.tzinfo is None:
            raise ValueError("file record modified must include a timezone")

        return cls(
            path=Path(path),
            size=size,
            sha256=digest.lower(),
            modified=timestamp.astimezone(UTC),
        )


def load_settings() -> Settings:
    if not CONFIG_PATH.is_file():
        raise ValueError(f"config file not found: {CONFIG_PATH}")

    try:
        with CONFIG_PATH.open("rb") as stream:
            data = tomllib.load(stream)
    except tomllib.TOMLDecodeError as exc:
        raise ValueError(f"invalid config {CONFIG_PATH}: {exc}") from exc

    ignore = data.get("ignore", [])
    batch_size = data.get("batch_size", 100)
    label = data.get("label")

    if not isinstance(ignore, list) or not all(
        isinstance(pattern, str) for pattern in ignore
    ):
        raise ValueError(f"{CONFIG_PATH}: 'ignore' must be a list of strings")
    if type(batch_size) is not int or batch_size <= 0:
        raise ValueError(f"{CONFIG_PATH}: 'batch_size' must be a positive integer")
    if label is not None and not isinstance(label, str):
        raise ValueError(f"{CONFIG_PATH}: 'label' must be a string")

    return Settings(tuple(ignore), batch_size, label)


def is_ignored(relative_path: Path, patterns: tuple[str, ...]) -> bool:
    relative_name = relative_path.as_posix()
    for pattern in patterns:
        # Leading **/ can also match zero directory components.
        candidate = pattern
        while True:
            if fnmatch.fnmatchcase(relative_name, candidate) or fnmatch.fnmatchcase(
                relative_path.name, candidate
            ):
                return True
            if not candidate.startswith("**/"):
                break
            candidate = candidate[3:]
    return False


def raise_walk_error(error: OSError) -> NoReturn:
    raise error


def collect_paths(root: Path, settings: Settings) -> list[Path]:
    paths: list[Path] = []
    for directory, directories, filenames in os.walk(
        root, onerror=raise_walk_error, followlinks=False
    ):
        directories.sort()
        for filename in sorted(filenames):
            path = Path(directory) / filename
            if is_ignored(path.relative_to(root), settings.ignore):
                continue
            if path.is_file():
                paths.append(path)
    return paths


def hash_file(path: Path) -> FileRecord:
    digest = hashlib.sha256()
    bytes_read = 0

    with path.open("rb") as stream:
        before = os.fstat(stream.fileno())
        while chunk := stream.read(HASH_CHUNK_SIZE):
            digest.update(chunk)
            bytes_read += len(chunk)
        after = os.fstat(stream.fileno())

    if (
        before.st_size != after.st_size
        or before.st_mtime_ns != after.st_mtime_ns
        or before.st_ctime_ns != after.st_ctime_ns
        or bytes_read != after.st_size
    ):
        raise ValueError(f"file changed while being hashed; scan again: {path}")

    return FileRecord(
        path=path,
        size=bytes_read,
        sha256=digest.hexdigest(),
        modified=datetime.fromtimestamp(after.st_mtime, UTC),
    )


def write_results(
    root: Path, settings: Settings, records: list[FileRecord]
) -> None:
    payload = {
        "version": 1,
        "root": str(root),
        "label": settings.label,
        "files": [record.to_json() for record in records],
    }

    # Replace the inventory only after the entire new JSON file is written.
    temporary_path: Path | None = None
    try:
        with tempfile.NamedTemporaryFile(
            mode="w",
            encoding="utf-8",
            dir=SCRIPT_DIR,
            prefix=".stash-",
            suffix=".tmp",
            delete=False,
        ) as stream:
            temporary_path = Path(stream.name)
            json.dump(payload, stream, indent=2, ensure_ascii=True)
            stream.write("\n")
            stream.flush()
            os.fsync(stream.fileno())
        temporary_path.replace(RESULTS_PATH)
    finally:
        if temporary_path is not None:
            temporary_path.unlink(missing_ok=True)


def read_results() -> list[FileRecord]:
    if not RESULTS_PATH.is_file():
        raise ValueError(
            f"inventory not found: {RESULTS_PATH}; run 'stash scan DIRECTORY' first"
        )

    try:
        with RESULTS_PATH.open("r", encoding="utf-8") as stream:
            payload = json.load(stream)

        if not isinstance(payload, dict) or payload.get("version") != 1:
            raise ValueError("unsupported inventory format")
        files = payload.get("files")
        if not isinstance(files, list):
            raise ValueError("'files' must be a list")

        return [FileRecord.from_json(value) for value in files]
    except ValueError as exc:
        raise ValueError(f"invalid inventory {RESULTS_PATH}: {exc}") from exc


def scan(directory: Path, settings: Settings) -> None:
    root = directory.expanduser().resolve()
    if not root.exists():
        raise ValueError(f"directory not found: {root}")
    if not root.is_dir():
        raise ValueError(f"not a directory: {root}")

    paths = collect_paths(root, settings)
    records: list[FileRecord] = []
    total_batches = (len(paths) + settings.batch_size - 1) // settings.batch_size
    prefix = f"[{settings.label}] " if settings.label else ""

    for number, batch in enumerate(batched(paths, settings.batch_size), start=1):
        records.extend(hash_file(path) for path in batch)
        print(
            f"{prefix}Batch {number}/{total_batches}: "
            f"hashed {len(batch)} files ({len(records)}/{len(paths)} total)",
            flush=True,
        )

    write_results(root, settings, records)
    print(f"{prefix}Saved {len(records)} files to {RESULTS_PATH}")


def group_records(records: list[FileRecord]) -> dict[str, list[FileRecord]]:
    groups: dict[str, list[FileRecord]] = defaultdict(list)
    for record in records:
        groups[record.extension].append(record)
    return dict(groups)


def newest_file(records: list[FileRecord]) -> FileRecord:
    # Resolve equal timestamps deterministically by absolute path.
    return max(records, key=lambda record: (record.modified, str(record.path)))


def report() -> None:
    groups = group_records(read_results())
    if not groups:
        print("No files recorded.")
        return

    extension_width = max(
        len("Extension"), *(len(extension or "(none)") for extension in groups)
    )
    print(f"{'Extension':<{extension_width}}  {'Files':>8}  {'Bytes':>14}  Newest file")
    for extension, records in sorted(groups.items()):
        newest = newest_file(records)
        total_size = sum(record.size for record in records)
        print(
            f"{extension or '(none)':<{extension_width}}  "
            f"{len(records):>8}  {total_size:>14}  {newest.path}"
        )


def archive() -> None:
    groups = group_records(read_results())
    selected = [newest_file(records) for _, records in sorted(groups.items())]

    # Check all sources before starting to copy.
    for record in selected:
        if not record.path.is_file():
            raise ValueError(f"recorded file is missing or not a file: {record.path}")

    ARCHIVE_DIR.mkdir(parents=True, exist_ok=True)

    for record in selected:
        destination = ARCHIVE_DIR / record.path.name
        if destination.exists() and os.path.samefile(record.path, destination):
            print(f"Already archived: {destination}")
            continue
        shutil.copy2(record.path, destination)
        print(f"Copied {record.path} -> {destination}")

    if not selected:
        print("No files to archive.")


def build_parser() -> argparse.ArgumentParser:
    parser = argparse.ArgumentParser(
        prog="stash",
        description="Scan files, report by extension, and archive newest files.",
    )
    subcommands = parser.add_subparsers(dest="command", required=True)

    scan_parser = subcommands.add_parser("scan", help="recursively inventory a directory")
    scan_parser.add_argument("directory", metavar="DIRECTORY", type=Path)
    subcommands.add_parser("report", help="summarize the saved inventory by extension")
    subcommands.add_parser("archive", help="copy the newest file of each extension")

    return parser


def main(argv: list[str] | None = None) -> int:
    arguments = build_parser().parse_args(argv)

    try:
        settings = load_settings()
        match arguments.command:
            case "scan":
                scan(arguments.directory, settings)
            case "report":
                report()
            case "archive":
                archive()
        return 0
    except (OSError, ValueError, OverflowError, shutil.Error) as exc:
        print(f"stash: error: {exc}", file=sys.stderr)
        return 1
    except KeyboardInterrupt:
        print("\nstash: interrupted", file=sys.stderr)
        return 130


if __name__ == "__main__":
    raise SystemExit(main())
Python Release Knowledge
Asked for the newest stable Python release, with just the version number, it said:
3.13.7
The Tiny Edit
To add a --verbose flag, GPT-6 Astra changed 11 lines, compared with 7 in our reference patch. You can inspect the diff below to see what it changed.
--- original.py
+++ updated.py
@@ -19,7 +19,9 @@


-def summarize(directory: Path) -> Counter[str]:
+def summarize(directory: Path, verbose: bool = False) -> Counter[str]:
     total: Counter[str] = Counter()
     for path in sorted(directory.glob("*.log")):
+        if verbose:
+            print(f"Processing {path.name}")
         total.update(count_levels(path))
     return total
@@ -29,7 +31,12 @@
     parser = argparse.ArgumentParser(description=__doc__)
     parser.add_argument("directory", type=Path)
+    parser.add_argument(
+        "--verbose",
+        action="store_true",
+        help="Print each file name as it is processed.",
+    )
     args = parser.parse_args()

-    counts = summarize(args.directory)
+    counts = summarize(args.directory, verbose=args.verbose)
     for level in ("DEBUG", "INFO", "WARNING", "ERROR", "CRITICAL"):
         print(f"{level:<9} {counts[level]:>6}")
The Made-Up Function
Caught it. There is no itertools.flatten(). It said the function doesn’t exist and offered a real alternative.
from itertools import chain  # itertools has no flatten()

lists = [[1, 2], [3, 4], [5]]
flat = list(chain.from_iterable(lists))  # [1, 2, 3, 4, 5]
Cost and Effort by Task
| Task | Time | Output tokens | Thinking tokens | Cost |
|---|---|---|---|---|
| The snake | 35 s | 2.1k | 335 | $0.11 |
| The stash tool | 39 s | 3.3k | 634 | $0.17 |
| Newest Python | 4 s | 186 | 175 | $0.010 |
| The tiny edit | 4 s | 315 | 0 | $0.02 |
| The made-up function | 3 s | 107 | 42 | $0.006 |
| Total | 1 min 25 s | 6.0k | 1.2k | $0.31 |
Reasoning effort: default. Cost is what OpenRouter billed. Output tokens include the thinking tokens. Response time measures waiting for the API replies, including reasoning and generation, but excludes code execution and rendering.
One Hour of Real Work
The five tasks above tell you what a model does when you hand it a prompt and walk away. They don’t tell you what it’s like to work next to it. So three of us put GPT-6 Astra to work on our actual jobs and talked about what we noticed:
Dan Bader
Dan Bader is the owner and editor-in-chief of Real Python and the main developer of the realpython.com learning platform.
Astra is my favorite OpenAI model so far. I’ve been living in Claude Code with Claude Fable 5.1 for a while, and switching over to Codex with Astra didn’t feel like a step down.
The test I cared about was a rewrite. I have a small text editor written in Python, and I asked Astra to port it to Rust. What came back did the same thing as before, about three times faster. Along the way, it flagged three bugs in my Python original, fixed them in the Rust version, and offered to patch the Python too.
Fable has done similar things for me on other codebases, so my guess is it would have landed in the same place. I haven’t tried the same rewrite with GPT-5.6 Sol or Claude Opus, so that part is a gut feeling, not a measurement.
For reasoning effort, low or medium is my sweet spot. Both Anthropic and OpenAI shipped new prompting guidance alongside these models, and it says the same thing: keep prompts short and drop the “you must” boilerplate.
Astra isn’t flawless, though. More than once I asked an obvious follow-up and got “What are you referring to?” back. That hasn’t happened to me with Fable, but that may only mean I’m used to steering Claude models.
Martin Breuss
Martin Breuss is Real Python’s Head of Content Strategy, with a background in education as a coding mentor, curriculum developer, and bootcamp instructor.
I didn’t get as much time with Astra as I’d have liked, and I used it mostly for text and language work rather than code. I’ve been working mainly with Anthropic models, and Astra feels like an improvement to me. One experiment was to get a head start on refreshing an outdated piece of content: make it technically accurate and current, but keep it reading like the original. That worked really well.
I didn’t change my prompting with Astra so far. I don’t engineer my prompts at all these days, I just say what I want as directly as I can, that usually works well with frontier models. I’ve never gotten into an argument with a model either. When a conversation stops going where I want it to go, I cut the context or start fresh.
What’s been refreshing is that Astra doesn’t have the stock phrases I’ve learned to skip over in Claude Opus, and to some degree in Fable. I can’t compare it with Fable head to head, because I probably haven’t given Fable the same tasks. I still use Opus for most things and save Fable for the ones that matter.
Philipp Acsany
Philipp Acsany is a core member of the Real Python team who creates tutorials, records video courses, and hosts live workshops.
Release demos are always a big 3D render or a one-shot game. That’s not where you notice a new model. You notice it in your day-to-day work, in whether the model supports what you’re doing or you end up working against it. I felt some of that friction with Claude Opus 5. With Astra, it feels more like we’re thinking along the same lines.
OpenAI’s announcement called the model more aligned, and after a few days, that’s the word I’d pick too.
Here’s a small example. I made a typo in a prompt, and Astra carried the typo through. Every model I’d used before would have quietly corrected it. When I asked, Astra confirmed the typo, gave the correct spelling, and left it at that. I’m not sure whether I liked that, and I still need to check whether it only happens at low effort. If I want it to fix something, I have to say so.
I get good output at low effort, from Astra and from Fable. I do wonder how much of this is the honeymoon phase. Maybe in three weeks we’ll be talking about Astra’s stock phrases too.
Conclusion
All three of us find day-to-day work with Astra better than it was before. Dan puts it roughly on par with Claude Fable 5.1, as far as he can tell, and calls the rest personal preference. Martin hasn’t run both on the same tasks and won’t make that call. Some of this may be the honeymoon phase, and Philipp says as much.
We do agree on one thing. When a big release lands, try it right away. What these models can do changes within months, sometimes weeks, and the only way to find out where a new one fits into your workflow is to hand it real work.
See how GPT-6 Astra compares with every other model we’ve run on the overview page.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development, Context Engineering, AI Code Review