If you’ve used Requests, then you’ve probably felt its limits the moment you needed to fire off a batch of API calls at once or keep one stalled server from freezing your script. HTTPX2, the Pydantic-maintained fork of Python HTTPX, keeps the Requests-style API you know while adding asynchronous requests, sensible default timeouts, and HTTP/2. In this tutorial, you’ll learn how to move from Requests to HTTPX2.
By the end of this tutorial, you’ll understand that:
- A reusable
Clientpools connections instead of opening a new one per request. AsyncClienthandles concurrent requests withasyncio.- Granular timeouts and a clear exception hierarchy make failures predictable.
- Streaming processes large responses without ever loading them fully into memory.
- HTTP/2 costs one extra dependency and one argument.
To get the most out of this tutorial, you should be comfortable making basic requests with Requests and working with dictionaries, with statements, and exceptions. You don’t need prior experience with asyncio, since you’ll learn what you need along the way.
To follow along, you’ll want a working Python 3.10 or newer environment. Start by creating and activating a virtual environment, so that the packages you install stay isolated from the rest of your system:
The (.venv) prefix in the prompt confirms that the environment is active, and installing both libraries into it lets you compare them side by side.
If you want to explore the code examples from this tutorial, then you can download them here:
Get Your Code: Click here to download the free sample code that shows you how to make HTTP requests in Python with HTTPX2.
Take the Quiz: Test your knowledge with our interactive “Python HTTPX: Making HTTP Requests With HTTPX2” quiz. You’ll receive a score upon completion to help you track your learning progress:
Interactive Quiz
Python HTTPX: Making HTTP Requests With HTTPX2Test your knowledge of Python HTTPX2 by reusing clients, sending async requests, setting timeouts, streaming responses, and enabling HTTP/2.
Before you write your first request, it’s worth taking a quick look at where HTTPX2 comes from, since that explains a few names you’ll run into later.
Meet HTTPX2, the Fork of Python HTTPX
The Python ecosystem has evolved considerably since Requests was designed in 2011. The original HTTPX project was kicked off in 2019 to bridge the gaps that Requests left behind. In 2026, Pydantic forked it as HTTPX2, picking up stewardship so that the library has a reliably maintained path forward.
HTTPX and HTTPX2 are separate packages rather than one renamed project: they install under different names, import differently, and can sit side by side in the same environment without conflicting.
HTTPX2 keeps the same public API, so most code moves across unchanged. A few things did shift in the fork: the command-line tool and the underlying httpcore package were renamed, Python 3.9 support was dropped, and TLS verification now uses your operating system’s trust store instead of a bundled certificate list.
That last change helps if you work behind a corporate proxy that inspects TLS traffic: as long as your company’s root certificate is installed in your operating system, HTTPX2 trusts it without any extra configuration. This tutorial refers to HTTPX2 throughout, but almost everything you’ll learn applies equally well to code you’ve already written with HTTPX.
The appeal of HTTPX2 is a developer-friendly API backed by powerful infrastructure. By standardizing on HTTPX2, you get a single tool that can handle both lightweight synchronous scripts and demanding, high-concurrency async workloads.
Replace One-Off Requests With a Reusable Client
In this section, you’ll start with a familiar one-off request, then move to a reusable client that shares connections and settings across calls, and finish by sending data to a server. Along the way, you’ll see how each step maps onto code you may already have written with Requests.
Make Your First Request
The quickest way to get started with HTTPX2 is to make a basic GET request:
first_request.py
import httpx2

response = httpx2.get("https://api.github.com/events")
print(response.status_code)
print(response.json())
The output from this code is shown below:
$ python first_request.py
200
[{'id': '19412078592', 'type': 'PushEvent', 'actor': {...}, ...}, ...]
This sends a GET request and prints the status code and the decoded JSON body. The response is a long list of event objects, so the output above is truncated with ellipses to keep it readable. Running the code yourself will print the full list.
Note: If you’ve used Requests before, then this will look familiar. The same snippet works almost identically there once you swap the import:
requests_version.py
import requests

response = requests.get("https://api.github.com/events")
print(response.status_code)
print(response.json())
Running it gives you the same kind of output:
$ python requests_version.py
200
[{'id': '19412225171', 'type': 'PushEvent', 'actor': {...}, ...}, ...]
The output is truncated in the same way. If you’re migrating an existing script, then swapping requests for httpx2 is often all it takes. The main difference to watch for is redirects: Requests follows them automatically, while HTTPX2 returns the 3xx response unless you pass follow_redirects=True. Still, resist the urge to run a blanket find-and-replace across a production codebase without testing the result first.
Note: The GitHub API allows sixty requests per hour from an unauthenticated IP address. If the examples in this tutorial suddenly start returning 403 or 429 responses, then you’ve most likely hit that limit rather than broken anything. The count resets each hour, and passing a personal access token in the Authorization header raises the limit substantially.
Reuse Connections With a Client
Top-level functions like httpx2.get() are good enough for exploration, but they hide a cost. Each call opens a fresh TCP connection, completes the request, and then tears the connection down again. When you make many calls to the same host, that repeated setup and teardown cycle becomes a performance bottleneck.
The fix is to reuse a single client across requests so that connections stay in a pool and get recycled. In Requests, you’d reach for a Session object to obtain this behavior. With HTTPX2, the persistent client is the natural way to work, and you manage it with a context manager:
reusable_client.py
import httpx2

with httpx2.Client(base_url="https://api.github.com") as client:
    first = client.get("/events")
    second = client.get(
        "/repos/python/cpython/issues",
        params={"state": "open", "per_page": 5},
    )
print(first.status_code, second.status_code)
Both requests succeed:
$ python reusable_client.py
200 200
Here, you create one httpx2.Client and issue two requests through the same client. Because the connection pool is open for the duration of the with block, the second request reuses the connection that the first one opened.
When the with block ends, the client closes its connection pool. The two responses have already been read in full at that point, so printing their status codes after the block works fine, but you can’t send any new requests through client afterward.
Notice how you pass the base_url directly to the client, so each request only needs the relative path. The params dict on the second call becomes the query string ?state=open&per_page=5 before the request is sent, so you don’t have to build that string by hand. If a value in the dict is a list or tuple instead of a single value, HTTPX2 repeats that key once per item rather than overwriting it.
You can also set default headers, including a persistent Authorization header, so that every request through this client inherits them:
auth_header.py
import httpx2

with httpx2.Client(
    base_url="https://api.github.com",
    headers={
        "Authorization": "Bearer your-token",
        "Accept": "application/vnd.github+json",
    },
) as client:
    first = client.get("/events")
    second = client.get("/repos/python/cpython")

print(first.status_code, second.status_code)
print(second.request.headers["Accept"])
The output from this code is shown below:
$ python auth_header.py
401 401
application/vnd.github+json
Both calls fail here because your-token is only a placeholder. GitHub’s API rejects any malformed or invalid bearer token outright, even on endpoints that would otherwise accept anonymous requests. The Bearer prefix identifies the token as a bearer token, the authentication scheme that most REST APIs—including GitHub’s—expect in the Authorization header.
This step is optional, since every endpoint in this tutorial works without authentication. If you’d like to try it with a real token, then you can create one by following GitHub’s authentication guide and paste it in place of your-token.
Setting headers on the client keeps your calls shorter and your credentials in a single place.
Send Data With POST
Several examples from here on use httpbin, a free service for testing HTTP clients that echoes your request back to you. It’s occasionally slow, so if an example hangs, then you can run your own copy locally with docker run -p 8080:80 kennethreitz/httpbin and point those examples at http://localhost:8080.
Sending data works much like fetching it. Pass a dictionary to json=, and HTTPX2 serializes it and sets the Content-Type header for you:
post_request.py
import httpx2

with httpx2.Client() as client:
    response = client.post(
        "https://httpbin.org/post",
        json={"title": "New issue", "body": "Found a bug"},
    )
    print(response.status_code)
    print(response.json()["json"])
The test server echoes your data back:
$ python post_request.py
200
{'body': 'Found a bug', 'title': 'New issue'}
Reach for json= whenever you’re sending structured data like this. Use data= instead when you need to send form-encoded fields, and content= for a raw string or bytes. Both skip the JSON serialization that json= handles automatically.
Scale Up With AsyncClient
When you need to make many independent requests at once, running them one after another wastes most of your application’s time waiting on the network. This is where asynchronous execution comes in, allowing you to run these requests concurrently. Async support is the main architectural improvement that HTTPX2 offers over Requests.
Python ships with the asyncio library to coordinate concurrency. You write a coroutine with async def, mark each pause point with await, and let asyncio schedule everything.
With the Requests library, going async means reaching for a separate library like aiohttp, which has a different API and paradigm for parallel HTTP requests. That introduces extra complexity into your application.
In HTTPX2, you keep the same library and the same methods. To move to async, you:
- Switch from
ClienttoAsyncClient - Add the
awaitkeyword - Use an async context manager
- Bring in the
asynciolibrary
Here’s what that looks like:
async_request.py
import asyncio

import httpx2

async def main():
    async with httpx2.AsyncClient(
        base_url="https://api.github.com"
    ) as client:
        response = await client.get("/events")
        print(response.status_code)

asyncio.run(main())
The output from this code is shown below:
$ python async_request.py
200
The shape of the code barely changed. The .get() call is the same one you’ve already used, only now you await it inside a coroutine that you run with asyncio.run().
This example only shows one request. The real advantage comes when you launch many requests at once. Because a single AsyncClient is safe to share across tasks, you can schedule them all and let them run concurrently:
fetch_all.py
import asyncio

import httpx2

async def fetch_all(paths):
    async with httpx2.AsyncClient(
        base_url="https://api.github.com"
    ) as client:
        coroutines = [client.get(path) for path in paths]
        responses = await asyncio.gather(*coroutines)
        return [response.status_code for response in responses]

paths = ["/events", "/repos/python/cpython", "/repos/psf/requests"]
print(asyncio.run(fetch_all(paths)))
All three requests come back successfully:
$ python fetch_all.py
[200, 200, 200]
Notice that there’s no await inside the list comprehension. Calling client.get() on an AsyncClient doesn’t send a request by itself. Instead, it creates a coroutine object that describes the work.
The asyncio.gather() function then schedules all of those coroutines as tasks and runs them concurrently over the shared connection pool. The * in gather(*coroutines) unpacks the list so each coroutine is passed as its own argument. If you wrote await client.get(path) inside an ordinary for loop instead, each request would finish before the next one started, and you’d be back to sequential code.
Instead of paying the network round-trip cost once per request in sequential order, you pay it approximately once for the whole batch. You then wait for all of the tasks to return before continuing.
Handle Timeouts and Errors
A request that never returns is one of the most common ways for a production service to hang forever. This is why the default timeouts matter. The Requests library defaults to no timeout at all, which lets a stalled connection block indefinitely.
HTTPX2 applies a five-second default timeout to each phase of a request instead. For reading and writing, that limit measures inactivity rather than total elapsed time, so a healthy request that keeps sending or receiving data can run for longer than five seconds, while a stalled one fails fast. This default alone prevents a whole set of production incidents.
When you need finer control, you can tune each of the four phases of the request separately with an httpx2.Timeout object:
custom_timeouts.py
import httpx2

timeout = httpx2.Timeout(connect=5.0, read=10.0, write=5.0, pool=5.0)

with httpx2.Client(timeout=timeout) as client:
    response = client.get("https://api.github.com/events")
    print(response.status_code)
The output from this code is shown below:
$ python custom_timeouts.py
200
Here, you allow five seconds to establish the connection, ten seconds of silence while reading the response, five seconds to send each piece of the request, and five seconds to acquire a connection from the pool.
As with the default, a response that keeps arriving can still take longer than ten seconds. Passing the Timeout object to the client applies that policy to every request you make through it.
The widget below shows how the default five-second policy plays out, with a separate five-second budget for each of the four phases rather than one budget for the whole request:
Timeouts are only useful if you handle them, and HTTPX2 provides a clear exception hierarchy for that. In the following example, httpx2.Timeout(5.0) applies the same five-second limit to all four phases, and each phase raises its own specific exception:
handle_errors.py
import httpx2

timeout = httpx2.Timeout(5.0)

with httpx2.Client(timeout=timeout) as client:
    try:
        response = client.get("https://api.github.com/nonexistent")
        response.raise_for_status()
    except httpx2.ConnectTimeout:
        print("Timed out while connecting to the host.")
    except httpx2.ReadTimeout:
        print("Timed out while receiving data from the host.")
    except httpx2.WriteTimeout:
        print("Timed out while sending data to the host.")
    except httpx2.PoolTimeout:
        print("Timed out waiting for a pool connection.")
    except httpx2.HTTPStatusError as error:
        print(f"Bad response: {error.response.status_code}")
    except httpx2.RequestError as error:
        print(f"A network problem occurred: {error}")
Only one of the handlers runs:
$ python handle_errors.py
Bad response: 404
This example shows the six exceptions you’ll reach for most often:
- A
ConnectTimeoutfires when HTTPX2 can’t establish a socket connection to the host within the timeout window. - A
ReadTimeoutfires when HTTPX2 doesn’t receive any data from the server within the timeout window, whether that’s the start of the response or the next chunk of the body. - A
WriteTimeoutfires when HTTPX2 doesn’t finish sending a piece of the request within the timeout window. - A
PoolTimeoutfires when no connection frees up in the pool within the timeout window. - An
HTTPStatusErrorfires when you call.raise_for_status()and the server returned a response outside the2xxrange, such as a4xxor5xxerror or a redirect you didn’t follow. That’s what happens with the404in the example above. - A
RequestErrorfires when a lower-level network problem occurs, such as a DNS failure or a refused connection. HTTPX2 raises these asConnectError, a subclass ofRequestError.
These six aren’t independent of each other, though. The four timeout exceptions all inherit from TimeoutException, which is itself a subclass of RequestError, so you can catch all four at once with a single except httpx2.TimeoutException clause when you don’t need to tell them apart. The HTTPStatusError exception sits outside that branch and inherits from HTTPError directly.
That hierarchy makes the order of the clauses above load-bearing. Python matches except clauses from top to bottom and stops at the first one that fits, so RequestError has to come last. If you move it above the four timeout clauses, then it will silently catch the timeouts first, and those handlers will never run.
Catching these six at the right level keeps a single slow or unreachable host from taking down the rest of your application.
To see a timeout fire, you can set a short timeout and send a request to an endpoint that deliberately responds slowly. This time, the example catches the TimeoutException base class, so a slow connection is handled the same way as a slow response:
timeout_fires.py
import httpx2

timeout = httpx2.Timeout(1.0)

with httpx2.Client(timeout=timeout) as client:
    try:
        client.get("https://httpbin.org/delay/3")
    except httpx2.TimeoutException:
        print("The request timed out.")
The request gives up after one second:
$ python timeout_fires.py
The request timed out.
The same exception types work inside an AsyncClient, so you don’t need a second error-handling pattern for async code. Here’s the timeout example again, rewritten to run asynchronously:
timeout_fires_async.py
import asyncio

import httpx2

async def main():
    timeout = httpx2.Timeout(1.0)
    async with httpx2.AsyncClient(timeout=timeout) as client:
        try:
            await client.get("https://httpbin.org/delay/3")
        except httpx2.TimeoutException:
            print("The request timed out.")

asyncio.run(main())
The result is the same:
$ python timeout_fires_async.py
The request timed out.
Only the async scaffolding around the try block changes:
- The code lives inside an
async deffunction. - The client is an
AsyncClient, opened withasync withinstead ofwith. - The request is awaited with
await. - The
asyncio.run()function starts the event loop that runsmain().
Stream Large Responses
Not every response you handle will be a small JSON payload like the ones you’ve seen so far. Calling .json() or reading .content pulls the entire response body into memory at once. That’s fine for small payloads, but downloading a large file or consuming a long-running streamed response this way can exhaust your available memory.
To manage your memory usage, you can stream the response and process it in chunks. You open a streaming request with the client’s .stream() method, which returns a context manager. The example below streams 100 KB of content from httpbin:
stream_download.py
import httpx2

with httpx2.Client() as client:
    with client.stream(
        "GET", "https://httpbin.org/stream-bytes/102400"
    ) as response:
        print(response.headers)
        for chunk in response.iter_bytes(chunk_size=1024):
            print(f"Received {len(chunk)} bytes")
The output from this code is shown below:
$ python stream_download.py
Headers({'date': '...', 'content-type': 'application/octet-stream', ... })
Received 1024 bytes
Received 1024 bytes
Received 1024 bytes
...
Received 1024 bytes
Inside the streaming context, the response headers are available right away, but the body isn’t downloaded until you iterate over it. Here, .iter_bytes() yields the body 1 KB at a time, so only a single chunk sits in memory at any moment.
You can choose the iterator that matches your data. Use .iter_bytes() for binary content, .iter_text() for decoded text, and .iter_lines() to process a response line by line. When you work with the AsyncClient, the same methods are available with the prefix a: .aiter_bytes(), .aiter_text(), and .aiter_lines().
Here’s the same download with an AsyncClient. To keep the output short, this version skips printing the headers:
stream_download_async.py
import asyncio

import httpx2

async def main():
    async with httpx2.AsyncClient() as client:
        async with client.stream(
            "GET", "https://httpbin.org/stream-bytes/102400"
        ) as response:
            async for chunk in response.aiter_bytes(chunk_size=1024):
                print(f"Received {len(chunk)} bytes")

asyncio.run(main())
The output shows the same chunks as before:
$ python stream_download_async.py
Received 1024 bytes
Received 1024 bytes
Received 1024 bytes
...
Received 1024 bytes
Both the client and the stream open with async with, and an async for loop over .aiter_bytes() takes the place of the regular for loop.
Upgrade to HTTP/2
Streaming changes how you process a single response. HTTP/2 tackles a different problem that takes you back to the concurrent requests you sent with AsyncClient: how many requests can share one connection at the same time.
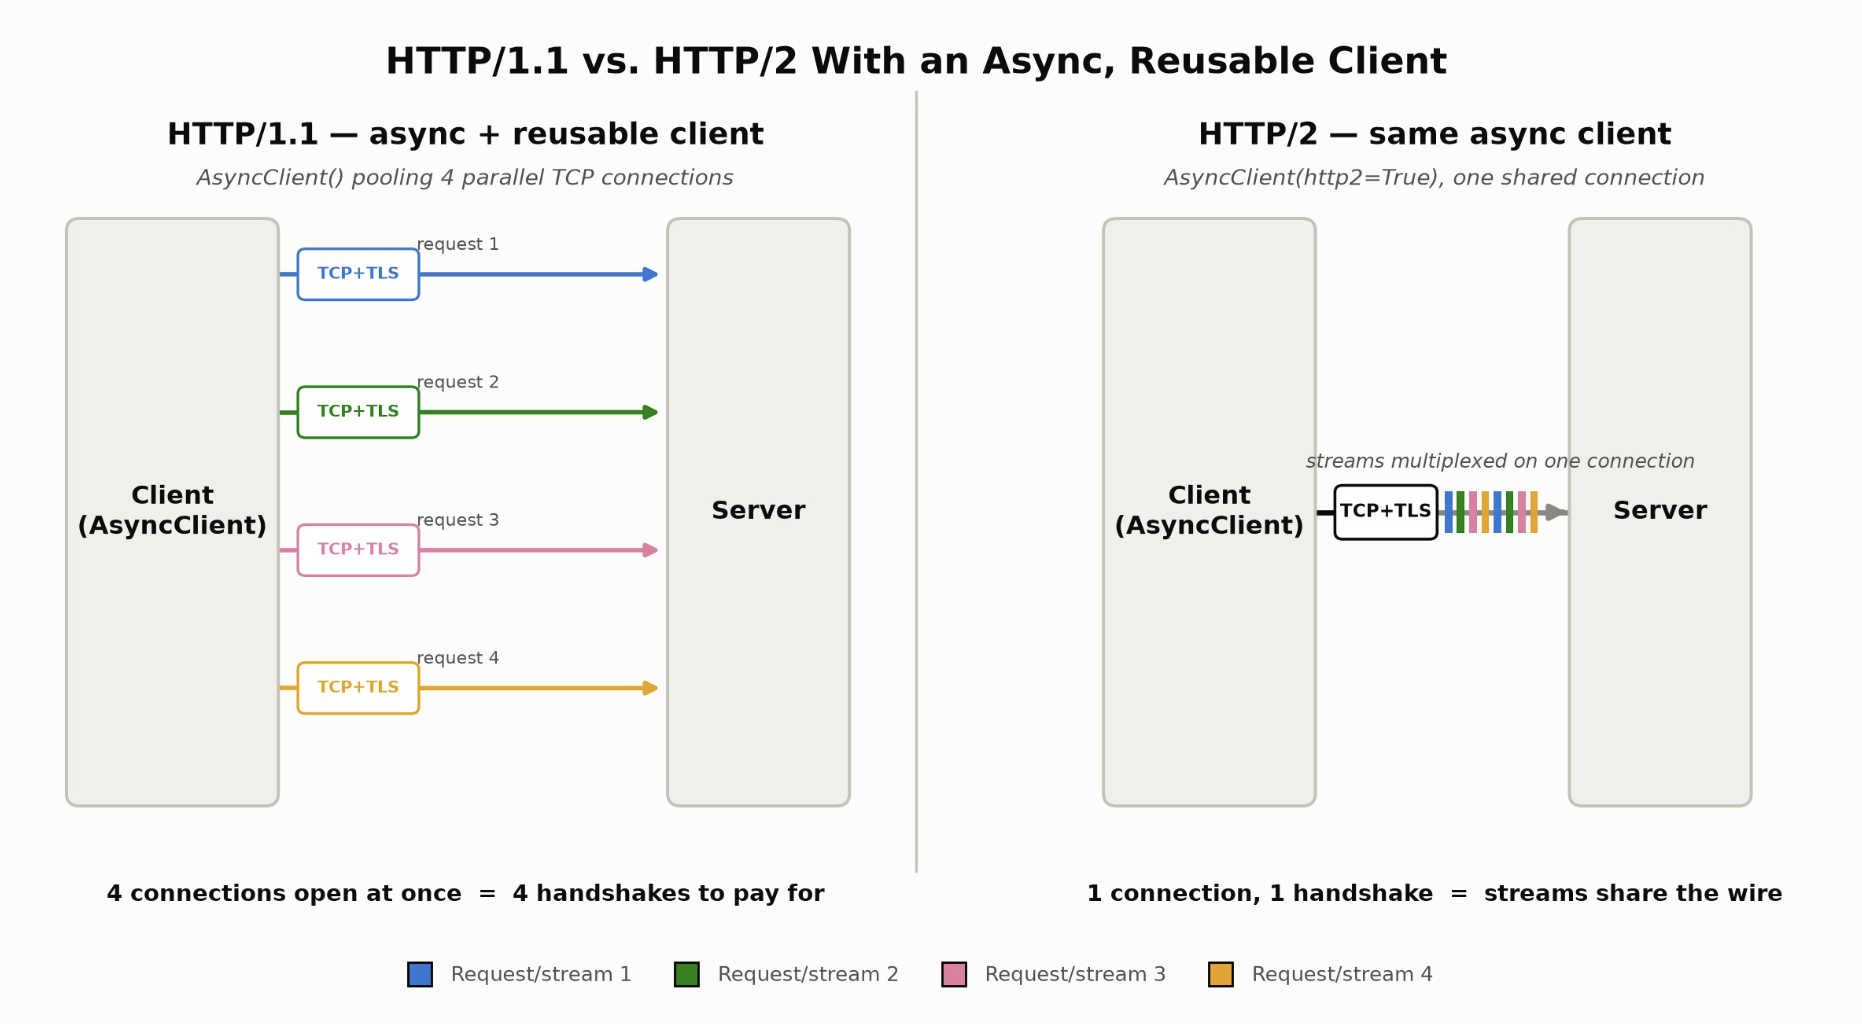
Under HTTP/1.1, your client either waits its turn on an existing connection or opens a new TCP connection and repeats the TLS handshake to keep up with your application’s traffic. That overhead multiplies with every request you send to the same host.
HTTP/2 solves this by multiplexing many requests over a single connection: your client fires them all at once, and the server answers each one independently, without making the others wait. Fewer handshakes mean less latency, and because one open connection can carry many requests, your app can scale its concurrency without opening more connections.
You may wonder why you’d need HTTP/2 when AsyncClient already sends requests concurrently. Async concurrency and HTTP/2 solve different problems: async controls how many requests your own code has in flight at once, while the protocol controls how those requests share a connection on the wire.
With an AsyncClient, that distinction plays out like this:
- On HTTP/1.1, the client still pools several parallel TCP connections, each with its own handshake, to carry your concurrent requests.
- On HTTP/2, that pool collapses into a single connection and a single handshake, with each request running independently, interleaved with the others. HTTP/2 calls these streams, but they’re unrelated to the response streaming from the previous section.
The following diagram compares how the two protocols carry those requests:
The Requests library has no way to use HTTP/2. With HTTPX2, you get it by changing one keyword argument, and every request you’ve already written keeps working exactly as it does today.
Because HTTP/2 support relies on a third-party package, you install it as an optional extra:
Once that’s in place, you enable the protocol by passing a single http2=True argument when you create the client:
http2_client.py
import httpx2

with httpx2.Client(http2=True) as client:
    response = client.get("https://api.github.com/events")
    print(response.http_version)
The response confirms which protocol the client negotiated:
$ python http2_client.py
HTTP/2
Setting http2=True tells the client to offer HTTP/2 during the TLS handshake, through a TLS extension called ALPN. The client and server agree on a protocol during that handshake, before any request is sent. The .http_version attribute reports which one they settled on, so you can confirm that HTTP/2 was actually negotiated.
Turning it on is also low-risk. If the target server doesn’t support HTTP/2, then HTTPX2 falls back to HTTP/1.1 automatically, so nothing breaks for servers that haven’t caught up yet. It isn’t free, though: you take on the extra h2 dependency, and the gains show up mainly when you’re making many concurrent requests to the same host rather than the occasional one-off call.
Choose Between HTTPX2 and Requests
You’ve now seen the features that set HTTPX2 apart, so the natural question is when to use which library. The following table summarizes the practical differences:
| Capability | Requests | HTTPX2 |
|---|---|---|
| Synchronous requests | Supported | Supported |
| Asynchronous requests | Not supported, needs aiohttp |
Supported, through AsyncClient |
| Connection pooling | Supported, through Session |
Supported, through Client |
| Default timeout | None | Five seconds |
| Following redirects | Automatic | Opt-in, with follow_redirects=True |
| HTTP/2 support | Not supported | Supported, with http2=True |
| Streaming responses | Supported | Supported, sync and async |
The takeaway isn’t that HTTPX2 wins on every line, but that it covers more ground with one consistent API. If you’re writing a short script that makes a handful of calls, then Requests remains a perfectly good choice that you may already know well.
As soon as your project needs concurrency, HTTP/2, or safer defaults out of the box, HTTPX2 lets you grow into those requirements without adopting a second HTTP library or rewriting your call sites.
Troubleshoot Common Issues
As you put these patterns into practice, a few errors tend to show up. The first appears when you enable HTTP/2 without installing the optional extra. If you followed the setup in the HTTP/2 section, then you already have the extra and won’t run into this, but here’s what happens in an environment without it:
import httpx2

httpx2.Client(http2=True)
Running this code raises an ImportError:
Traceback (most recent call last):
  ...
ImportError: Using http2=True, but the 'h2' package is not installed.
Make sure to install httpx using `pip install httpx[http2]`.
The fix is to install the extra dependency with python -m pip install "httpx2[http2]==2.13.1", which pulls in the h2 package that the protocol upgrade needs.
Note that the traceback above tells you to install httpx[http2], naming the original library rather than httpx2. That message is inherited from upstream and hasn’t been updated for the fork yet, so follow the command above instead.
Installing "httpx[http2]" does clear the error, since it brings in the same h2 package, but it also installs HTTPX itself alongside HTTPX2. The two coexist happily, but they’re separate libraries with separate exception hierarchies, so an except httpx.HTTPError left over from your old code won’t catch anything HTTPX2 raises.
The second common surprise is a timeout on a slow endpoint that used to work with Requests. Because HTTPX2 applies a five-second default, a long-running request that Requests allowed to hang will now raise an exception. The following example purposely makes a request that will take six seconds:
import httpx2

httpx2.get("https://httpbin.org/delay/6")
After five seconds, this code raises a ReadTimeout:
Traceback (most recent call last):
  ...
httpx2.ReadTimeout: The read operation timed out
If the endpoint legitimately needs more time, then raise the limit for the phase that’s timing out rather than disabling the timeout entirely. Here, that’s the read phase:
slow_endpoint.py
import httpx2

timeout = httpx2.Timeout(5.0, read=15.0)

with httpx2.Client(timeout=timeout) as client:
    response = client.get("https://httpbin.org/delay/6")
    print(response.status_code)
This time, the request completes:
$ python slow_endpoint.py
200
The first argument sets five seconds for every phase, and read=15.0 overrides only the read phase, so the six-second response now arrives in time while the other phases keep their tighter limits.
Finally, watch out for reusing a client after its with block has ended. Once the context manager closes, the connection pool is gone:
import httpx2

with httpx2.Client() as client:
    pass

client.get("https://api.github.com/events")
Running this code raises a RuntimeError:
Traceback (most recent call last):
  ...
RuntimeError: Cannot send a request, as the client has been closed.
Keep every request that shares a client inside the same with block, or create the client without a context manager and close it yourself when you’re done.
Conclusion
You’ve now built up a toolkit for modern HTTP requests in Python. Along the way, you saw how closely HTTPX2 mirrors the familiar Requests API, so most of what you already know carries over unchanged.
In this tutorial, you’ve learned how to:
- Replace one-off requests with a reusable
Clientthat pools connections - Handle concurrent requests with
AsyncClientandasyncio - Configure granular timeouts and catch errors through a clear exception hierarchy
- Stream large responses to keep your memory usage flat
- Enable HTTP/2 for faster, multiplexed connections
The next time you start a project that needs to interact with the web, you can reach for HTTPX2 with confidence.
If you want to keep going with the async side of this tutorial, Real Python’s Concurrency and Async Programming learning path brings together tutorials and video courses on async IO, thread safety, and parallel processing.
Get Your Code: Click here to download the free sample code that shows you how to make HTTP requests in Python with HTTPX2.
Frequently Asked Questions
Now that you have some experience making HTTP requests in Python, you can use the questions and answers below to check your understanding and recap what you’ve learned.
These FAQs are related to the most important concepts you’ve covered in this tutorial. Click the Show/Hide toggle beside each question to reveal the answer.
HTTPX and its fork HTTPX2 offer an API similar to that of Requests, but they add asynchronous support, HTTP/2, and a five-second default timeout. Requests handles synchronous calls only, and it waits indefinitely unless you set a timeout yourself.
HTTPX2 is a fork of HTTPX that Pydantic created in 2026 to give the project a maintained path forward. The public API is the same, so most HTTPX code moves across by changing the import.
Yes. Both HTTPX and its fork HTTPX2 provide an AsyncClient class that sends requests inside an asyncio event loop, letting many requests overlap on the wire. Each library also covers synchronous code through Client, so you don’t need a second dependency.
Yes. In both HTTPX and HTTPX2, every request gets five seconds by default, applied separately to the connect, read, write, and pool phases rather than as one total budget. You can change it by passing a Timeout object to the client.
No. To enable it, you install the optional http2 extra and pass http2=True when you create the client. The client then offers HTTP/2 during the TLS handshake and falls back to HTTP/1.1 when the server doesn’t support it.
Take the Quiz: Test your knowledge with our interactive “Python HTTPX: Making HTTP Requests With HTTPX2” quiz. You’ll receive a score upon completion to help you track your learning progress:
Interactive Quiz
Python HTTPX: Making HTTP Requests With HTTPX2Test your knowledge of Python HTTPX2 by reusing clients, sending async requests, setting timeouts, streaming responses, and enabling HTTP/2.