multimodal model
A multimodal model is a machine learning model that takes in, and sometimes produces, more than one kind of data, such as text, images, audio, and video, within a single request. Models that pair images with text are often called vision-language models (VLMs).
Most multimodal models are built around a large language model. An encoder for each extra modality, or input type, turns raw input into vectors in the same embedding space as text tokens. The language model then reads image or audio tokens and words as one sequence:
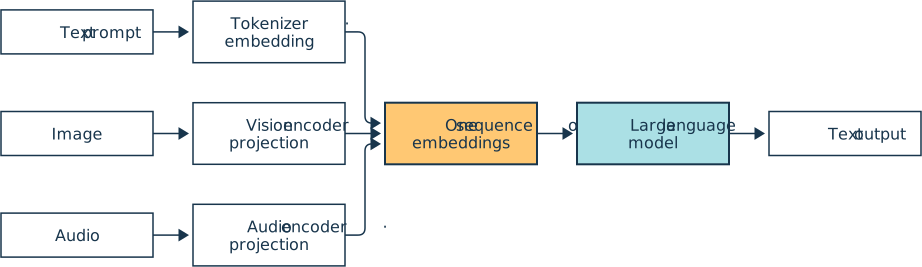
LLaVA, released in 2023, showed the simplest form of this design. It passes image features from a pretrained CLIP vision transformer through a single trainable projection into the language model’s word-embedding space. Google’s Gemini models were instead trained on interleaved text, images, audio, and video from the start.
In coding work, these models read screenshots of a user interface, error dialogs, architecture diagrams, and scanned documents. Images aren’t free, though. Each one is split into patches that count against the context window like any other tokens, and a full-screen screenshot can cost more than a thousand of them.
Small text, rotated images, counting, and precise spatial positions remain weak spots, and a model can hallucinate details that the image doesn’t contain.
Related Resources
Tutorial
Python MarkItDown: Convert Documents Into LLM-Ready Markdown
Get started with Python MarkItDown to turn PDFs, Office files, images, and URLs into clean, LLM-ready Markdown in seconds.
For additional information on related topics, take a look at the following resources:
- How to Use Ollama to Run Large Language Models Locally (Tutorial)
- How to Integrate Local LLMs With Ollama and Python (Tutorial)
- Build an LLM RAG Chatbot With LangChain (Tutorial)
- Converting Documents to Markdown With MarkItDown (Course)
- Python MarkItDown: Convert Documents Into LLM-Ready Markdown (Quiz)
- How to Use Ollama to Run Large Language Models Locally (Quiz)
- How to Get Started With Ollama (Course)
- How to Integrate Local LLMs With Ollama and Python (Quiz)
- First Steps With LangChain (Course)
- Build an LLM RAG Chatbot With LangChain (Quiz)
Have a question about this? Mentor AI can show you examples, compare related terms, and point you to tutorials.
Ask Mentor AI

By Martin Breuss • Updated Nov. 7, 2026
